動態頁面獲取
- 2020 年 3 月 30 日
- 筆記
一、反爬與反反爬
反爬措施(伺服器)
- 通過客戶端請求頭欄位來判斷是不是爬蟲。
- 通過在url中拼接加密欄位,一般通過js動態生成。
- 通過判斷一個IP在一個時間段內訪問頻率。
- 驗證碼。
- 不直接在頁面中顯示數據,通過js進行數據渲染。
反反爬措施(你)
- 封裝常用請求頭,列如:user-agent,Referer。
- 通過 js逆向,或在頁面中獲得加密欄位,。
- 使用IP池,設置爬取策略
- 驗證碼識別
- 字母驗證碼,可以通過打碼平台識別/自己識別,再輸入。
- 滑動/點擊驗證碼,可通過打碼平台識別位置後,通過selenium模擬人工滑動/點擊,進行驗證。
- js渲染可通過以下方法獲取數據
- 有些網站數據放置在js程式碼中,例如36kr。
- 通過selenium+phantomjs(無介面瀏覽器)、selenium+chrome來獲取數據
- 找到數據來源的介面(ajax介面)
- splash獲取數據。Splash是一個javascript渲染服務。。
二、ajax
1、什麼是ajax
Ajax 不是一種新的程式語言,而是一種用於創建更好更快以及交互性更強的Web應用程式的技術。
使用 JavaScript 向伺服器提出請求並處理響應而不阻塞用戶核心對象XMLHttpRequest。通過這個對象,您的 JavaScript 可在不重載頁面的情況與 Web 伺服器交換數據,即在不需要刷新頁面的情況下,就可以產生局部刷新的效果。Ajax 在瀏覽器與 Web 伺服器之間使用非同步數據傳輸(HTTP 請求),這樣就可使網頁從伺服器請求少量的資訊,而不是整個頁面。Ajax可使網際網路應用程式更小、更快,更友好。
總結下來:ajax是通過XMLHttpRequest對象,在不刷新頁面的情況下非同步發送請求,接受響應,的一種網路技術。
三、selenium與瀏覽器驅動安裝。
1、安裝 selenium 模組
pip install selenium 2、下載瀏覽器驅動並且安裝。
下載 chromedrive,首先需要查看自己的瀏覽器版本
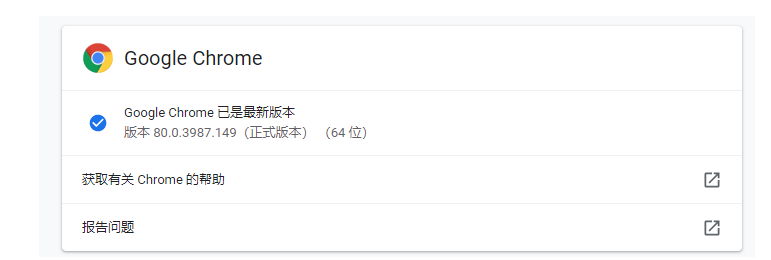
chromedrive下載地址:https://chromedriver.storage.googleapis.com/index.html?path=80.0.3987.106/
phantomjs下載地址:https://bitbucket.org/ariya/phantomjs/downloads/phantomjs-2.1.1-windows.zip
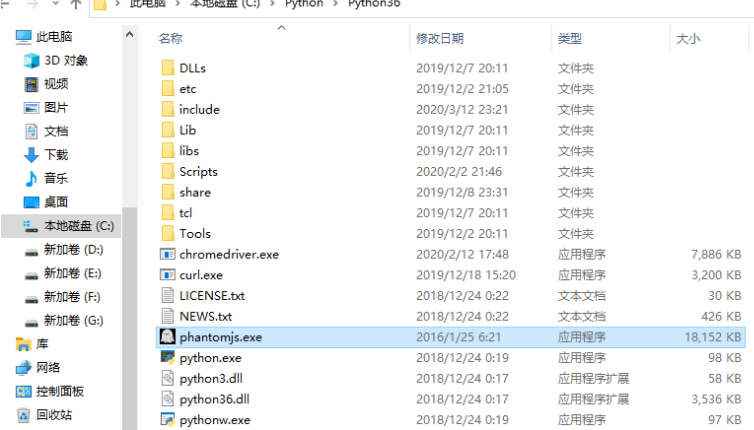
下載完成後解壓,移動到python.exe所在的目錄,你也可以進行單獨環境變數配置,不過這種方法是最簡單的
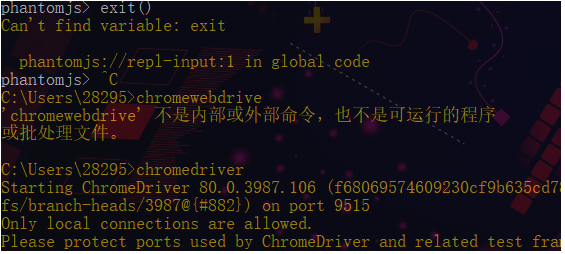
是否成功,在cmd命令行中輸入相關命令
四、selenium簡單使用
4.1、常用方法如下
from selenium import webdriver chrome = webdriver.Chrome() # 訪問url chrome.get('https://www.baidu.com') # 元素選擇 input_1 = chrome.find_element_by_id('kw') # 通過id選擇 input_2 = chrome.find_element_by_xpath("//input[@id='su']") # 通過xpath input_3 = chrome.find_element_by_css_selector('#su') # 通過css選擇器 input_4 = chrome.find_element_by_class_name('bg s_btn') # 通過類名 # 往輸入框內發送內容,並且點擊 input_1.send_keys('spider') button = chrome.find_element_by_xpath('//input[@id="su"]') # 獲取某對象的png bytes數據 content_bytes = button.screenshot_as_png # 獲取元素的位置 print(button.location) button.click() # 全螢幕截圖 chrome.save_screenshot('1.png') # 元素大小 print(button.size) chrome.close() # 關閉選項卡 chrome.close() # 退出瀏覽器 chrome.quit() 4.2、selenium提取cookies字典
from selenium import webdriver chrome = webdriver.Chrome() chrome.get('http://www.baidu.com') cookies = chrome.get_cookies() cok_dic = {i.get('name'): i.get('value') for i in cookies} print(cok_dic) chrome.close() chrome.quit() 4.3、selenium中的三種等待
程式碼執行的速度是非常快的,但是我們通過selenium+瀏覽器驅動去驅動一個瀏覽器執行某些動作,但是瀏覽器執行的速度很慢。我們進行數據提取時,瀏覽器頁面並沒有載入完畢,我們可能會提取不到數據,所以需要設置等待。
強制等待:shitime.sleep(1) #程式暫停1秒 隱式等待:chrome.implicitly_wait(5) #最多等待5秒,在5秒內,載入完成就不會報錯。 顯示等待:指定時間情況下,指定某些元素或者狀態是否載入完成。載入完成就不會報錯。 from selenium.webdriver.common.by import By #通過什麼方式判斷:id、xpath、cssselect、等 from selenium.webdriver.support.ui import WebDriverWait from selenium.webdriver.support import expected_conditions as EC next_page = WebDriverWait(self.browser, 5).until( EC.presence_of_element_located((By.XPATH, '//div[contains(@class,"paginator")]/a[last()]'))) #等待a標籤是否載入成功。 next_url = next_page.get_attribute('href') #EC這個類中提供了很多判斷條件,下面是常用判斷條件 title_is #title標籤內容是.. title_contains #title標籤包含。 presence_of_element_located #元素載入完成 visibility_of_element_located #元素可視 text_to_be_present_in_element #元素內的內容載入完成 element_to_be_clickable #元素可點擊 element_to_be_selected #元素可選擇 
五、相關案例
5.1、豆瓣圖書
from selenium import webdriver import time import random from selenium.webdriver.common.by import By from selenium.webdriver.support.ui import WebDriverWait from selenium.webdriver.support import expected_conditions as EC from lxml import etree import xlwt class Douband(): def __init__(self, kw, page): self.base_url = 'https://book.douban.com/' self.browser = webdriver.Chrome() self.page_url = '' self.kw = kw self.page = page self.cont_list = [] def get_index(self, url): self.browser.get(url) try: next_page = WebDriverWait(self.browser, 5).until( EC.presence_of_element_located((By.XPATH, '//div[contains(@class,"paginator")]/a[last()]'))) next_url = next_page.get_attribute('href') self.page_url = next_url return self.browser.page_source except Exception: self.browser.quit() def parser_index(self, content): html = etree.HTML(content) item_list = html.xpath('//div[contains(@class,"sc-bZQynM" )]') for item in item_list: title = item.xpath('.//div[@class="detail"]/div[@class="title"]/a/text()') rating = item.xpath('.//div[@class="detail"]/div[contains(@class,"rating")]/span[2]/text()') times = item.xpath('.//div[@class="detail"]/div[contains(@class,"rating")]/span[3]/text()'), info = item.xpath('.//div[@class="detail"]/div[@class="meta abstract"]/text()'), item = { 'title': title[0] if title else None, 'rating': rating[0] if rating else None, 'times': times[0] if times else None, 'info': info[0] if info else None, } print(item) self.cont_list.append(item) def search(self): self.browser.get(self.base_url) self.browser.find_element_by_id('inp-query').send_keys(self.kw) time.sleep(random.random()) self.browser.find_element_by_xpath('//div[@class="inp-btn"]/input').click() def write_to_excel(self, filename, sheetname): # 創建workbook file = xlwt.Workbook() # 添加sheet表 sheet = file.add_sheet(sheetname) # 設置表頭 head = [i for i in self.cont_list[0].keys()] for i in range(len(head)): sheet.write(0, i, head[i]) # 寫內容 i = 1 for item in self.cont_list: for j in range(len(head)): sheet.write(i, j, item[head[j]]) i += 1 # 保存 file.save(filename) print('寫入excle成功!') def run(self): self.search() count = 0 self.page_url = self.browser.current_url while count < self.page: content = self.get_index(self.page_url) self.parser_index(content) count += 1 self.browser.quit() self.write_to_excel('python.xls', 'book') if __name__ == '__main__': db = Douband('python', 10) db.run() 5.2、騰訊招聘
import requests from jsonpath import jsonpath from excle_wirte import ExcelUtils import os def get_content(url): headers = { 'user-agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/80.0.3987.149 Safari/537.36', 'referer': 'https://careers.tencent.com/search.html' } res = requests.get(url, headers=headers).json() jp = jsonpath(res, '$.*.Posts.*') print(jp) return jp def write_excel(filename, item_list, sheetname): if not os.path.exists(filename): ExcelUtils.write_to_excel(filename, item_list, sheetname) else: ExcelUtils.append_to_excel(filename, item_list) if __name__ == '__main__': base_url = 'https://careers.tencent.com/tencentcareer/api/post/Query?timestamp=1585401795646&countryId=&cityId=&bgIds=&productId=&categoryId=&parentCategoryId=&attrId=&keyword=&pageIndex={}&pageSize=20&language=zh-cn&area=cn' for i in range(1, 11): content = get_content(base_url.format(i)) write_excel('tencent.xls',content,'hr') 在這裡用到了寫入excel的一些方法,我這裡直接引用了別人封裝的方法。
import xlwt import xlrd from xlutils.copy import copy as C class ExcelUtils(object): @staticmethod def write_to_excel(filename, item_list, sheetname): try: # 創建workbook workbook = xlwt.Workbook(encoding='utf-8') # 給工作表添加sheet表單 sheet = workbook.add_sheet(sheetname) # 設置表頭 head = [] for i in item_list[0].keys(): head.append(i) # print(head) # 將表頭寫入excel for i in range(len(head)): sheet.write(0, i, head[i]) # 寫內容 i = 1 for item in item_list: for j in range(len(head)): sheet.write(i, j, item[head[j]]) i += 1 # 保存 workbook.save(filename) print('寫入excle成功!') except Exception as e: print(e) print('寫入失敗!') @staticmethod def append_to_excel(filename, item_list): # 打開excle文件 work_book = xlrd.open_workbook(filename) # 獲取工作表中的所有sheet表單名稱 sheets = work_book.sheet_names() # 獲取第一個表單 work_sheet = work_book.sheet_by_name(sheets[0]) # 獲取已經寫入的行數 old_rows = work_sheet.nrows # 獲取表頭的所有欄位 keys = work_sheet.row_values(0) # 將xlrd對象轉化成xlwt,為了寫入 new_work_book = C(work_book) # 獲取表單來添加數據 new_sheet = new_work_book.get_sheet(0) i = old_rows for item in item_list: for j in range(len(keys)): new_sheet.write(i, j, item[keys[j]]) i += 1 new_work_book.save(filename) print('追加成功!')