Okio Okio源碼分析
概述
-
okio 是一個由 square 公司開發的開源庫,它彌補了 Java.io 和 java.nio 的不足,能夠更方便快速的讀取、存儲和處理數據。
-
okio 有自己的流類型 Source 和 Sink,對應於 java.io 的 InputStream 和 OutputStream。
-
okio 內部引入了 ByteString 和 Buffer,提升了效率和性能。
-
okio 引入了超時機制。
- okio 規模不大,程式碼精巧,是源碼學習的好素材
流(Stream)
是指在電腦的輸入輸出操作中各部件之間的數據流動。按照數據的傳輸方向,流可分為輸入流與輸出流。Java語言里的流序列中的數據既可以是未經加工的原始二進位數據,也可以是經過一定編碼處理後符合某種特定格式的數據。
1.輸入輸出流
在Java中,把不同類型的輸入輸出源抽象為流,其中輸入和輸出的數據稱為數據流(Data Stream)。數據流是Java程式發送和接收數據的一個通道,數據流中包括輸入流(Input Stream)和輸出流(Output Stream)。通常應用程式中使用輸入流讀出數據,輸出流寫入數據。 流式輸入、輸出的特點是數據的獲取和發送均沿數據序列順序進行。相對於程式來說,輸出流是往存儲介質或數據通道寫入數據,而輸入流是從存儲介質或數據通道中讀取數據,一般來說關於流的特性有下面幾點:
-
先進先出,最先寫入輸出流的數據最先被輸入流讀取到。
-
順序存取,可以一個接一個地往流中寫入一串位元組,讀出時也將按寫入順序讀取一串位元組,不能隨機訪問中間的數據。
-
只讀或只寫,每個流只能是輸入流或輸出流的一種,不能同時具備兩個功能,在一個數據傳輸通道中,如果既要寫入數據,又要讀取數據,則要分別提供兩個流。
2.緩衝流
為了提高數據的傳輸效率,引入了緩衝流(Buffered Stream)的概念,即為一個流配備一個緩衝區(Buffer),一個緩衝區就是專門用於傳送數據的一塊記憶體。
當向一個緩衝流寫入數據時,系統將數據發送到緩衝區,而不是直接發送到外部設備。緩衝區自動記錄數據,當緩衝區滿時,系統將數據全部發送到相應的外部設備。當從一個緩衝流中讀取數據時,系統實際是從緩衝區中讀取數據,當緩衝區為空時,系統就會從相關外部設備自動讀取數據,並讀取儘可能多的數據填滿緩衝區。 使用數據流來處理輸入輸出的目的是使程式的輸入輸出操作獨立於相關設備,由於程式不需關注具體設備實現的細節(具體細節由系統處理),所以對於各種輸入輸出設備,只要針對流做處理即可,不需修改源程式,從而增強了程式的可移植性。
Okio 關鍵類介紹
ByteStrings and Buffers
Okio 是圍繞這兩種類型構建的,它們將大量功能打包到一個簡單的 API 中:
ByteString是不可變的位元組序列。對於字元數據,最基本的就是String。而ByteString就像是String的兄弟一般,它使得將二進位數據作為一個變數值變得容易。這個類很聰明:它知道如何將自己編碼和解碼為十六進位、base64 和 utf-8。
Buffer是一個可變的位元組序列。像 Arraylist 一樣,你不需要預先設置緩衝區的大小。你可以將緩衝區讀寫為一個隊列:將數據寫到隊尾,然後從隊頭讀取。在內部,
ByteString和Buffer做了一些聰明的事情來節省CPU和記憶體。如果您將UTF-8字元串編碼為ByteString,它會快取對該字元串的引用,這樣,如果您稍後對其進行解碼,就不需要做任何工作。
Buffer是作為片段的鏈表實現的。當您將數據從一個緩衝區移動到另一個緩衝區時,它會重新分配片段的持有關係,而不是跨片段複製數據。這對多執行緒特別有用:與網路交互的子執行緒可以與工作執行緒交換數據,而無需任何複製或多餘的操作。
Sources and Sinks
java.io設計的一個優雅部分是如何對流進行分層來處理加密和壓縮等轉換。Okio 有自己的 stream 類型:Source和Sink,分別類似於 java 的Inputstream和Outputstream,但是有一些關鍵區別:
超時(Timeouts)。流提供了對底層 I/O 超時機制的訪問。與
java.io的 socket 字流不同,read()和write()方法都給予超時機制。易於實施。
source只聲明了三個方法:read()、close()和timeout()。沒有像available()或單位元組讀取這樣會導致正確性和性能意外的危險操作。使用方便。雖然
source和sink的實現只有三種方法可寫,但是調用方可以實現Bufferedsource和Bufferedsink介面, 這兩個介面提供了豐富API能夠滿足你所需的一切。位元組流和字元流之間沒有人為的區別。都是數據。你可以以位元組、UTF-8 字元串、big-endian 的32位整數、little-endian 的短整數等任何你想要的形式進行讀寫;不再有
InputStreamReader!易於測試。
Buffer類同時實現了BufferedSource和BufferedSink介面,即是 source 也是 sink,因此測試程式碼簡單明了。Sources 和 Sinks 分別與
InputStream和OutputStream交互操作。你可以將任何Source看做InputStream,也可以將任何InputStream當做Source。對於Sink和Outputstream也是如此。
Segment
Segment在 Okio 中作為數據緩衝的載體,一個 Segment 的數據緩衝大小為 8192,即 8k。每一個 Segment 都有前驅和後繼結點,也就是說 Sement 是一個雙向鏈錶鏈表,準確的來說是一個雙向循環鏈表。讀取數據從 Segment 頭結點讀取,寫數據從 Segment 尾結點寫。
Okio 中引入池的概念也就是源碼中SegmentPool的實現。SegmentPool 負責 Segment 創建和銷毀,SegmentPool 最大可以快取 8 個 Segment。
SegmentPool 是一個靜態方法,因此也就是全局快取只有 64 kb;
整體設計
前面說了介紹了很多關鍵的類,下面看下 Okio 的整體設計:
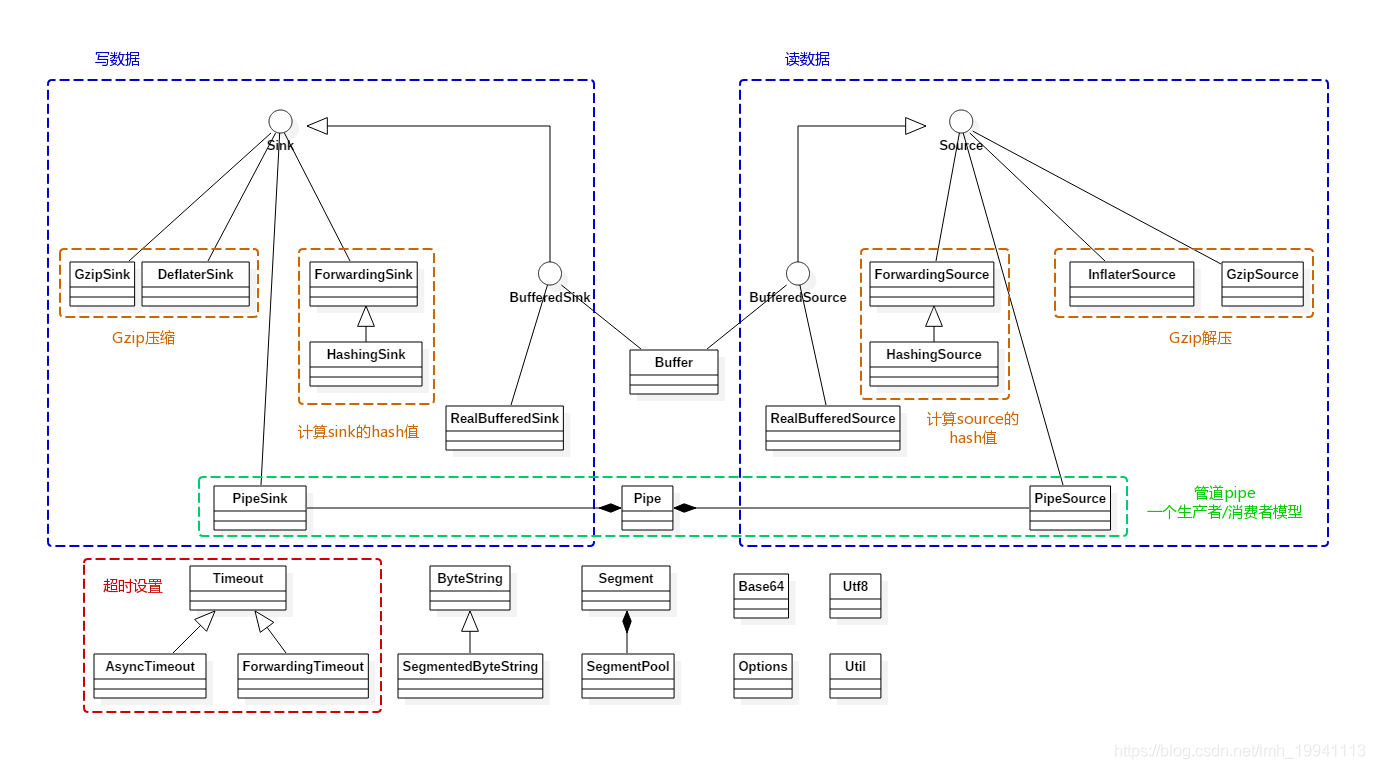 圖片摘自 Okio源碼分析
Okio 讀寫流程
在介紹 Okio 的讀寫流程的時候,還是得提一下一個關鍵的類:Okio。
Okio 類是工具類,內部提供了很多靜態方法,方便大家調用,減少大家寫了很多重複的程式碼,使得整個調用變得更加簡單。
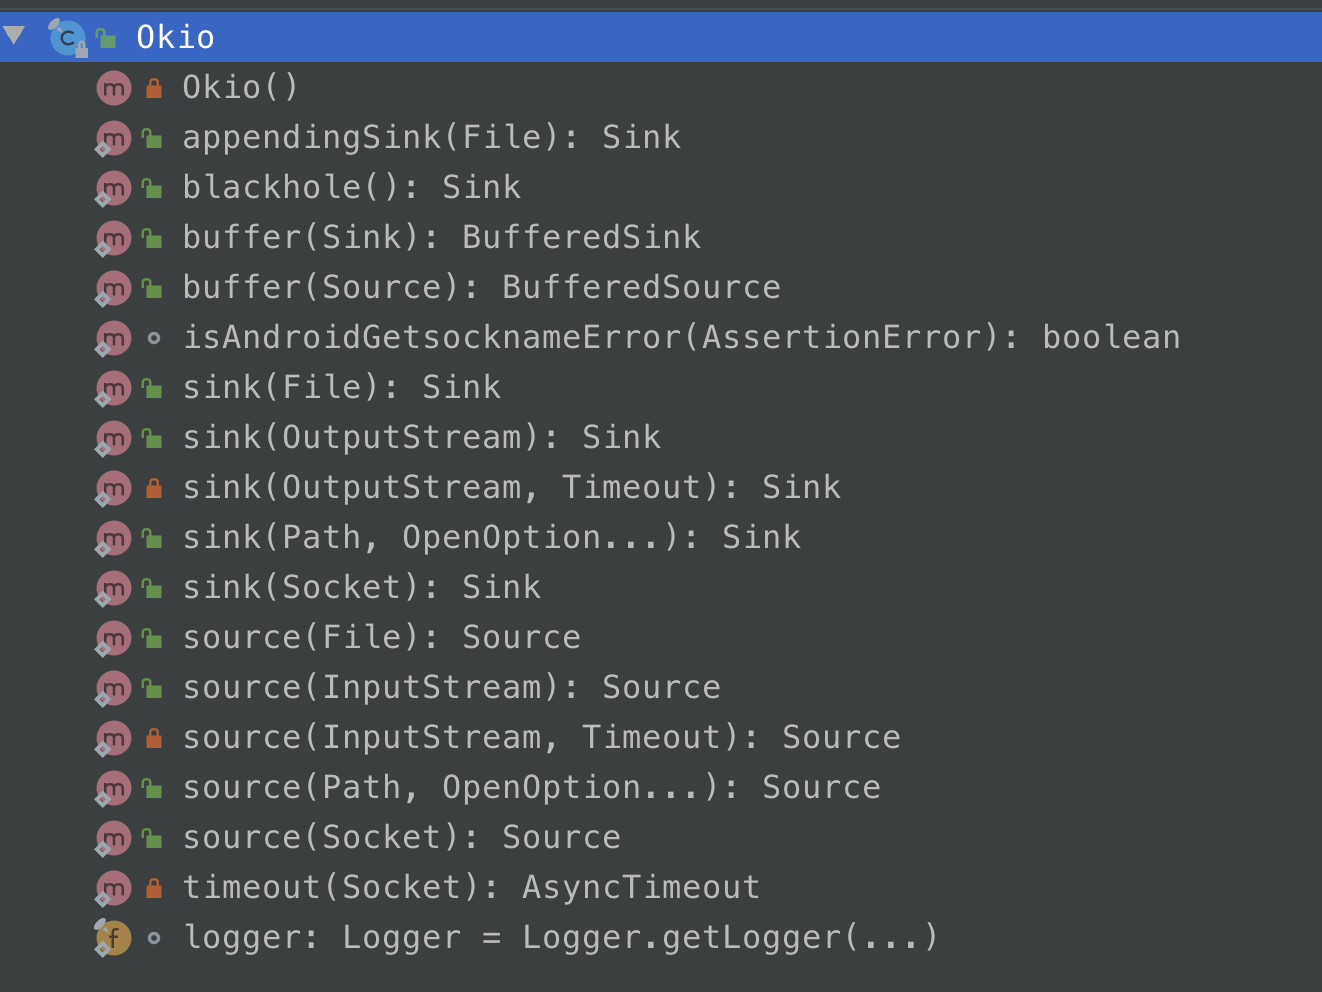
讀文本文件
 public void readLines(File file) throws IOException {
      Source fileSource = Okio.source(file);
      BufferedSource bufferedSource = Okio.buffer(fileSource);
      for (String line; (line = bufferedSource.readUtf8Line()) != null; ) {
          System.out.println(line);
      }
      bufferedSource.close();
  }
這個示例程式碼是用來讀取文本文件的,Okio 通過 Okio.source(File) 的方式來讀取文件流,它返回的是一個 Source 對象,但是 Source 對象的方法是比較少的(只有3個),因此 Okio 提供了一個裝飾者對象介面 BufferedSource,通過 Okio.buffer(fileSource) 來生成,這個方法內部實際會生成一個 RealBufferedSource 類對象,RealBufferedSource 內部持有Buffer緩衝對象可使 IO 速度更快,該類實現了BufferedSource介面,而 BufferedSource 介面提供了大量豐富的介面方法:
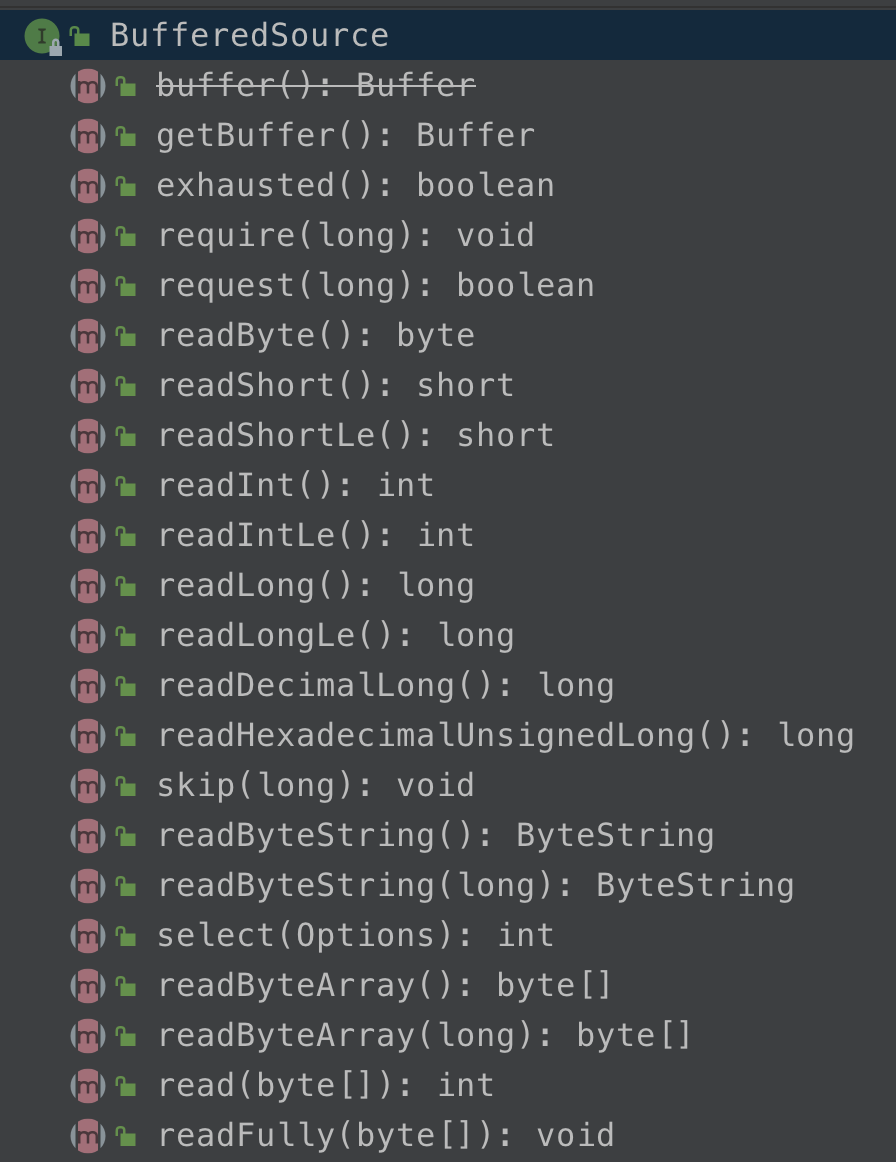
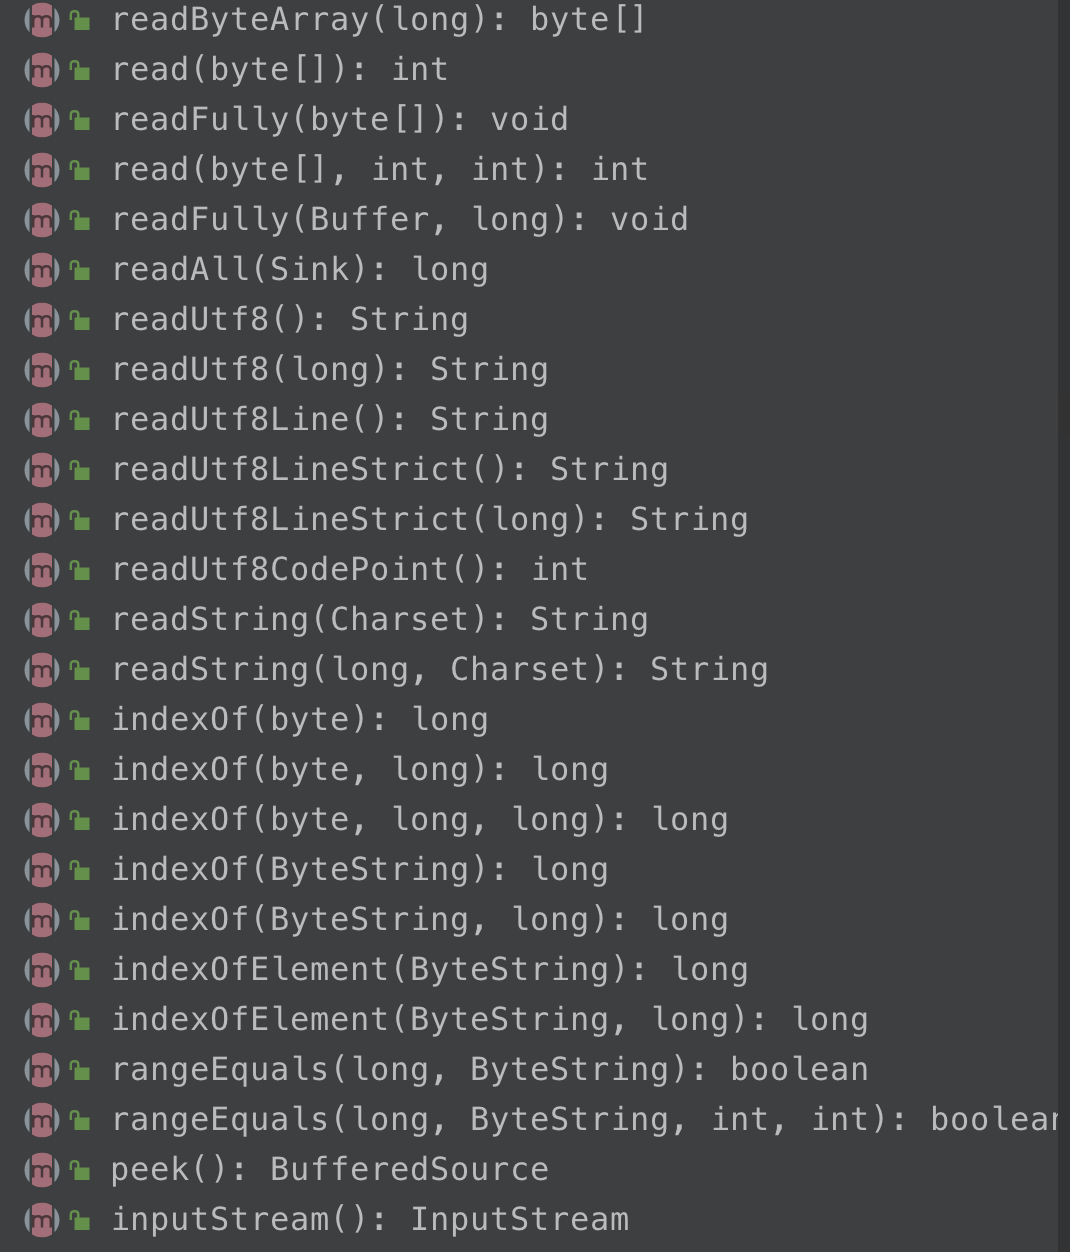
可以看到,幾乎你想從輸入流中讀取任何的數據類型都可以,而不需要你自己去轉換,可以說是非常強大而且人性化了,除了 read 方法以外,還有一些別的方法,可以說幾乎可以滿足很多需求。
在上面的示例程式碼中,打開輸入流對象的方法需要負責關閉對象資源,調用 close 方法,Okio 官方推薦使用 java 的 try-with-source 語法,上面示例程式碼可以寫成下面這樣:
public void readLines(File file) throws IOException {
      try (BufferedSource bufferedSource = Okio.buffer(Okio.source(file))) {
           for (String line; (line = bufferedSource.readUtf8Line()) != null; ) {
              System.out.println(line);
           }
      }
  }
try-with-source 是 jdk1.4 開始提供的語法糖,在 try 語句 () 裡面的資源對象,jdk 最終會自動調用它的 close 方法去關閉它, 即便 try 里有多個資源對象也是可以的,這樣就不用你手動去關閉資源了。但是在 android 裡面使用的話,會提示你要求 API level 最低為 19 才可以。
寫文本文件
public void writeEnv(File file) throws IOException {
  try (BufferedSink sink = Okio.buffer(Okio.sink(file))) {
       sink.writeUtf8("啊啊啊")
             .writeUtf8("=")
          .writeUtf8("aaa")
          .writeUtf8("\n");
  }
}
其中 Okio.buffer(fileSink) 內部返回的實現對象是一個 RealBufferedSink 類的對象, 跟 RealBufferedSource一 樣它也是一個裝飾者對象,具備 Buffer 緩衝功能。
類似於讀文件使用 Source 和 BufferedSource, 寫文件的話,則是使用的 Sink 和 BufferedSink,同樣的在 BufferedSink 介面中也提供了豐富的介面方法,這裡就不展開了,具體可以查看程式碼。
此處再次強烈建議去閱讀官方文檔://square.github.io/okio/ 。
源碼分析
通過上面的介紹,大家對 Okio 的讀取有了一個基本的了解。下面開始進入源碼分析,深入去研究其實現,再介紹源碼的時候,會先對一些介面做一些簡單的介紹。
Source & Sink
public interface Sink extends Closeable, Flushable {
  /** Removes {@code byteCount} bytes from {@code source} and appends them to this. */  從 source 中獲取到的數據添加到 sink 自身
  void write(Buffer source, long byteCount) throws IOException;

  /** Pushes all buffered bytes to their final destination. */
  @Override void flush() throws IOException;

  /** Returns the timeout for this sink. */
  Timeout timeout();

  @Override void close() throws IOException;
}

public interface Source extends Closeable {
  /**
   * Removes at least 1, and up to {@code byteCount} bytes from this and appends
   * them to {@code sink}. Returns the number of bytes read, or -1 if this
   * source is exhausted.  將自身數據給 sink
   */
  long read(Buffer sink, long byteCount) throws IOException;

  /** Returns the timeout for this source. */
  Timeout timeout();

   */
  @Override void close() throws IOException;
}
這兩個是 Okio 中最基本的兩個介面,分別對應 java 的 InputStream 和 OutputStream 即輸入流和輸出流,Source 是輸入流,Sink 是輸出流。介面提供的方法也是非常簡單,大家一看就知道這幾個方法的目的。
BufferedSink & BufferedSource
上面 Source和 Sink 提供了極簡的介面,接著作者對這兩個介面進行豐富的擴展。具體介面方法上文已介紹,這裡也不在展開。
這裡簡單提一點,這種設計風格是值得我們去學習的,設計介面的時候要簡單,專一。然後可以再新建一個介面,去豐富擴展其功能。這樣使用者可以選擇自己想要的介面來進行實現。
RealBufferedSource & RealBufferedSink
在我們通過 Okio.source() 和 Okio.sink() 獲取了 Souce 和 Sink 對象後,一般不會直接使用,而是會再調用一次 Okio.buffer() 生成一個實現 BufferedSource 和 BufferedSink 介面的對象:
  /**
   * Returns a new source that buffers reads from {@code source}. The returned
   * source will perform bulk reads into its in-memory buffer. Use this wherever
   * you read a source to get an ergonomic and efficient access to data.
   */
  public static BufferedSource buffer(Source source) {
    return new RealBufferedSource(source);
  }

  /**
   * Returns a new sink that buffers writes to {@code sink}. The returned sink
   * will batch writes to {@code sink}. Use this wherever you write to a sink to
   * get an ergonomic and efficient access to data.
   */
  public static BufferedSink buffer(Sink sink) {
    return new RealBufferedSink(sink);
  }
內部分別返回的是 RealBufferedSource 和 RealBufferedSink 對象,他們分別實現了 BufferedSource 和BufferedSink介面,而這兩個介面則是分別繼承了 Source 和 Sink 介面的並基礎上進行了方法擴展,提供了豐富的讀寫介面方法,幾乎可以對各種基礎數據類型進行讀寫。
Segment 及 SegmentPool
Segment 是 Okio 中非常重要的一環,它可以說是 Buffer 中數據的載體。容量是 8kb,頭結點為 head。
final class Segment {
  //Segment的容量,最大為8kb
  static final int SIZE = 8192;

  //如果Segment中位元組數 > SHARE_MINIMUM時(大Segment),就可以共享,不能添加到SegmentPool
  static final int SHARE_MINIMUM = 1024;
  //存儲的數據
  final byte[] data;

  //下一次讀取的開始位置
  int pos;

 //寫入的開始位置
  int limit;

  //當前Segment是否可以共享
  boolean shared;

  //data是否僅當前Segment獨有,不share
  boolean owner;

  //後繼節點
  Segment next;

  //前驅節點
  Segment prev;

  ...

  //移除當前Segment
  public final @Nullable Segment pop() {
    Segment result = next != this ? next : null;
    prev.next = next;
    next.prev = prev;
    next = null;
    prev = null;
    return result;
  }

  //在當前節點後添加一個新的節點
  public final Segment push(Segment segment) {
    segment.prev = this;
    segment.next = next;
    next.prev = segment;
    next = segment;
    return segment;
  }

  //將當前Segment分裂成2個Segment結點。前面結點pos~limit數據範圍是[pos..pos+byteCount),後面結點pos~limit數據範圍是[pos+byteCount..limit)
  public final Segment split(int byteCount) {
    if (byteCount <= 0 || byteCount > limit - pos) throw new IllegalArgumentException();
    Segment prefix;

    //如果位元組數大於SHARE_MINIMUM則拆分成共享節點
    if (byteCount >= SHARE_MINIMUM) {
      prefix = sharedCopy();
    } else {
      prefix = SegmentPool.take();
      System.arraycopy(data, pos, prefix.data, 0, byteCount);
    }

    prefix.limit = prefix.pos + byteCount;
    pos += byteCount;
    prev.push(prefix);
    return prefix;
  }

  //當前Segment結點和prev前驅結點合併成一個Segment,統一合併到prev,然後當前Segment結點從雙向鏈表移除並添加到SegmentPool復用。當然合併的前提是:2個Segment的位元組總和不超過8K。合併後可能會移動pos、limit
  public final void compact() {
    if (prev == this) throw new IllegalStateException();
    if (!prev.owner) return; // Cannot compact: prev isn't writable.
    int byteCount = limit - pos;
    int availableByteCount = SIZE - prev.limit + (prev.shared ? 0 : prev.pos);
    if (byteCount > availableByteCount) return; // Cannot compact: not enough writable space.
    writeTo(prev, byteCount);
    pop();
    SegmentPool.recycle(this);
  }

  //從當前節點移動byteCount個位元組到sink中
  public final void writeTo(Segment sink, int byteCount) {
    if (!sink.owner) throw new IllegalArgumentException();
    if (sink.limit + byteCount > SIZE) {
      // We can't fit byteCount bytes at the sink's current position. Shift sink first.
      if (sink.shared) throw new IllegalArgumentException();
      if (sink.limit + byteCount - sink.pos > SIZE) throw new IllegalArgumentException();
      System.arraycopy(sink.data, sink.pos, sink.data, 0, sink.limit - sink.pos);
      sink.limit -= sink.pos;
      sink.pos = 0;
    }

    System.arraycopy(data, pos, sink.data, sink.limit, byteCount);
    sink.limit += byteCount;
    pos += byteCount;
  }
}
SegmentPool 是一個 Segment 池,內部維護了一個 Segment 單向鏈表,容量為64kb(8 個 Segment),回收不用的 Segment 對象。
final class SegmentPool {
    //SegmentPool的最大容量
    static final long MAX_SIZE = 64 * 1024; // 64 KiB.

    //後繼節點
    static Segment next;

    //當前池內的總位元組數
    static long byteCount;

    private SegmentPool() {
    }
    //從池中獲取一個Segment對象
    static Segment take() {
        synchronized (SegmentPool.class) {
            if (next != null) {
                Segment result = next;
                next = result.next;
                result.next = null;
                byteCount -= Segment.SIZE;
                return result;
            }
        }
        return new Segment(); // Pool is empty. Don't zero-fill while holding a lock.
    }
    //將Segment狀態初始化並放入池中
    static void recycle(Segment segment) {
        if (segment.next != null || segment.prev != null) throw new IllegalArgumentException();
        if (segment.shared) return; // This segment cannot be recycled.
        synchronized (SegmentPool.class) {
            if (byteCount + Segment.SIZE > MAX_SIZE) return; // Pool is full.
            byteCount += Segment.SIZE;
            segment.next = next;
            segment.pos = segment.limit = 0;
            next = segment;
        }
    }
}
SegmentPool 可以理解為一個快取Segment的池,它只有兩個方法,一個 take(),一個 recycle(),在 SegmentPool 中維護的是一個 Segment 的單鏈表,並且它的最大值為 MAX_SIZE = 64 * 1024 也就是 64kb 即 8 個 Segment 的長度,next 就是單鏈表中的頭結點。
take() 方法的作用是取出單鏈表的頭結點 Segment 對象,然後將取出的對象與鏈表斷開並將鏈表往後移動一個單位,如果是第一次調用 take, next 為 null, 則會直接 new 一個 Segment 對象返回,並且這裡創建的Segment是不共享的。
recycle() 方法的作用則是回收一個 Segment 對象,被回收的 Segment 對象將會被插入到 SegmentPool 中的單鏈表的頭部,以便後面繼續復用,並且這裡源碼我們也可以看到如果是 shared 的對象是不處理的,如果是第一次調用 recycle() 方法則鏈表會由空變為擁有一個節點的鏈表, 每次回收就會插入一個到表頭,直到超過最大容量。
Buffer
如果你只看 Segment 的話還是很難理解整個數據的讀寫流程,因為你只知道它是能夠形成一個鏈表的東西,但是當你看完 Buffer 之後完整的流程就會清晰多了。
Buffer 類是 Okio 中最核心並且最豐富的類了,前面分析發現最終的 Source 和 Sink 實現對象中,都是通過該類完成讀寫操作,而 Buffer 類同時實現了 BufferedSource 和 BufferedSink 介面,因此 Buffer 具備 Okio 中的讀和寫的所有方法,所以這個類的方法超多!我們只找一個讀和寫的方法來看一下實現好了。
寫byte[]操作:
    @Override
    public Buffer write(byte[] source, int offset, int byteCount) {
        if (source == null) throw new IllegalArgumentException("source == null");
        // 檢測參數的合法性
        checkOffsetAndCount(source.length, offset, byteCount);

        // 計算 source 要寫入的最後一個位元組的 index 值
        int limit = offset + byteCount;
        while (offset < limit) {
            // 獲取循環鏈表尾部的一個 Segment
            Segment tail = writableSegment(1);
            // 計算最多可寫入的位元組
            int toCopy = Math.min(limit - offset, Segment.SIZE - tail.limit);
            // 把 source 複製到 data 中
            System.arraycopy(source, offset, tail.data, tail.limit, toCopy);
            // 調整寫入的起始位置
            offset += toCopy;
            // 調整尾部Segment 的 limit 位置
            tail.limit += toCopy;
        }
        // 調整 Buffer 的 size 大小
        size += byteCount;
        return this;
    }
寫操作內部是調用 System.arraycopy 進行位元組數組的複製,這裡是寫到 tail 對象,也就是循環鏈表的鏈尾 Segment 對象當中,而且這裡會不斷循環的獲取鏈尾 Segment 對象進行寫入。
看一下獲取鏈尾的方法:
  /**
   * Returns a tail segment that we can write at least {@code minimumCapacity}
   * bytes to, creating it if necessary.
   */
  Segment writableSegment(int minimumCapacity) {
    if (minimumCapacity < 1 || minimumCapacity > Segment.SIZE) throw new IllegalArgumentException();

    // 如果鏈表的頭指針為null,就會SegmentPool中取出一個
    if (head == null) {
      head = SegmentPool.take(); // Acquire a first segment.
      return head.next = head.prev = head;
    }

    // 獲取前驅結點,也就是尾部結點
    Segment tail = head.prev;
    // 如果能寫的位元組數限制超過了8192,或者不是擁有者
    if (tail.limit + minimumCapacity > Segment.SIZE || !tail.owner) {
        // 從SegmentPool中獲取一個Segment,插入到循環雙鏈表當前結點的後面
      tail = tail.push(SegmentPool.take()); // Append a new empty segment to fill up.
    }
    return tail;
  }
這裡有個 head 對象,就是 Segment 鏈表的頭結點的引用,這個方法中可以看到如果寫的時候頭結點head為空,則會調用 SegmentPool.take() 方法從Segment池中獲取一個 Segment快取對象,並以此形成一個雙向鏈表的初始節點:
    if (head == null) {
      head = SegmentPool.take(); // Acquire a first segment.
      return head.next = head.prev = head;
    }
這時Segment中會形成下面這樣的初始鏈表: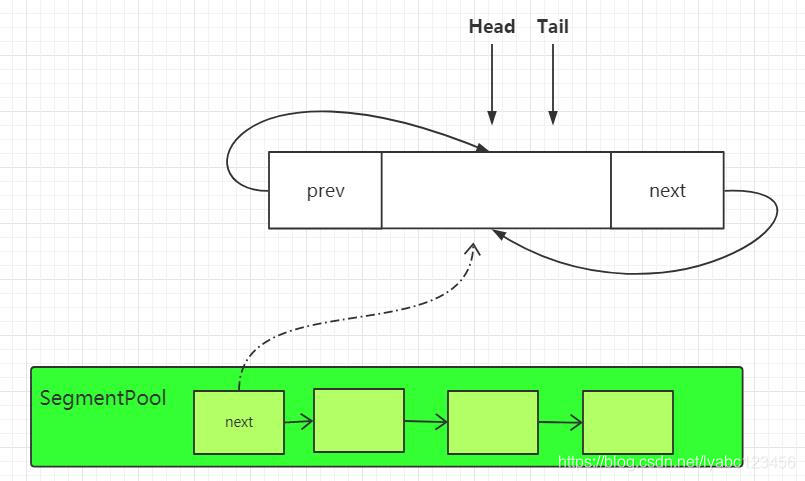
這時頭結點和尾節點其實是同一個節點,然後取得 head.prev 也就是 tail 尾節點返回,但是如果此時 tail 能寫的位元組數限制超過了 8k 或者尾節點不是 data 的擁有者,就會調用tail.push(SegmentPool.take()); 也就是再調用一次 SegmentPool.take() 取到 Segment 池中下一個 Segment. 通過 tail. push() 方法插入到循環鏈表的尾部。這時 Segment 中的鏈表會變成下面這樣: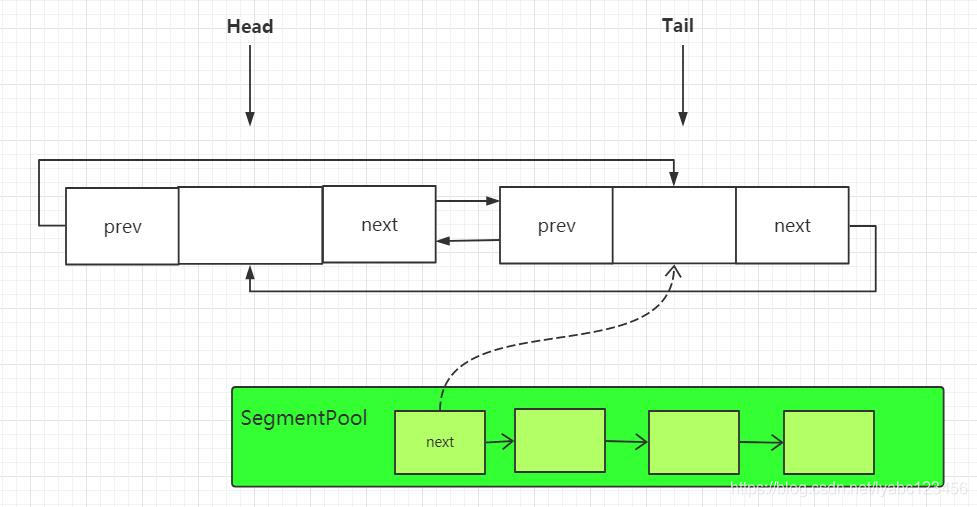
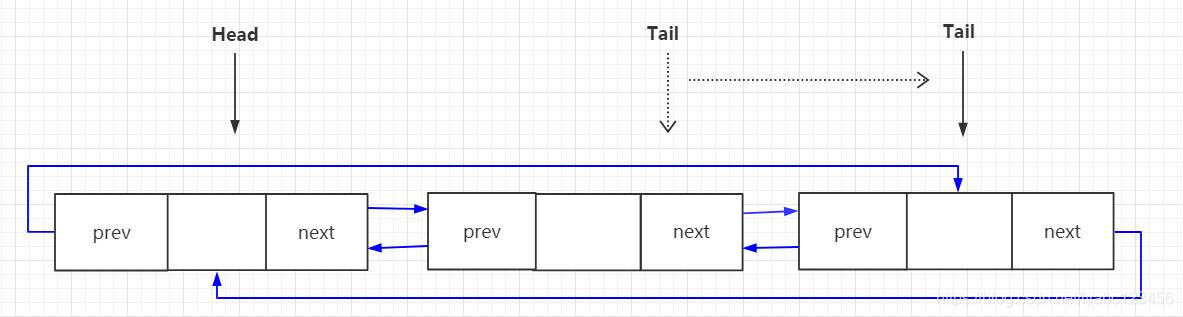
此時插入的節點會作為新的tail節點返回,下一次獲取尾節點的時候就會取到它,每當 tail 進行 push 一次,就會將新 push 的節點作為新的尾節點:
讀byte[]操作:
  @Override
  public int read(byte[] sink, int offset, int byteCount) {
    checkOffsetAndCount(sink.length, offset, byteCount);
    //取到Segment循環鏈表的表頭
    Segment s = head;
    if (s == null) return -1;
    // 計算最多可寫入的位元組
    int toCopy = Math.min(byteCount, s.limit - s.pos);
    //將數據拷貝到鏈頭的data位元組數組當中
    System.arraycopy(s.data, s.pos, sink, offset, toCopy);

    //調整鏈頭的data數組的起始postion和Buffer的size
    s.pos += toCopy;
    size -= toCopy;
    //pos等於limit的時候,從循環鏈表中移除該Segment並從SegmentPool中回收復用
    if (s.pos == s.limit) {
      head = s.pop();//移除的同時返回下一個Segment作為表頭
      SegmentPool.recycle(s);
    }

    return toCopy;
  }
讀操作內部也是調用 System.arraycopy 進行位元組數組的複製,這裡是直接對 head 頭結點進行讀取,也就是說 Buffer 在每次讀數據的時候都是從鏈表的頭部進行讀取的,如果讀取的頭結點的 pos 等於 limit, 這裡就會調用 s.pop() 將頭節點從鏈表中刪除,並返回下一個節點作為新的頭結點引用,然後將刪除的節點通過 SegmentPool.recycle(s) 進行回收復用。這時鏈表中的變化如下: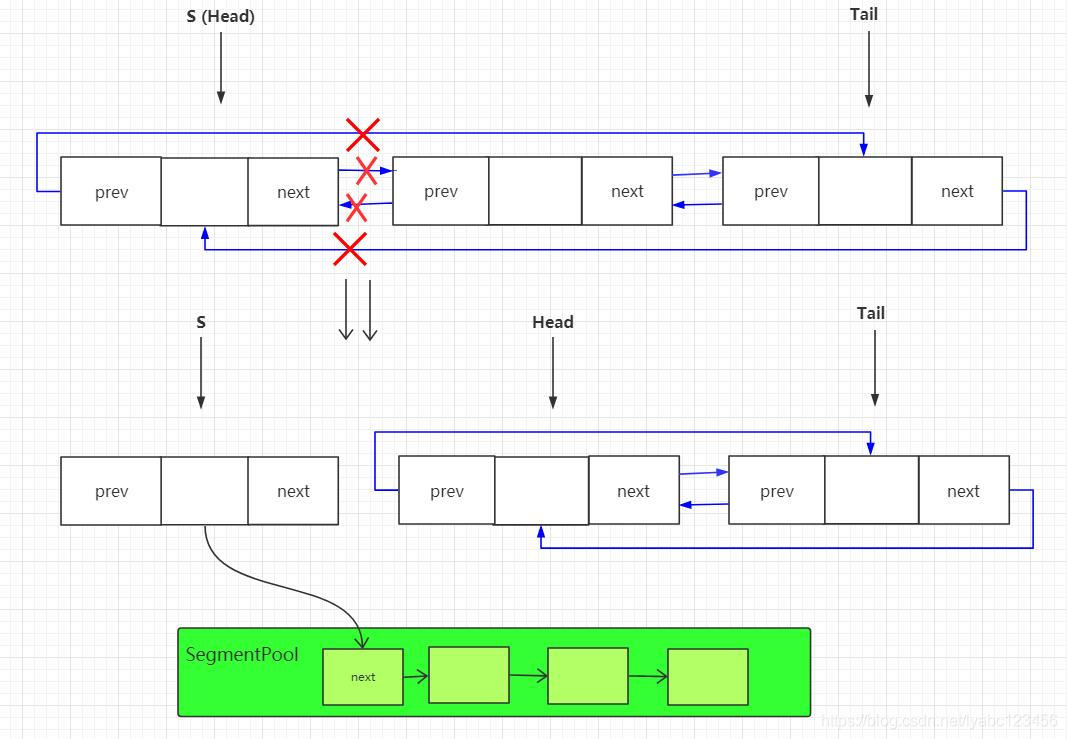
以上是讀寫位元組數據的過程,讀取其它數據類型如 int、long、String,過程類似,所以簡單的概括 Buffer 中讀的過程就是不斷取頭結點的過程,而寫的過程就是不斷取尾節點的過程。
Buffer 除了讀寫基礎數據以外,還有一個比較重要的功能就是 Buffer 之間的數據交換, 還記得在官方對 Buffer 的介紹中寫到的:
當您將數據從一個緩衝區移動到另一個緩衝區時,它會重新分配片段的持有關係,而不是跨片段複製數據。這對多執行緒特別有用:與網路交互的子執行緒可以與工作執行緒交換數據,而無需任何複製或多餘的操作。
這裡說在 Buffer 緩衝區之間移動數據的時候,是重新分配片段也就是 Segment 的持有關係,而不是跨片段的複製數據,那麼它說的這個比較牛逼的過程是如何實現的呢, 來看一下實現的方法:
@Override
public void write(Buffer source, long byteCount) {
    // Move bytes from the head of the source buffer to the tail of this buffer
    // while balancing two conflicting goals: don't waste CPU and don't waste
    // memory.
    //
    //
    // Don't waste CPU (ie. don't copy data around).
    //
    // Copying large amounts of data is expensive. Instead, we prefer to
    // reassign entire segments from one buffer to the other.
    //
    //
    // Don't waste memory.
    //
    // As an invariant, adjacent pairs of segments in a buffer should be at
    // least 50% full, except for the head segment and the tail segment.
    //
    // The head segment cannot maintain the invariant because the application is
    // consuming bytes from this segment, decreasing its level.
    //
    // The tail segment cannot maintain the invariant because the application is
    // producing bytes, which may require new nearly-empty tail segments to be
    // appended.
    //
    //
    // Moving segments between buffers
    //
    // When writing one buffer to another, we prefer to reassign entire segments
    // over copying bytes into their most compact form. Suppose we have a buffer
    // with these segment levels [91%, 61%]. If we append a buffer with a
    // single [72%] segment, that yields [91%, 61%, 72%]. No bytes are copied.
    //
    // Or suppose we have a buffer with these segment levels: [100%, 2%], and we
    // want to append it to a buffer with these segment levels [99%, 3%]. This
    // operation will yield the following segments: [100%, 2%, 99%, 3%]. That
    // is, we do not spend time copying bytes around to achieve more efficient
    // memory use like [100%, 100%, 4%].
    //
    // When combining buffers, we will compact adjacent buffers when their
    // combined level doesn't exceed 100%. For example, when we start with
    // [100%, 40%] and append [30%, 80%], the result is [100%, 70%, 80%].
    //
    //
    // Splitting segments
    //
    // Occasionally we write only part of a source buffer to a sink buffer. For
    // example, given a sink [51%, 91%], we may want to write the first 30% of
    // a source [92%, 82%] to it. To simplify, we first transform the source to
    // an equivalent buffer [30%, 62%, 82%] and then move the head segment,
    // yielding sink [51%, 91%, 30%] and source [62%, 82%].

    if (source == null) throw new IllegalArgumentException("source == null");
    if (source == this) throw new IllegalArgumentException("source == this");
    checkOffsetAndCount(source.size, 0, byteCount);

    while (byteCount > 0) {
      // Is a prefix of the source's head segment all that we need to move?
     // 如果 Source Buffer 的頭結點可用位元組數大於要寫出的位元組數
      if (byteCount < (source.head.limit - source.head.pos)) {
        //取到當前buffer的尾節點
        Segment tail = head != null ? head.prev : null;
        // 如果尾部結點有足夠空間可以寫數據,並且這個結點是底層數組的擁有者
        if (tail != null && tail.owner
            && (byteCount + tail.limit - (tail.shared ? 0 : tail.pos) <= Segment.SIZE)) {
          // Our existing segments are sufficient. Move bytes from source's head to our tail.
          //source頭結點的數據寫入到當前尾節點中,然後就直接結束返回了
          source.head.writeTo(tail, (int) byteCount);
          source.size -= byteCount;
          size += byteCount;
          return;
        } else {
          // We're going to need another segment. Split the source's head
          // segment in two, then move the first of those two to this buffer.
          //如果尾節點空間不足或者不是持有者,這時就需要把 Source Buffer 的頭結點分割為兩個 Segment,
          //然後將source的頭指針更新為分割後的第一個Segment, 如[92%, 82%]變成[30%, 62%, 82%]這樣
          source.head = source.head.split((int) byteCount);
        }
      }

      // Remove the source's head segment and append it to our tail.
      //從 Source Buffer 的鏈表中移除頭結點, 並加入到當前Buffer的鏈尾
      Segment segmentToMove = source.head;
      long movedByteCount = segmentToMove.limit - segmentToMove.pos;
      //移除操作,並移動更新source中的head
      source.head = segmentToMove.pop();
       // 如果當前buffer的頭結點為 null,則頭結點直接指向source的頭結點,初始化雙向鏈表
      if (head == null) {
        head = segmentToMove;
        head.next = head.prev = head;
      } else {
        //否則就把Source Buffer的 head 加入到當前Buffer的鏈尾
        Segment tail = head.prev;
        tail = tail.push(segmentToMove);//壓入鏈尾,並更新尾節點
        tail.compact();//尾節點嘗試合併,如果合併成功,則尾節點會被SegmentPool回收掉
      }
      source.size -= movedByteCount;
      size += movedByteCount;
      byteCount -= movedByteCount;
    }
  }
主要就是在這個 write(Buffer source, long byteCount) 方法中實現的,這個方法前面有大段的英文注釋,我從源碼中直接複製過來的,我們可以翻譯過來理解一下說的是啥:
將位元組數據從 source buffer 的頭節點複製到當前buffer的尾節點中,這裡主要需要平衡兩個相互衝突的目標:CPU 和 記憶體。
不要浪費 CPU(即不要複製全部的數據)。
複製大量數據代價昂貴。相反,我們更喜歡將整個段從一個緩衝區重新分配到另一個緩衝區。
不要浪費記憶體。
Segment作為一個不可變數,緩衝區中除了頭節點和尾節點的片段以外,相鄰的片段,至少應該保證
50%以上的數據負載量(指的是Segment中的data數據, Okio 認為data數據量在50%以上才算是被有效利用的)。由於頭結點中需要讀取消耗位元組數據,而尾節點中需要寫入產生位元組數據,因此頭結點和尾節點是不能保持不變性的。在緩衝區之間移動片段
在將一個緩衝區寫入另一個緩衝區時,我們更喜歡重新分配整個段,將位元組複製到最緊湊的形式。假設我們有一個緩衝區,其中的片段負載為[91%,61%],如果我們要在這上面附加一個負載量為[72%]的單一片段,這樣將產生的結果為[91%,61%,72%]。這期間不會進行任何的位元組複製操作。(即空間換時間,犧牲記憶體,提供速度)
再假設,我們有一個緩衝區負載量為:[100%,2%],並且我們希望將其附加到一個負載量為[99%,3%]的緩衝區中。這個操作將產生以下部分:[100%、2%、99%、3%],也就是說,我們不會花時間去複製位元組來提高記憶體的使用效率,如變成[100%,100%,4%]這樣。(即這種情況下 Okio 不會採取時間換空間的策略,因為太浪費CPU)
在合併緩衝區時,當相鄰緩衝區的合併級別不超過100%時,我們將壓縮相鄰緩衝區。例如,當我們在[100%,40%]基礎上附加[30%,80%]時,結果將會是[100%,70%,80%]。(也就是中間相鄰的負載為 40% 和 30% 的兩個 Segment 將會被合併為一個負載為 70% 的 Segment )
分割片段
有時我們只想將 source buffer 中的一部分寫入到sink buffer當中,例如,給定一個sink為
[51%,91%],現在我們想要將一個source為[92%,82%]的前30%寫入到這個sinkbuffer 當中。為了簡化,我們首先將 source buffer 轉換為等效緩衝區[30%,62%,82%](即拆分Segment),然後移動 source 的頭結點 Segment 即可,最終生成 sink[51%,91%,30%]和 source[62%,82%]。
這裡的注釋基本上已經說明了這個方法的意圖實現過程,主要是通過移動 source 頭結點的指向,另外配合分割/合併Segment的操作來平衡 CPU 消耗和記憶體消耗的兩個目標。
Segment 的合併過程:
假設初始兩個 Buffer 中的 Segment 鏈表如下:
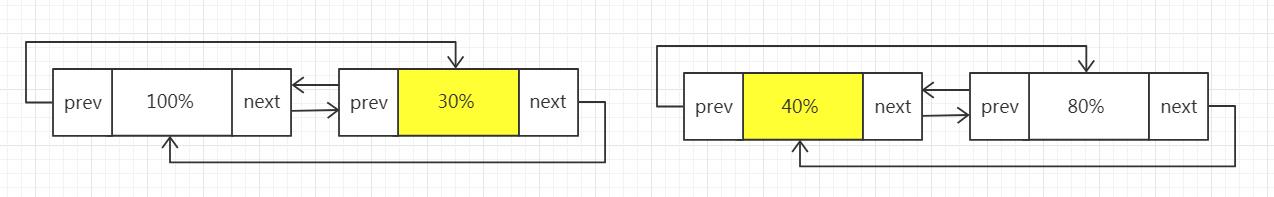
現在將第二個 Buffer 完全寫入到第一個 Buffer: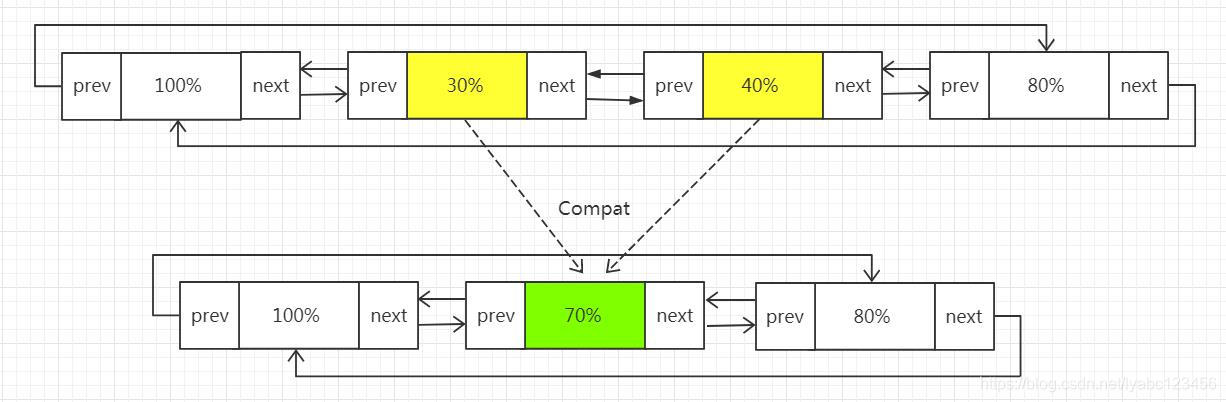
首先,它會直接將第二個 Buffer 的頭節點連接到第一個 Buffer 的鏈尾,然後嘗試將鏈尾的兩個 Segment 進行合併,如果合併成功,則在合併之後,圖中 40% 的那個 Segment 會被SegmentPool 回收,它的數據完全寫入到 30% 的那個 Segment 中,最終生成一個70% 的 Segment,這樣就達到了節約記憶體的目標。
Segment 的拆分過程:
假設初始兩個 Buffer 中的 Segment 鏈表如下:
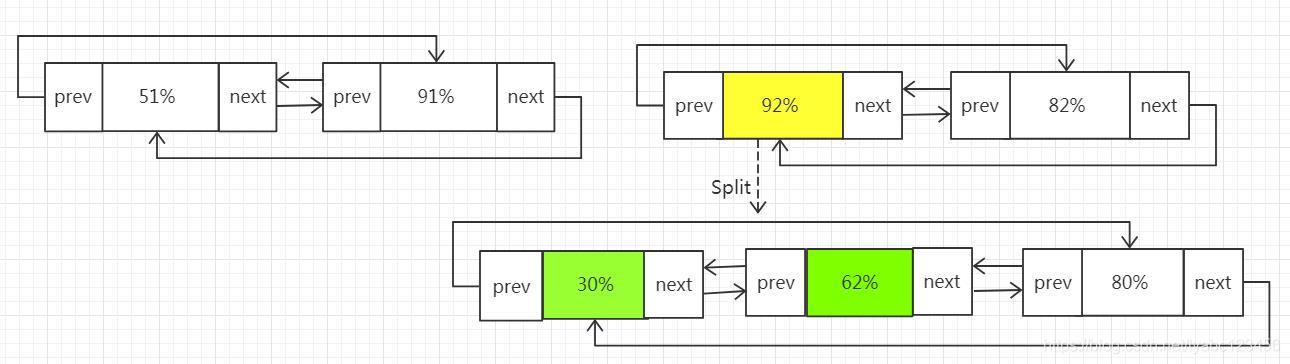
現在要從第二個Buffer中取前30%的數據寫入到第一個Buffer當中,那麼首先會將第二個Buffer的頭結點Segment進行分割,分割為兩個負載為30%和62%的Segment, 接下來移動這個新的30%的Segment節點到第一個Buffer的鏈表的尾部:
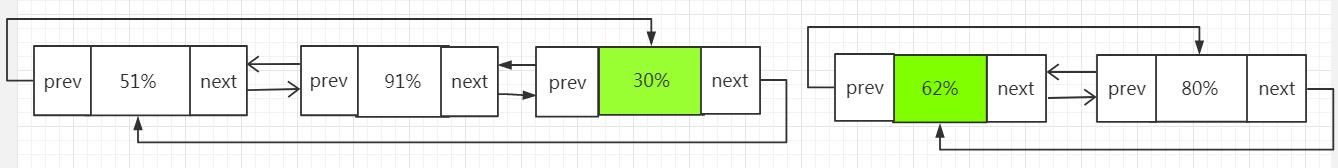
這樣就完成了從第二個Buffer取30%的數據寫入到第一個Buffer當中的工作。
超時機制
Okio的亮點之一就是增加了超時機制,防止因為意外導致I/O一直阻塞的問題,默認的超時機制是同步的。AsyncTimeout是Okio中非同步超時機制的實現,它是一個單鏈表,結點按等待時間從小到大排序,head是一個頭結點,起佔位作用。使用了一個WatchDog的後台執行緒來不斷的遍歷所有節點,如果某個節點超時就會將該節點從鏈表中移除,並關閉Socket。
AsyncTimeout提供了3個方法enter、exit、timeout,分別用於流操作開始、結束、超時三種情況調用。
public class AsyncTimeout extends Timeout {
    //頭結點,佔位使用
    static
    AsyncTimeout head;

    //是否在鏈表中
    private boolean inQueue;

    //後繼節點
    private
    AsyncTimeout next;

    //超時時間
    private long timeoutAt;
    //把當前AsyncTimeout對象加入節點
    public final void enter() {
        ...
        scheduleTimeout(this, timeoutNanos, hasDeadline);
    }

    private static synchronized void scheduleTimeout(
            AsyncTimeout node, long timeoutNanos, boolean hasDeadline) {
        //創建佔位頭結點並開啟子執行緒
        if (head == null) {
            head = new AsyncTimeout();
            new Watchdog().start();
        }

        ...

        //插入到鏈表中,按照時間長短進行排序,等待事件越長越靠後
        for (AsyncTimeout prev = head; true; prev = prev.next) {
            if (prev.next == null || remainingNanos < prev.next.remainingNanos(now)) {
                node.next = prev.next;
                prev.next = node;
                if (prev == head) {
                    AsyncTimeout.class.notify(); // Wake up the watchdog when inserting at the front.
                }
                break;
            }
        }
    }

    //從鏈表中移除節點
    public final boolean exit() {
        if (!inQueue) return false;
        inQueue = false;
        return cancelScheduledTimeout(this);
    }

    //執行真正的移除操作
    private static synchronized boolean cancelScheduledTimeout(AsyncTimeout node) {
        // Remove the node from the linked list.
        for (AsyncTimeout prev = head; prev != null; prev = prev.next) {
            if (prev.next == node) {
                prev.next = node.next;
                node.next = null;
                return false;
            }
        }

        // The node wasn't found in the linked list: it must have timed out!
        return true;
    }

    //在子類中重寫了該方法,主要是進行socket的關閉
    protected void timedOut() {
    }

    //監聽節點是否超時的子執行緒
    private static final class Watchdog extends Thread {
        Watchdog() {
            super("Okio Watchdog");
            setDaemon(true);
        }

        public void run() {
            while (true) {
                try {
                    AsyncTimeout timedOut;
                    synchronized (AsyncTimeout.class) {
                        timedOut = awaitTimeout();
                        //代表頭結點的後繼節點已超時,
                        if (timedOut == null) continue;
                        //除頭結點外沒有任何其他節點
                        if (timedOut == head) {
                            head = null;
                            return;
                        }
                    }

                    //關閉socket
                    timedOut.timedOut();
                } catch (InterruptedException ignored) {
                }
            }
        }
    }


    static AsyncTimeout awaitTimeout() throws InterruptedException {
        AsyncTimeout node = head.next;
        //除了頭結點外沒有任何其他節點
        if (node == null) {
            long startNanos = System.nanoTime();
            AsyncTimeout.class.wait(IDLE_TIMEOUT_MILLIS);
            return head.next == null && (System.nanoTime() - startNanos) >= IDLE_TIMEOUT_NANOS
                    ? head  // The idle timeout elapsed.
                    : null; // The situation has changed.
        }

        long waitNanos = node.remainingNanos(System.nanoTime());

        //進行等待
        if (waitNanos > 0) {
            //等待
            long waitMillis = waitNanos / 1000000L;
            waitNanos -= (waitMillis * 1000000L);
            AsyncTimeout.class.wait(waitMillis, (int) waitNanos);
            return null;
        }

        //代表node節點已超時
        head.next = node.next;
        node.next = null;
        return node;
    }
}
默認都是未設置超時時間的,需要我們自己來設置,同步及非同步的超時時間設置方式是一樣的,通過下面程式碼即可。
    sink.timeout().deadline(1, TimeUnit.SECONDS);
    source.timeout().deadline(1,TimeUnit.MILLISECONDS);
生產者/消費者模型
在 Okio 中可以使用 Pipe 來實現一個生產者/消費者模型。Pipe 維護了一個一定大小 Buffer。當該 Buffer 容量達到最大時,執行緒就會等待直到該 Buffer 有剩餘的空間。
public final class Pipe {
  //Pipe的最大容量
  final long maxBufferSize;
  //Pipe對應的Buffer
  final Buffer buffer = new Buffer();
  boolean sinkClosed;
  boolean sourceClosed;
  //寫入流,對應著生產者
  private final Sink sink = new PipeSink();
  //讀取流,對應著消費者
  private final Source source = new PipeSource();

  public Pipe(long maxBufferSize) {
    //最大容量不能小於1
    if (maxBufferSize < 1L) {
      throw new IllegalArgumentException("maxBufferSize < 1: " + maxBufferSize);
    }
    this.maxBufferSize = maxBufferSize;
  }
  ...
  //寫入數據到Pipe中
  final class PipeSink implements Sink {
    final Timeout timeout = new Timeout();

    @Override public void write(Buffer source, long byteCount) throws IOException {
      synchronized (buffer) {
        ...

        while (byteCount > 0) {
          ...

          long bufferSpaceAvailable = maxBufferSize - buffer.size();
          if (bufferSpaceAvailable == 0) {
            //buffer中,沒有剩餘空間,等待消費者消費
            timeout.waitUntilNotified(buffer); // Wait until the source drains the buffer.
            continue;
          }

          long bytesToWrite = Math.min(bufferSpaceAvailable, byteCount);
      // 將數據寫入到 buffer的 data 中
          buffer.write(source, bytesToWrite);
          // 還需要寫多少數據
          byteCount -= bytesToWrite;
          //通知buffer,有新的數據了,
          buffer.notifyAll(); // Notify the source that it can resume reading.
        }
      }
    }

    ...
  }
  //從 Pipe 中讀取數據
  final class PipeSource implements Source {
    final Timeout timeout = new Timeout();

    @Override public long read(Buffer sink, long byteCount) throws IOException {
      synchronized (buffer) {
        ...

        while (buffer.size() == 0) {
          if (sinkClosed) return -1L;
          //Pipe中沒有數據,等待生產者寫入
          timeout.waitUntilNotified(buffer); // Wait until the sink fills the buffer.
        }

        long result = buffer.read(sink, byteCount);
        buffer.notifyAll(); // Notify the sink that it can resume writing.
        return result;
      }
    }
    ...
  }
}
Pipe 的程式碼還是比較少的。簡單說下 pipe 的實現原理,其實就是內部維護了一個 buffer 用來存儲數據,可讀可寫;
-
當讀數據的時候,就會減少 buffer 裡面數據的容量,同時通過 buffer.notifyAll() 告訴外界狀態發生了變化;
-
當寫數據的時候,只能添加最大容量的數據,寫好數據之後,就會通過 buffer.notifyAll() 告訴外界狀態發生了變化;
下面就來如何使用 Pipe。
    public void pipe() throws IOException {
        //設置 Pipe 的容量為1024位元組,即 1kb
        Pipe pipe = new Pipe(1024);
        new Thread(new Runnable() {
            @Override
            public void run() {
          //1 pipe.source 會從 pipe 的 buffer 中讀取數據
                try (BufferedSource bufferedSource = Okio.buffer(pipe.source())) {
                    //2 將Pipe中數據寫入env4.txt這個文件中,;
                    bufferedSource.readAll(Okio.sink(new File("file/env4.txt")));
                } catch (IOException e) {
                    e.printStackTrace();
                }
            }
        }).start();

        new Thread(new Runnable() {
            @Override
            public void run() {
          //3 pipe.sink 會將數據寫入到 pipe 的 buffer 中
                try (BufferedSink bufferedSink = Okio.buffer(pipe.sink())) {
                    //4 將env3.txt中數據寫入到Pipe中;
                    bufferedSink.writeAll(Okio.source(new File("file/env3.txt")));
                } catch (IOException e) {
                    e.printStackTrace();
                }
            }
        }).start();
    }
-
Okio.buffer(pipe.source()) 創建一個 source ,可以用於讀取數據;
-
Okio.sink(new File("file/env4.txt")) 創建一個 sink,在調用 bufferedSource.readAll (sink ),意思就是 bufferedSource 將自身 buffer (pipe 中的 buffer 數據)的數據給 sink。
-
Okio.buffer(pipe.sink()) 創建一個 sink ,可以寫數據;
-
Okio.source(new File("file/env3.txt")) 創建一個 source , bufferedSink.writeAll(source) 意思就是從 source 裡面獲取數據添加到自身的 buffer (pipe 中的 buffer 數據)
//juejin.cn/post/6844904195707912200
//blog.csdn.net/lyabc123456/article/details/88830541
//juejin.cn/post/6844903785236545549
//blog.csdn.net/lyabc123456/article/details/89106168