輕量級CNN模型之squeezenet
- 2019 年 10 月 31 日
- 筆記
SqueezeNet
論文地址:https://arxiv.org/abs/1602.07360
和別的輕量級模型一樣,模型的設計目標就是在保證精度的情況下盡量減少模型參數.核心是論文提出的一種叫"fire module"的卷積方式.
設計策略
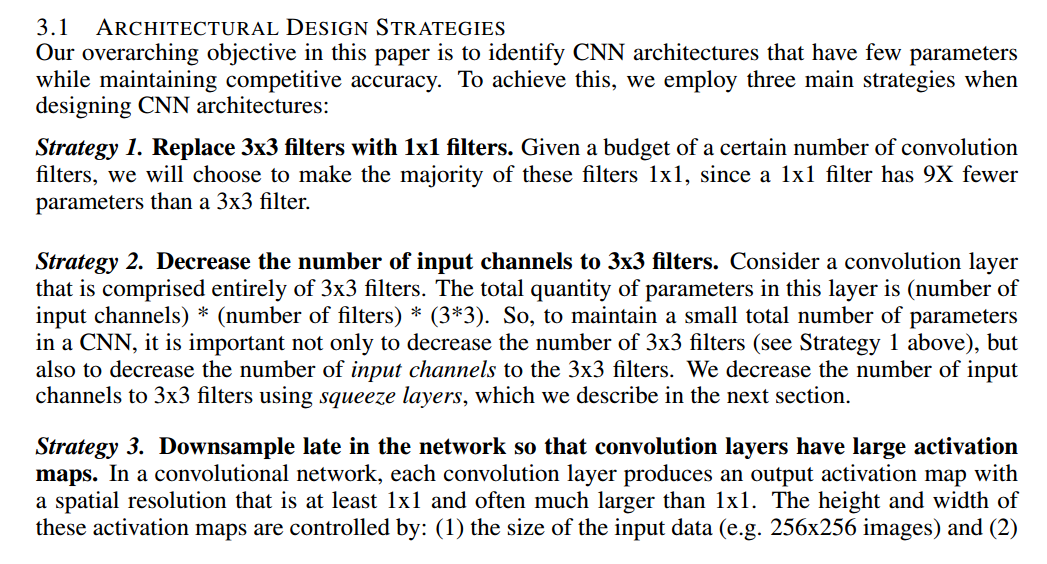
- 主要用1x1卷積核,而不是3x3.
- 減少3x3卷積核作用的channel.
- 推遲下取樣的時間.以獲取更大尺寸的feature map.這一點是處於精度的考慮.畢竟feature map的resolution越大,資訊越豐富.下取樣主要通過pool來完成或者卷積的時候控制stride大小.
Fire Module
這個就是網路的核心組件了.
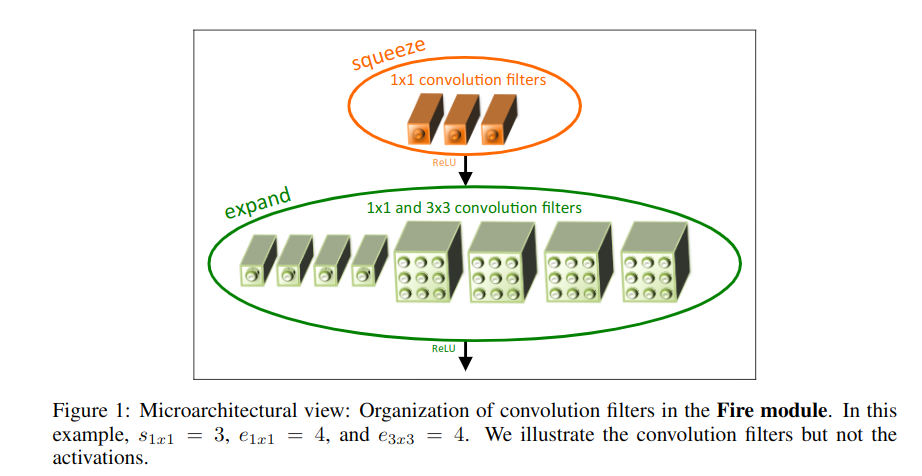
分2部分:
- squeeze convolution layer
- expand layer
其中squeeze只有1x1filter,expand layer由1x1和3x3filter組成.
在squeeze層卷積核數記為(s_{1x1}),在expand層,記1x1卷積核數為(e_{1x1}),而3x3卷積核數為(e_{3x3}),這三個屬於超參數,可調。為了盡量降低3x3的輸入通道數,讓(s_{1x1}<e_{1x1}+e_{3x3})。
這兩層的設計分別體現了策略1(多用1x1filter)和策略2(減少3x3filter作用channel).
首先,squeeze convolution layer通過控制1x1卷積核數量達到把輸入的channel數目降低的目的.這個是降低參數的最關鍵的一步.
然後,分別用1x1卷積核和3x3卷積核去做卷積.然後得到不同depth的輸出,concat起來.([x,x,depth1],[x,x,depth2]-->[x,x,depth1+depth2])
程式碼實現
torch的官方實現:https://pytorch.org/docs/stable/_modules/torchvision/models/squeezenet.html
import torch import torch.nn as nn class Fire(nn.Module): def __init__(self, inplanes, squeeze_planes, expand1x1_planes, expand3x3_planes): super(Fire, self).__init__() self.inplanes = inplanes self.squeeze = nn.Conv2d(inplanes, squeeze_planes, kernel_size=1) self.squeeze_activation = nn.ReLU(inplace=True) self.expand1x1 = nn.Conv2d(squeeze_planes, expand1x1_planes, kernel_size=1) self.expand1x1_activation = nn.ReLU(inplace=True) self.expand3x3 = nn.Conv2d(squeeze_planes, expand3x3_planes, kernel_size=3, padding=1) self.expand3x3_activation = nn.ReLU(inplace=True) def forward(self, x): x = self.squeeze_activation(self.squeeze(x)) print(x.shape) e_1 = self.expand1x1(x) print(e_1.shape) e_3 = self.expand3x3(x) print(e_3.shape) return torch.cat([ self.expand1x1_activation(e_1), self.expand3x3_activation(e_3) ], 1)很顯然地,squeeze convolution layer把channel數量降下來了,所以參數少了很多.
以輸入tensor為[n,c,h,w]=[1,96,224,224]舉例,假設fire module的squeeze layer的卷積核數量為6,expand layer中1x1卷積核數量為5,3x3卷積核數量為4.
則fire module的參數數量為1x1x96x6 + 1x1x6x5 + 3x3x6x4=822.
普通的3x3卷積,得到depth=9的feature map的話需要3x3x96x9=7776個參數.
所以模型才可以做到很小.
網路結構

基本就是fire module的堆疊.中間穿插了一些maxpool對feature map下取樣. 注意一下最後用了dropout以及全局平均池化而不是全連接來完成分類.
最左邊的就是類似vgg的堆疊式的結構.中間和右邊的參考了resnet的skip-connection.
class SqueezeNet(nn.Module): def __init__(self, version='1_0', num_classes=1000): super(SqueezeNet, self).__init__() self.num_classes = num_classes if version == '1_0': self.features = nn.Sequential( nn.Conv2d(3, 96, kernel_size=7, stride=2), nn.ReLU(inplace=True), nn.MaxPool2d(kernel_size=3, stride=2, ceil_mode=True), Fire(96, 16, 64, 64), Fire(128, 16, 64, 64), Fire(128, 32, 128, 128), nn.MaxPool2d(kernel_size=3, stride=2, ceil_mode=True), Fire(256, 32, 128, 128), Fire(256, 48, 192, 192), Fire(384, 48, 192, 192), Fire(384, 64, 256, 256), nn.MaxPool2d(kernel_size=3, stride=2, ceil_mode=True), Fire(512, 64, 256, 256), ) elif version == '1_1': self.features = nn.Sequential( nn.Conv2d(3, 64, kernel_size=3, stride=2), nn.ReLU(inplace=True), nn.MaxPool2d(kernel_size=3, stride=2, ceil_mode=True), Fire(64, 16, 64, 64), Fire(128, 16, 64, 64), nn.MaxPool2d(kernel_size=3, stride=2, ceil_mode=True), Fire(128, 32, 128, 128), Fire(256, 32, 128, 128), nn.MaxPool2d(kernel_size=3, stride=2, ceil_mode=True), Fire(256, 48, 192, 192), Fire(384, 48, 192, 192), Fire(384, 64, 256, 256), Fire(512, 64, 256, 256), ) else: # FIXME: Is this needed? SqueezeNet should only be called from the # FIXME: squeezenet1_x() functions # FIXME: This checking is not done for the other models raise ValueError("Unsupported SqueezeNet version {version}:" "1_0 or 1_1 expected".format(version=version)) # Final convolution is initialized differently from the rest final_conv = nn.Conv2d(512, self.num_classes, kernel_size=1) self.classifier = nn.Sequential( nn.Dropout(p=0.5), final_conv, nn.ReLU(inplace=True), nn.AdaptiveAvgPool2d((1, 1)) ) for m in self.modules(): if isinstance(m, nn.Conv2d): if m is final_conv: init.normal_(m.weight, mean=0.0, std=0.01) else: init.kaiming_uniform_(m.weight) if m.bias is not None: init.constant_(m.bias, 0) def forward(self, x): x = self.features(x) x = self.classifier(x) return torch.flatten(x, 1)https://pytorch.org/hub/pytorch_vision_squeezenet/
這裡有一個用torch中的模型做推理的例子,
..... with torch.no_grad(): output = model(input_batch) # Tensor of shape 1000, with confidence scores over Imagenet's 1000 classes print(output[0]) # The output has unnormalized scores. To get probabilities, you can run a softmax on it. print(torch.nn.functional.softmax(output[0], dim=0))CNN結構設計的探索
主要從2個方面做實驗探討了不同結構對模型精度和模型大小的影響.

- fire module怎麼設計,squeeze layer和expand layer的filter數量怎麼設計
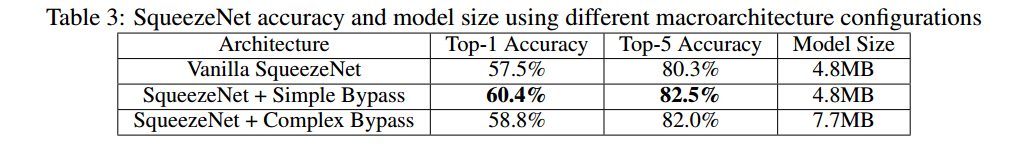
- fire module怎麼串起來形成一個網路,是簡單堆疊還是引入bypass
關於第一點fire module中各種filter佔比的實驗結果如下圖:

這裡的sr指的是squeeze layer的卷積核數量/expand layer比例.3x3filter比例指expand layer里3x3filter比例.
具體設計參考論文:

一點思考:
1x1的卷積核關聯了某個位置的feature所有channel上的資訊.3x3的卷積核關聯了多個位置的feature的所有channel的資訊.按道理說3x3的越多應該模型精度越好,但實驗數據顯示並非如此.可能有些是噪音,3x3卷積參考太多周圍的feature反而導致精度下降. 這也是深度學習現在被比較多詬病的一點,太黑盒了.只知道能work,為啥work不好解釋.不同的數據集可能不同的參數表現會不一樣,很難講哪個最優,調參比較依賴經驗.
關於第二點在layer之間採用不同的連接方式,實驗結果如下: