Netty源碼分析--記憶體模型(下)(十二)
- 2019 年 10 月 3 日
- 筆記
這一節我們一起看下分配過程
1 PooledByteBuf<T> allocate(PoolThreadCache cache, int reqCapacity, int maxCapacity) { 2 PooledByteBuf<T> buf = newByteBuf(maxCapacity); // 初始化一塊容量為 2^31 - 1的ByteBuf 3 allocate(cache, buf, reqCapacity); // reqCapacity = 1024 進入分配邏輯 4 return buf; 5 }
1 private void allocate(PoolThreadCache cache, PooledByteBuf<T> buf, final int reqCapacity) { 2 final int normCapacity = normalizeCapacity(reqCapacity); // 對請求的大小進行校準,一會具體看 3 if (isTinyOrSmall(normCapacity)) { // capacity < pageSize 判斷校準之後的請求大小 是否小於 8k 4 int tableIdx; 5 PoolSubpage<T>[] table; 6 boolean tiny = isTiny(normCapacity); // 判斷請求大小是否小於512B 7 if (tiny) { // < 512 8 if (cache.allocateTiny(this, buf, reqCapacity, normCapacity)) { // 從快取中進行分配,如果是第一次這裡肯定是沒有對應大小快取的,除非之前有過釋放,然後記憶體空間被快取起來了。 9 // was able to allocate out of the cache so move on 10 return; 11 } 12 tableIdx = tinyIdx(normCapacity); // tiny數組中獲取對應的下標 13 table = tinySubpagePools; // tiny subPage數組 14 } else { // 512 <= normCapacity < 8K 15 if (cache.allocateSmall(this, buf, reqCapacity, normCapacity)) { // 一樣從快取中進行分配,這個上一節詳細的介紹過 16 // was able to allocate out of the cache so move on 17 return; 18 } 19 tableIdx = smallIdx(normCapacity); // 獲取small subPage數組下標 20 table = smallSubpagePools; // subPage 數組 21 } 22 23 final PoolSubpage<T> head = table[tableIdx];// 取得對應下標的subPage 24 25 /** 26 * Synchronize on the head. This is needed as {@link PoolChunk#allocateSubpage(int)} and 27 * {@link PoolChunk#free(long)} may modify the doubly linked list as well. 28 */ 29 synchronized (head) { // 鎖定防止其他操作修改head結點 30 final PoolSubpage<T> s = head.next; 31 if (s != head) {// 如果雙向鏈表已經初始化,那麼從subpage中進行分配 32 assert s.doNotDestroy && s.elemSize == normCapacity; // 斷言確保 當前的這個subPage中的elemSize大小必須和校對後的請求大小一樣 33 long handle = s.allocate(); // 從subPage中進行分配 34 assert handle >= 0; 35 s.chunk.initBufWithSubpage(buf, handle, reqCapacity); 36 incTinySmallAllocation(tiny); 37 return; 38 } 39 } 40 synchronized (this) { 41 allocateNormal(buf, reqCapacity, normCapacity); // 雙向循環鏈表還沒初始化,使用normal分配 42 } 43 44 incTinySmallAllocation(tiny); 45 return; 46 } 47 if (normCapacity <= chunkSize) { 48 if (cache.allocateNormal(this, buf, reqCapacity, normCapacity)) { 49 // was able to allocate out of the cache so move on 50 return; 51 } 52 synchronized (this) { 53 allocateNormal(buf, reqCapacity, normCapacity); 54 ++allocationsNormal; 55 } 56 } else { 57 // Huge allocations are never served via the cache so just call allocateHuge 58 allocateHuge(buf, reqCapacity); 59 } 60 }
int normalizeCapacity(int reqCapacity) { if (reqCapacity < 0) { throw new IllegalArgumentException("capacity: " + reqCapacity + " (expected: 0+)"); } if (reqCapacity >= chunkSize) { return directMemoryCacheAlignment == 0 ? reqCapacity : alignCapacity(reqCapacity); } if (!isTiny(reqCapacity)) { // 如果是 >=512 的記憶體申請,那麼就規範到2的次方大小 ,比如 1000 就會 變成 1024,自己可以把這段位操作,自己main方法試一下。 // Doubled int normalizedCapacity = reqCapacity; normalizedCapacity --; normalizedCapacity |= normalizedCapacity >>> 1; normalizedCapacity |= normalizedCapacity >>> 2; normalizedCapacity |= normalizedCapacity >>> 4; normalizedCapacity |= normalizedCapacity >>> 8; normalizedCapacity |= normalizedCapacity >>> 16; normalizedCapacity ++; if (normalizedCapacity < 0) { normalizedCapacity >>>= 1; } assert directMemoryCacheAlignment == 0 || (normalizedCapacity & directMemoryCacheAlignmentMask) == 0; return normalizedCapacity; } if (directMemoryCacheAlignment > 0) { return alignCapacity(reqCapacity); } // Quantum-spaced if ((reqCapacity & 15) == 0) { // 如果 < 512 判斷如果是16的倍數,那麼直接返回 return reqCapacity; } return (reqCapacity & ~15) + 16; // 如果不是則對齊成16的倍數 }
private void allocateNormal(PooledByteBuf<T> buf, int reqCapacity, int normCapacity) { if (q050.allocate(buf, reqCapacity, normCapacity) || q025.allocate(buf, reqCapacity, normCapacity) || q000.allocate(buf, reqCapacity, normCapacity) || qInit.allocate(buf, reqCapacity, normCapacity) || q075.allocate(buf, reqCapacity, normCapacity)) { return; } // 先嘗試從chunk鏈表中進行分配, 這裡有一個需要注意的地方 // 分配順序 先分配 q50 也就是 50% ~ 100% 的,然後是 q25 也就是 25% ~ 75% 的, 然後是 q000 0%~50% 、 qInit 0%~25% 、 q75 75% ~ 100% // Add a new chunk. PoolChunk<T> c = newChunk(pageSize, maxOrder, pageShifts, chunkSize); // 新建一個Chunk long handle = c.allocate(normCapacity); // 記憶體分配 assert handle > 0; c.initBuf(buf, handle, reqCapacity); qInit.add(c); // 添加到初始化的chunk鏈表 }
上面的分配順序,大家想一下為什麼不是從q000開始分配呢?我找了一段分析的很好的。
在分析PoolChunkList的時候,我們知道一個chunk隨著記憶體的不停釋放,它本身會不停的往其所在的chunk list的prev list移動,直到其完全釋放後被回收。 如果這裡是從q000開始嘗試分配,雖然分配的速度可能更快了(因為分配成功的幾率更大),但一個chunk在使用率為25%以內時有更大幾率再分配,也就是一個chunk被回收的幾率大大降低了。這樣就帶來了一個問題,我們的應用在實際運行過程中會存在一個訪問高峰期,這個時候記憶體的佔用量會是平時的幾倍,因此會多分配幾倍的chunk出來,而等高峰期過去以後,由於chunk被回收的幾率降低,記憶體回收的進度就會很慢(因為沒被完全釋放,所以無法回收),記憶體就存在很大的浪費。
為什麼是從q050開始嘗試分配呢,q050是記憶體佔用50%~100%的chunk,猜測是希望能夠提高整個應用的記憶體使用率,因為這樣大部分情況下會使用q050的記憶體,這樣在記憶體使用不是很多的情況下一些利用率低(<50%)的chunk慢慢就會淘汰出去,最終被回收。然而為什麼不是從qinit中開始呢,這裡的chunk利用率低,但又不會被回收,豈不是浪費?q075,q100由於使用率高,分配成功的幾率也會更小,因此放到最後。
上面也有提到新建一個chunk,這裡我想特殊說明兩個byte數組,數組的大小是4096
memoryMap = new byte[maxSubpageAllocs << 1]; depthMap = new byte[memoryMap.length]; int memoryMapIndex = 1; for (int d = 0; d <= maxOrder; ++ d) { // move down the tree one level at a time int depth = 1 << d; for (int p = 0; p < depth; ++ p) { // in each level traverse left to right and set value to the depth of subtree memoryMap[memoryMapIndex] = (byte) d; depthMap[memoryMapIndex] = (byte) d; memoryMapIndex ++; } }
循環之後的數組是怎麼樣子的呢?

MemoryMap存放分配資訊,depthMap存放節點的高度資訊 ;初始狀態時,memoryMap和depthMap相等,depthMap的值初始化後不再改變,memoryMap的值則隨著節點分配而改變。
下標代表了平衡二叉樹的節點序號,值代表該節點的高度值。
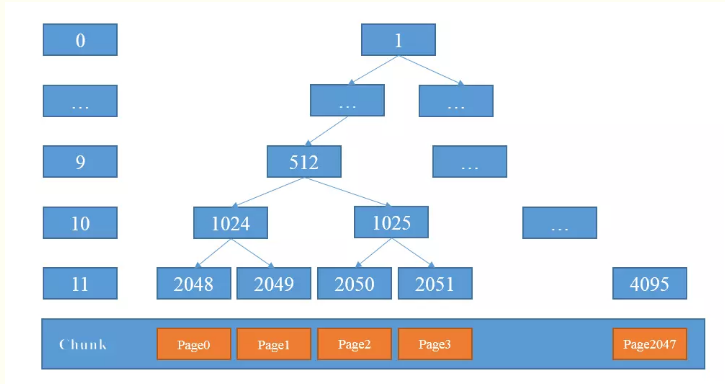
比如MemoryMap[1024] = 10, MemoryMap[2048] = 11. 好了,這個說完了,我們繼續看:
1 long allocate(int normCapacity) { 2 if ((normCapacity & subpageOverflowMask) != 0) { // >= pageSize >= 8K 3 return allocateRun(normCapacity); 4 } else { 5 return allocateSubpage(normCapacity); // < 8K 6 } 7 }
 1     private long allocateSubpage(int normCapacity) {   2         // Obtain the head of the PoolSubPage pool that is owned by the PoolArena and synchronize on it.   3         // This is need as we may add it back and so alter the linked-list structure.   4         PoolSubpage<T> head = arena.findSubpagePoolHead(normCapacity); // 根據請求記憶體大小,獲取下標,然後獲取對應的subPage   5         synchronized (head) {   6             int d = maxOrder; // 最大層數 11   7             int id = allocateNode(d);  // 分配節點,修改涉及節點層數, 具體看下面的分析   8             if (id < 0) { // 無可分配節點   9                 return id;  10             }  11  12             final PoolSubpage<T>[] subpages = this.subpages;  13             final int pageSize = this.pageSize;  14  15             freeBytes -= pageSize;// 16M(初始化值,後面會逐漸減少) - 8K  16  17             int subpageIdx = subpageIdx(id); // 2048 對應的偏移量是 0 , 2049 對應的偏移量是 1 。。。4095 對應偏移量是 2047  18             PoolSubpage<T> subpage = subpages[subpageIdx]; // 取對應下標的 subpage  19             if (subpage == null) {  20                 subpage = new PoolSubpage<T>(head, this, id, runOffset(id), pageSize, normCapacity); // 創建PoolSubpage  21                 subpages[subpageIdx] = subpage;
                   // 新建或初始化subpage並加入到chunk的subpages數組,同時將subpage加入到arena的subpage雙向鏈表中,最後完成分配請求的記憶體。
                   // 程式碼中,subpage != null的情況產生的原因是:subpage初始化後分配了記憶體,但一段時間後該subpage分配的記憶體釋放並從arena的雙向鏈表中刪除,
                   // 此時subpage不為null,當再次請求分配時,只需要調用init()將其加入到areana的雙向鏈表中即可。
  22             } else {  23                 subpage.init(head, normCapacity);  24             }  25             return subpage.allocate(); // 最後結果是一個long整數,其中低32位表示二叉樹中的分配的節點,高32位表示subPage中分配的具體位置  26         }  27     }
修改節點對應的層數,底下這個方法涉及了很多的位運算,這裡大家要仔細琢磨。
1 private int allocateNode(int d) { // d = 11 2 int id = 1; 3 int initial = - (1 << d); // -2048 4 byte val = value(id); // memoryMap[id] , 一般1對應的層數是 0 ,當第一個節點被分配完成後,這個節點的值會變成12 5 if (val > d) { // unusable // 如果分配完成,那麼無法進行分配,那麼就是 12 > 11 ,直接返回 -1 6 return -1; 7 } 8 while (val < d || (id & initial) == 0) { // id & initial == 1 << d for all ids at depth d, for < d it is 0 9 id <<= 1; // 左移1位 10 val = value(id); // 取到節點對應的層數 11 if (val > d) { // 如果當前的值大於層數,也就是說左子節點用完了 12 id ^= 1; // 當前節點值 +1 ,取右節點 13 val = value(id); // 取右子節點 14 } 15 } 16 byte value = value(id); 17 assert value == d && (id & initial) == 1 << d : String.format("val = %d, id & initial = %d, d = %d", 18 value, id & initial, d); 19 setValue(id, unusable); // mark as unusable //將該節點的值設置為12,不可用 20 updateParentsAlloc(id); // 將該節點對應的所有父節點,層數全部 + 1 21 return id; 22 }
1 private void updateParentsAlloc(int id) { 2 while (id > 1) { 3 int parentId = id >>> 1; // 取父級節點 4 byte val1 = value(id); // 5 byte val2 = value(id ^ 1); // 如果 id = 2048 那麼 id ^ 1 = 2049 , 如果 id = 2049 這裡 id ^ 1 = 2048 這裡一定要注意!!! 6 byte val = val1 < val2 ? val1 : val2; 7 setValue(parentId, val); // 修改父級對應層數 8 id = parentId; 9 } 10 }
上面這個方法很有意思,大家要仔細體會,我舉個例子
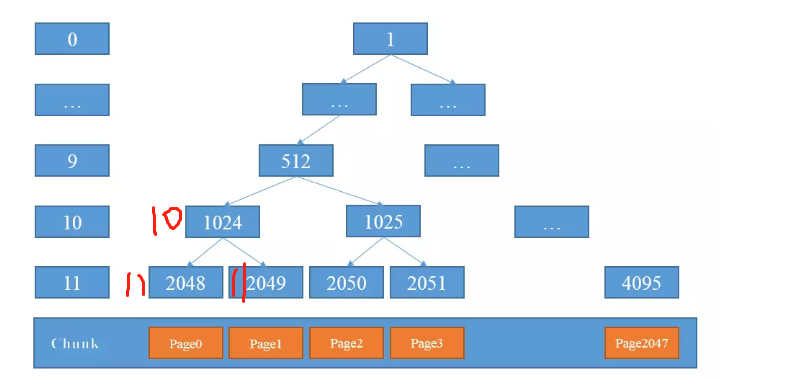
最開始是這樣的,我們開始第一次分配,那麼就是2048號節點,分配完成後會變成
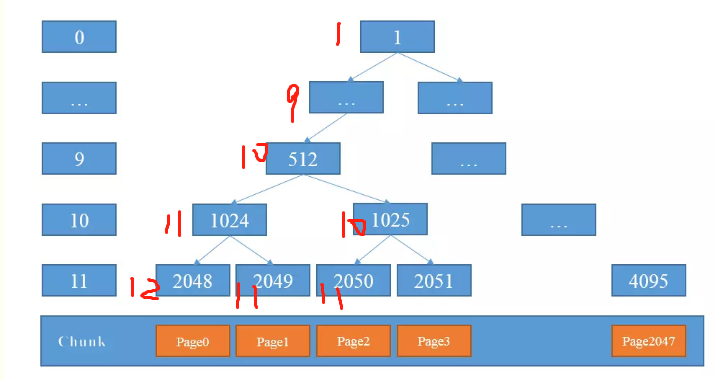
這時候由於2048變成了12,不可用狀態,那麼取右節點進行分配
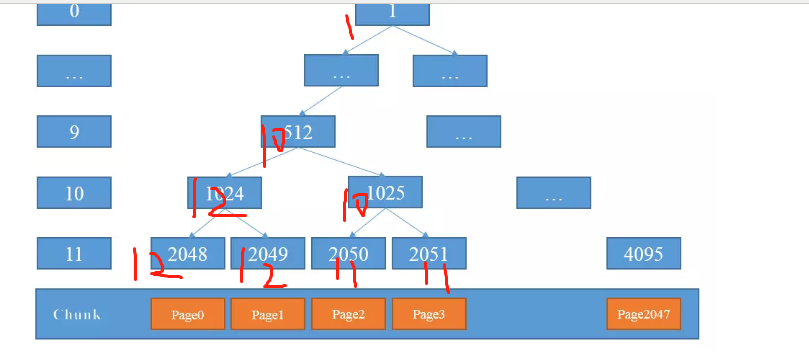
下一次再進行分配的時候, 發現 1024 是 12 ,那麼取右子節點, 是 1025 = 10 ,因為 10 < 11 所以再次進入循環,找到2050節點,對應層數是 11 < 12 ,則分配 2050節點分配後變成
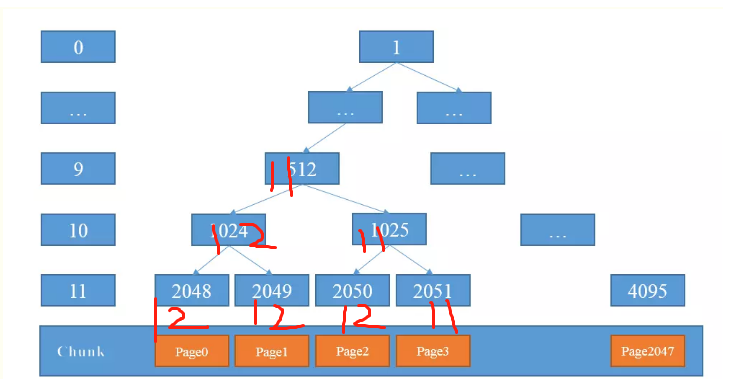
然後依次類推。
1 private long allocateRun(int normCapacity) { 2 int d = maxOrder - (log2(normCapacity) - pageShifts); // 計算滿足需求的節點的高度 比如 16K , 那麼 就是 d= 11 - (14 - 13) = 10 3 int id = allocateNode(d); // 從第十層找空閑節點, 原理跟上面相同,就不說了 4 if (id < 0) { 5 return id; 6 } 7 freeBytes -= runLength(id); // 分配後剩餘的位元組數 8 return id; 9 }
說到這裡,記憶體模型的重點部分算是說完了。如果整個Netty系列有任何不對的地方,歡迎大家指出,我會虛心改正。
後面呢,我將打算將Spring的源碼的關鍵部分進行分析,期間也會穿插著對Redis的底層數據結構等重要內容進行分析。有需要的童鞋們,記得關注我,隨時可以獲取最新的消息。
謝謝。