Spark3.0YarnCluster模式任務提交流程源碼分析
1.通過spark-submit腳本提交spark程式
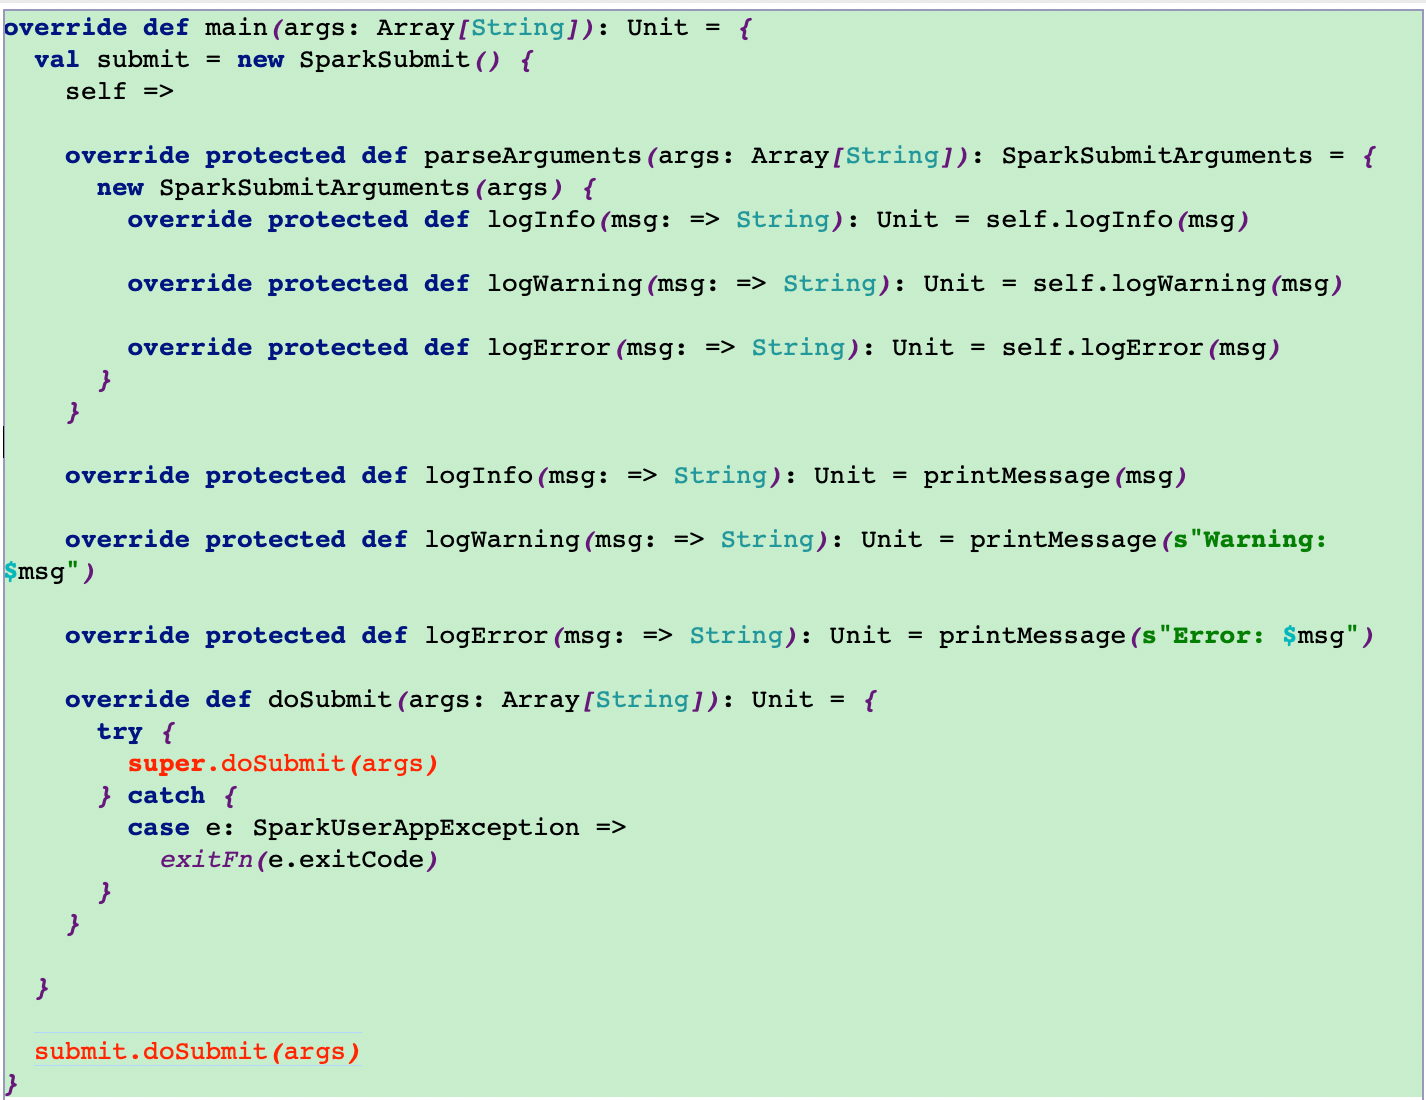
在spark-submit腳本裡面執行了SparkSubmit類的main方法

2.運行SparkSubmit類的main方法
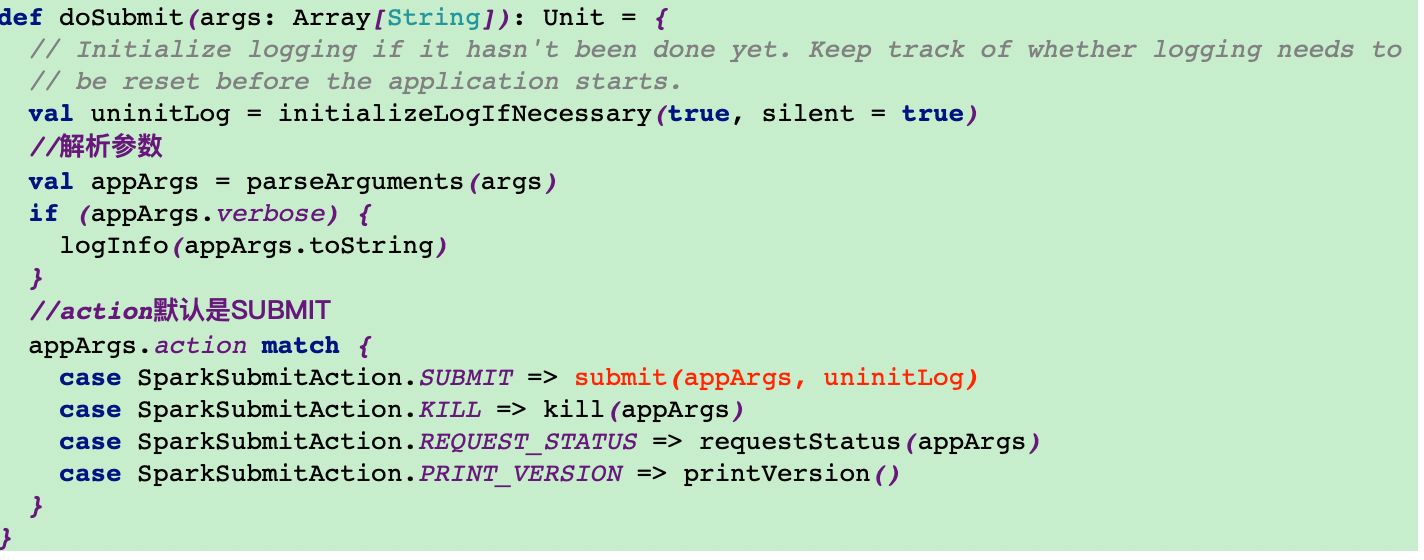
3.調用doSubmit方法
4.調用submit方法
在submit方法里調用doRunMain方法,最終調用runMain方法
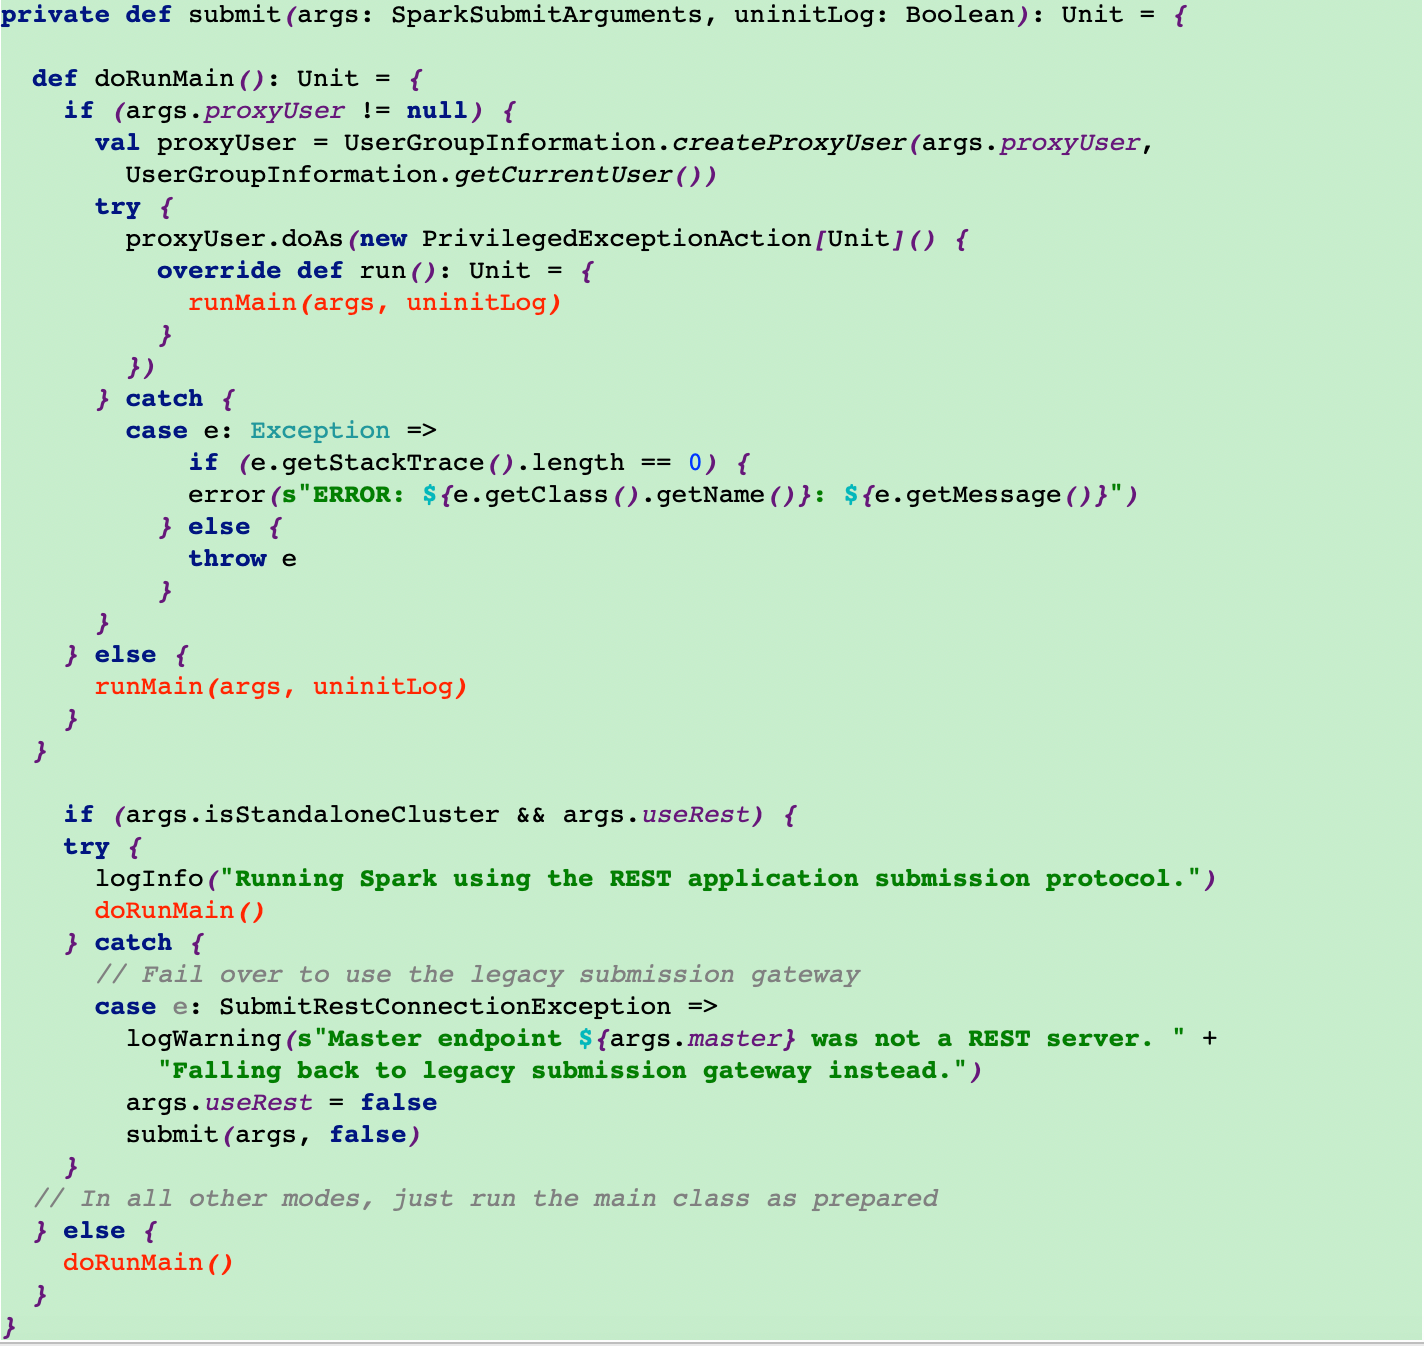
5.在runMain方法裡面獲取mainClass,再去執行start方法
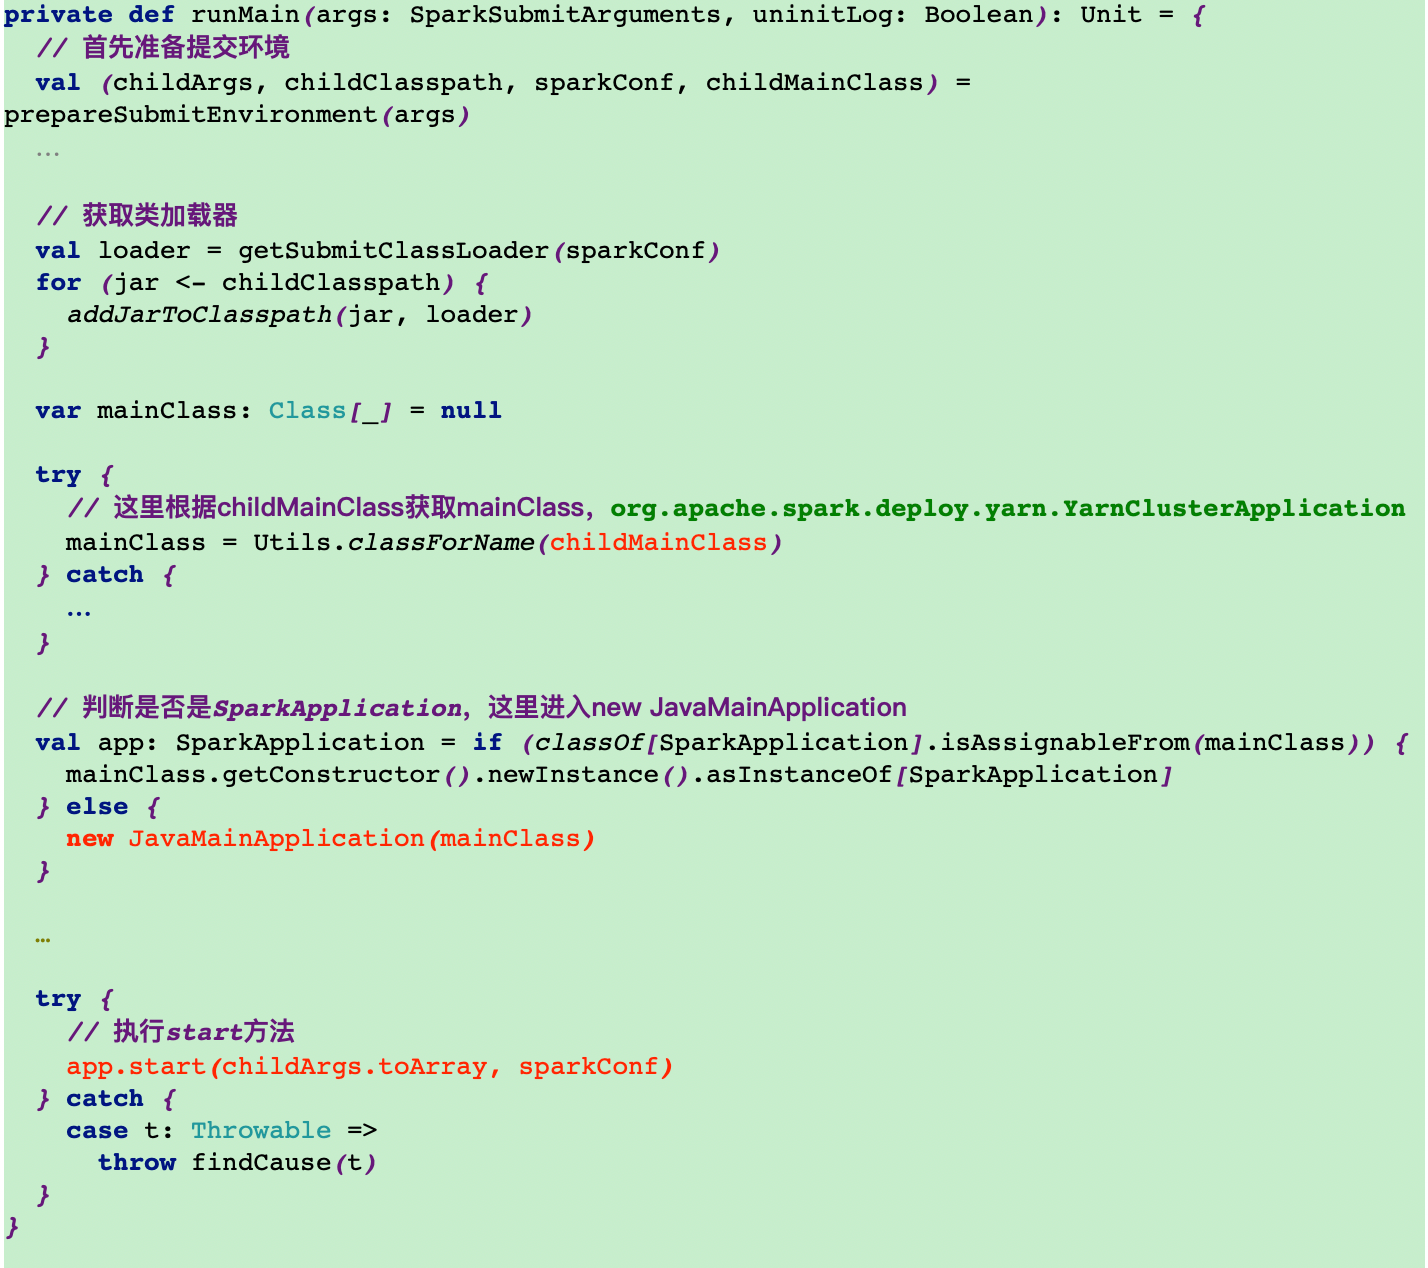
在這裡根據提交模式來選擇mainClass
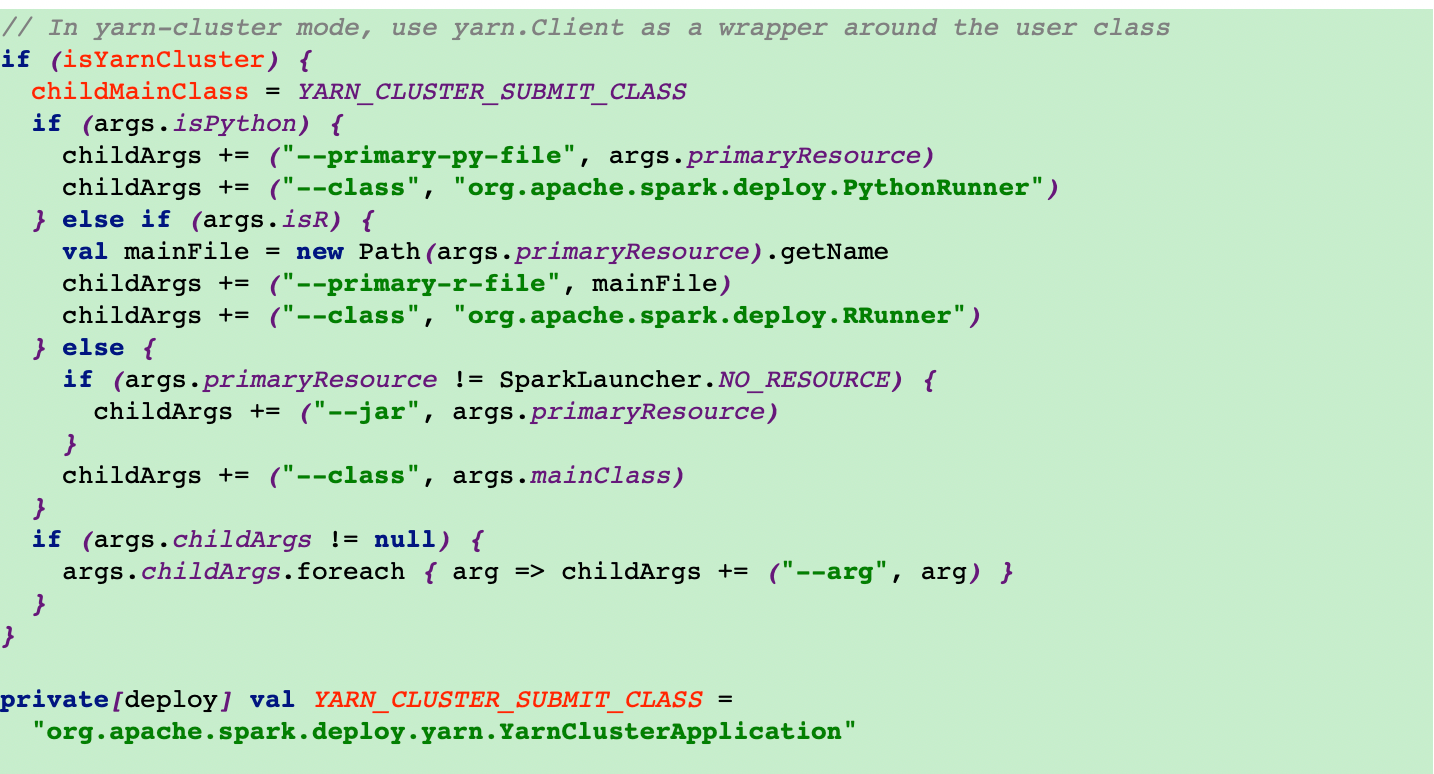
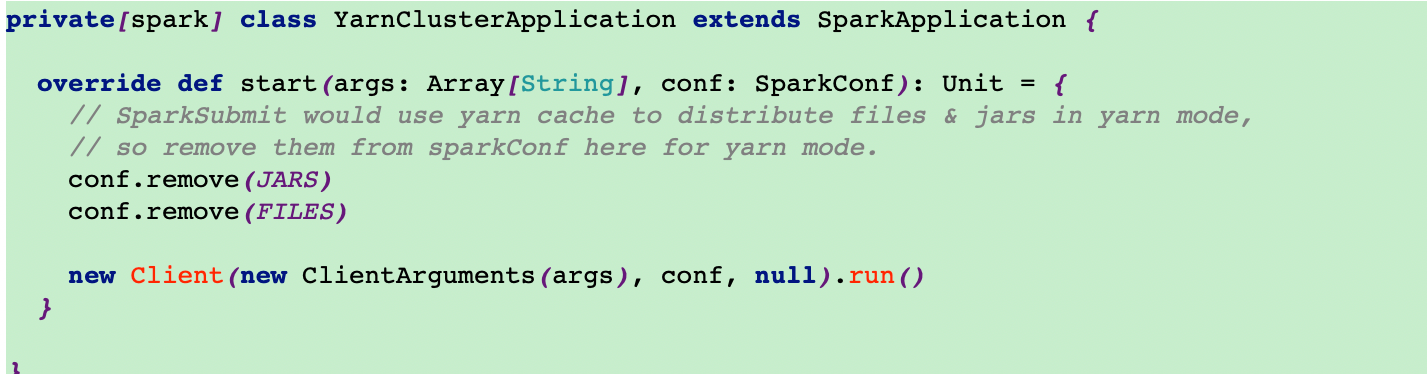
6.在start方法裡面去調用YarnClusterApplication的start方法
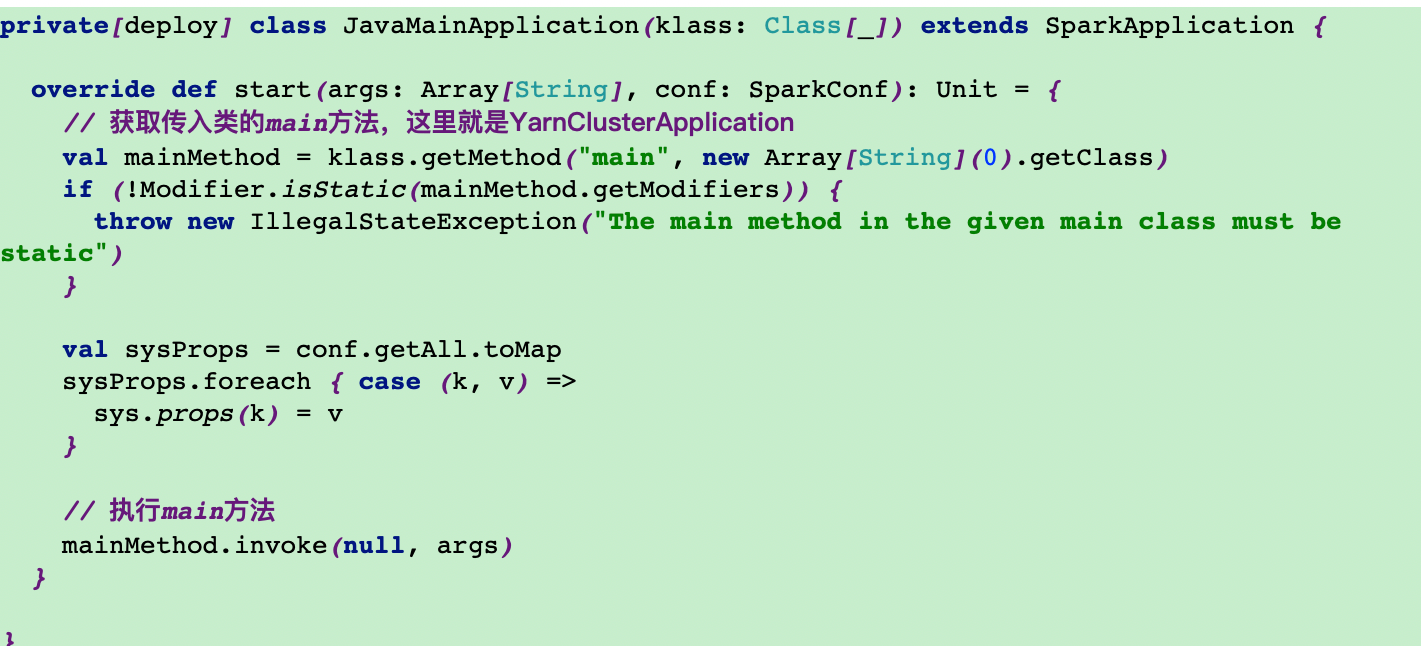
7.YarnClusterApplication方法裡面new一個yarnClient對象,並執行run方法
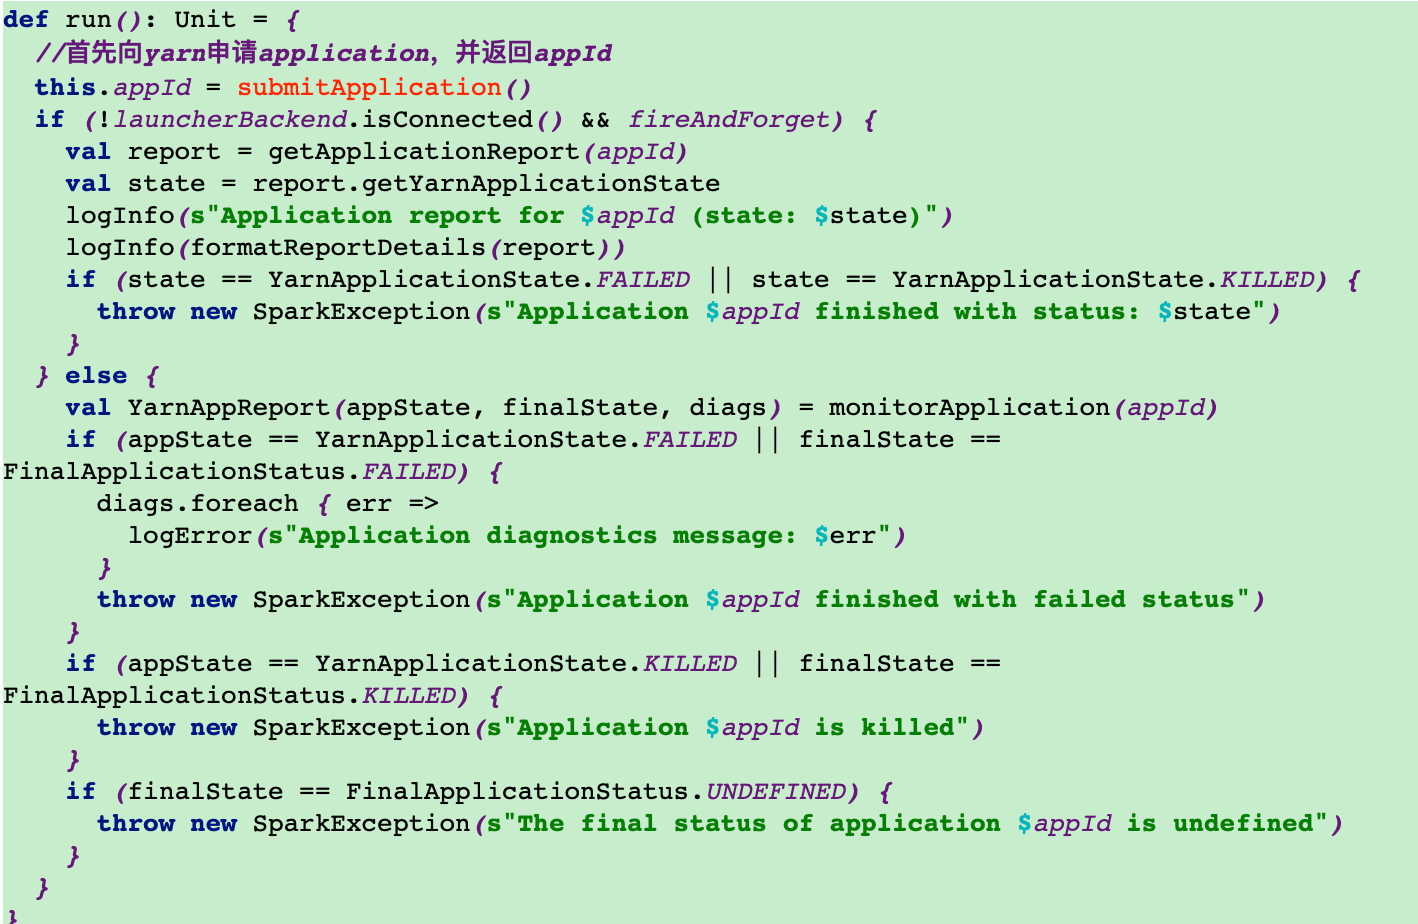
8.run方法里執行submitApplication提交application
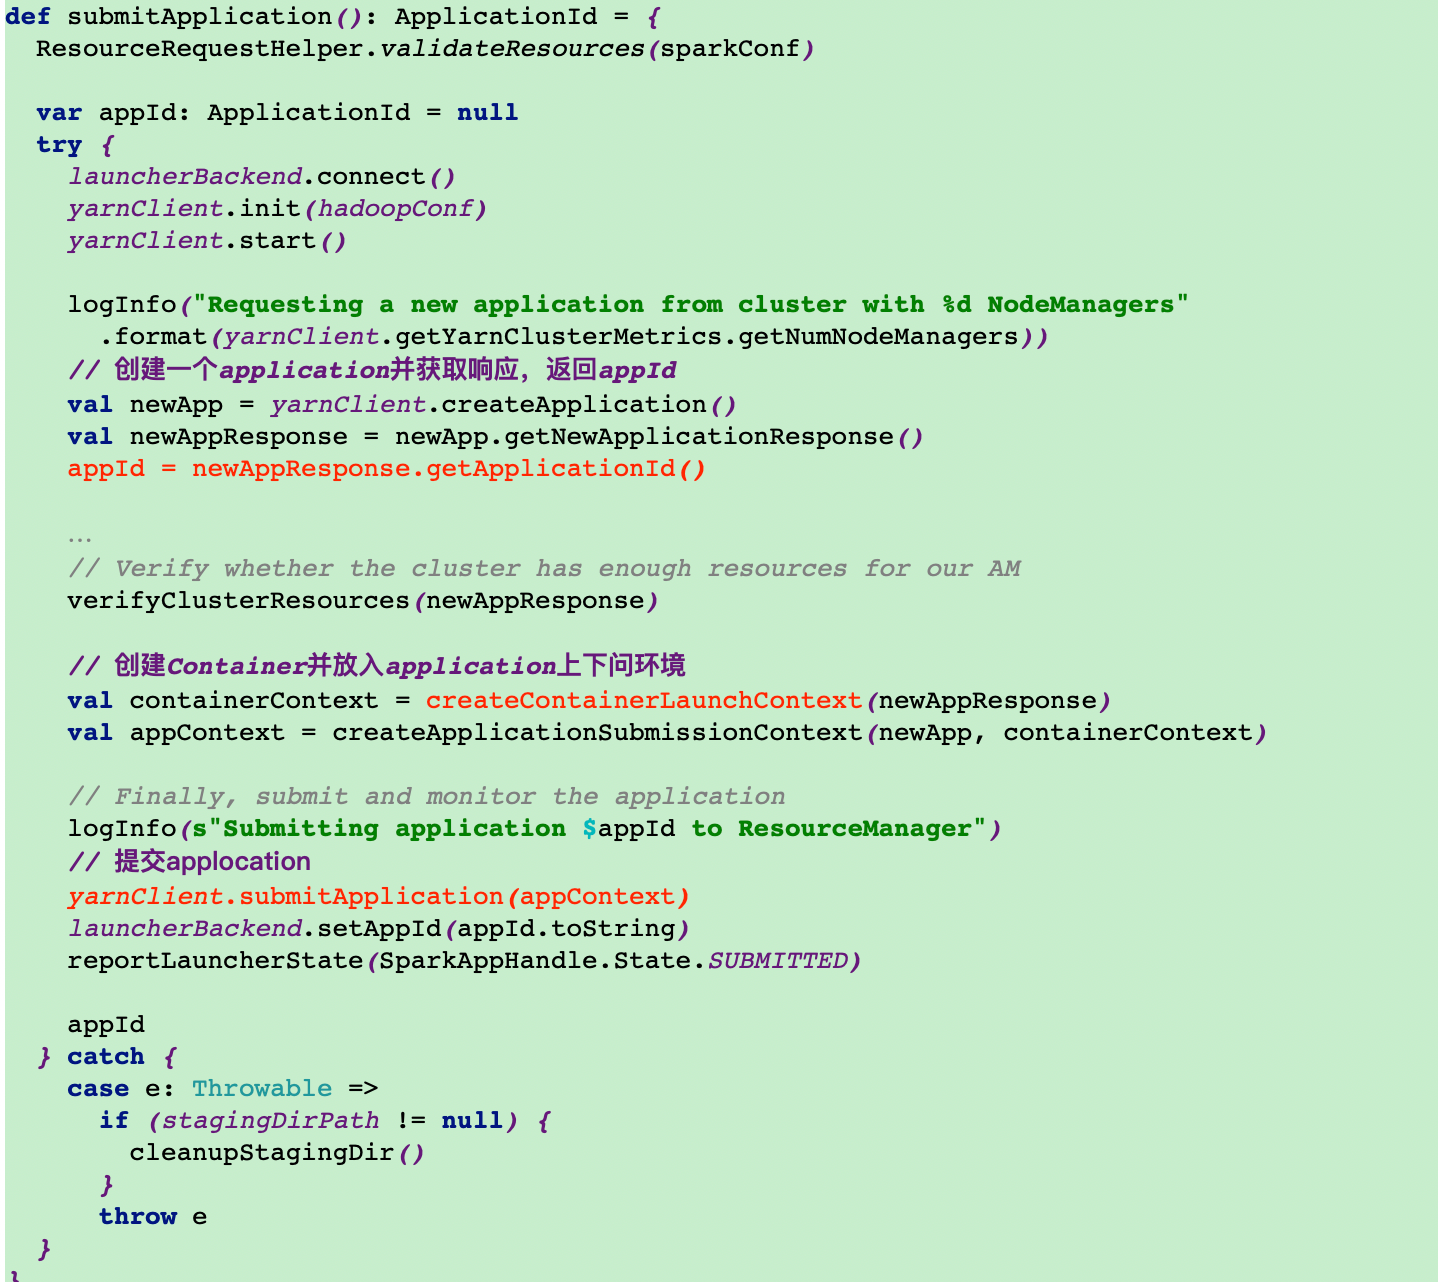
9.submitApplication方法里首先會去請求RM並返回一個appId,然後創建container和application上下文環境並執行submitApplication提交application
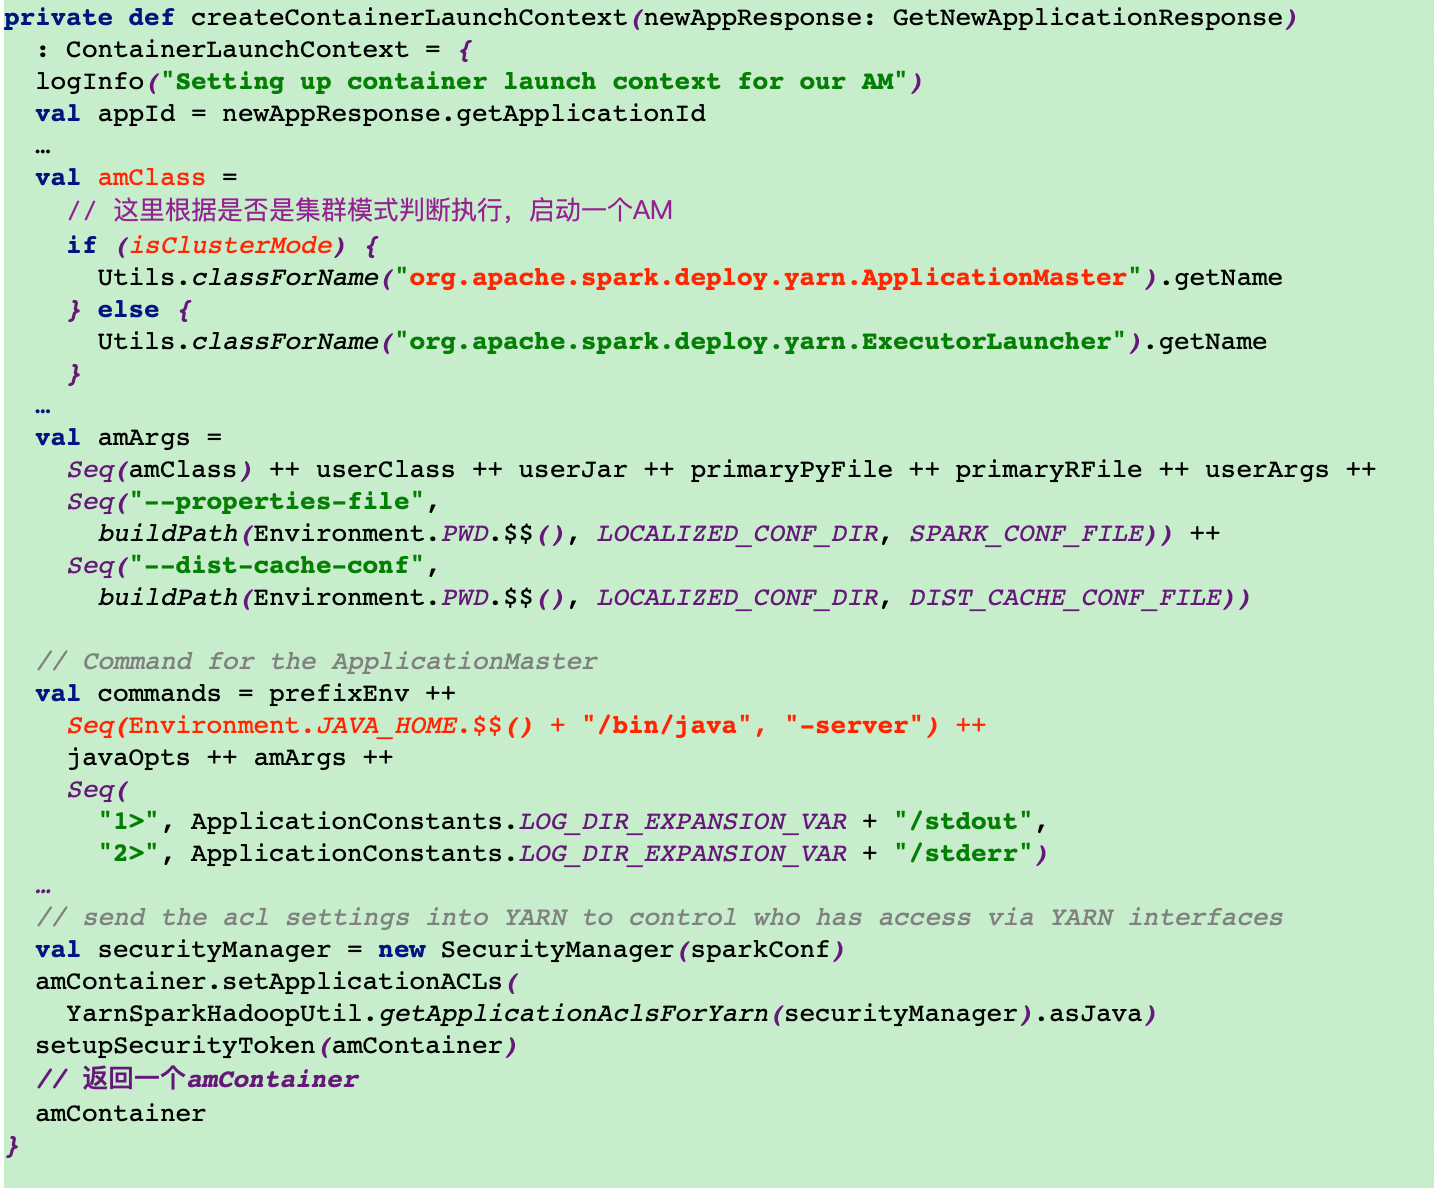
這裡通過createContainerLaunchContext方法啟動了ApplicationMaster
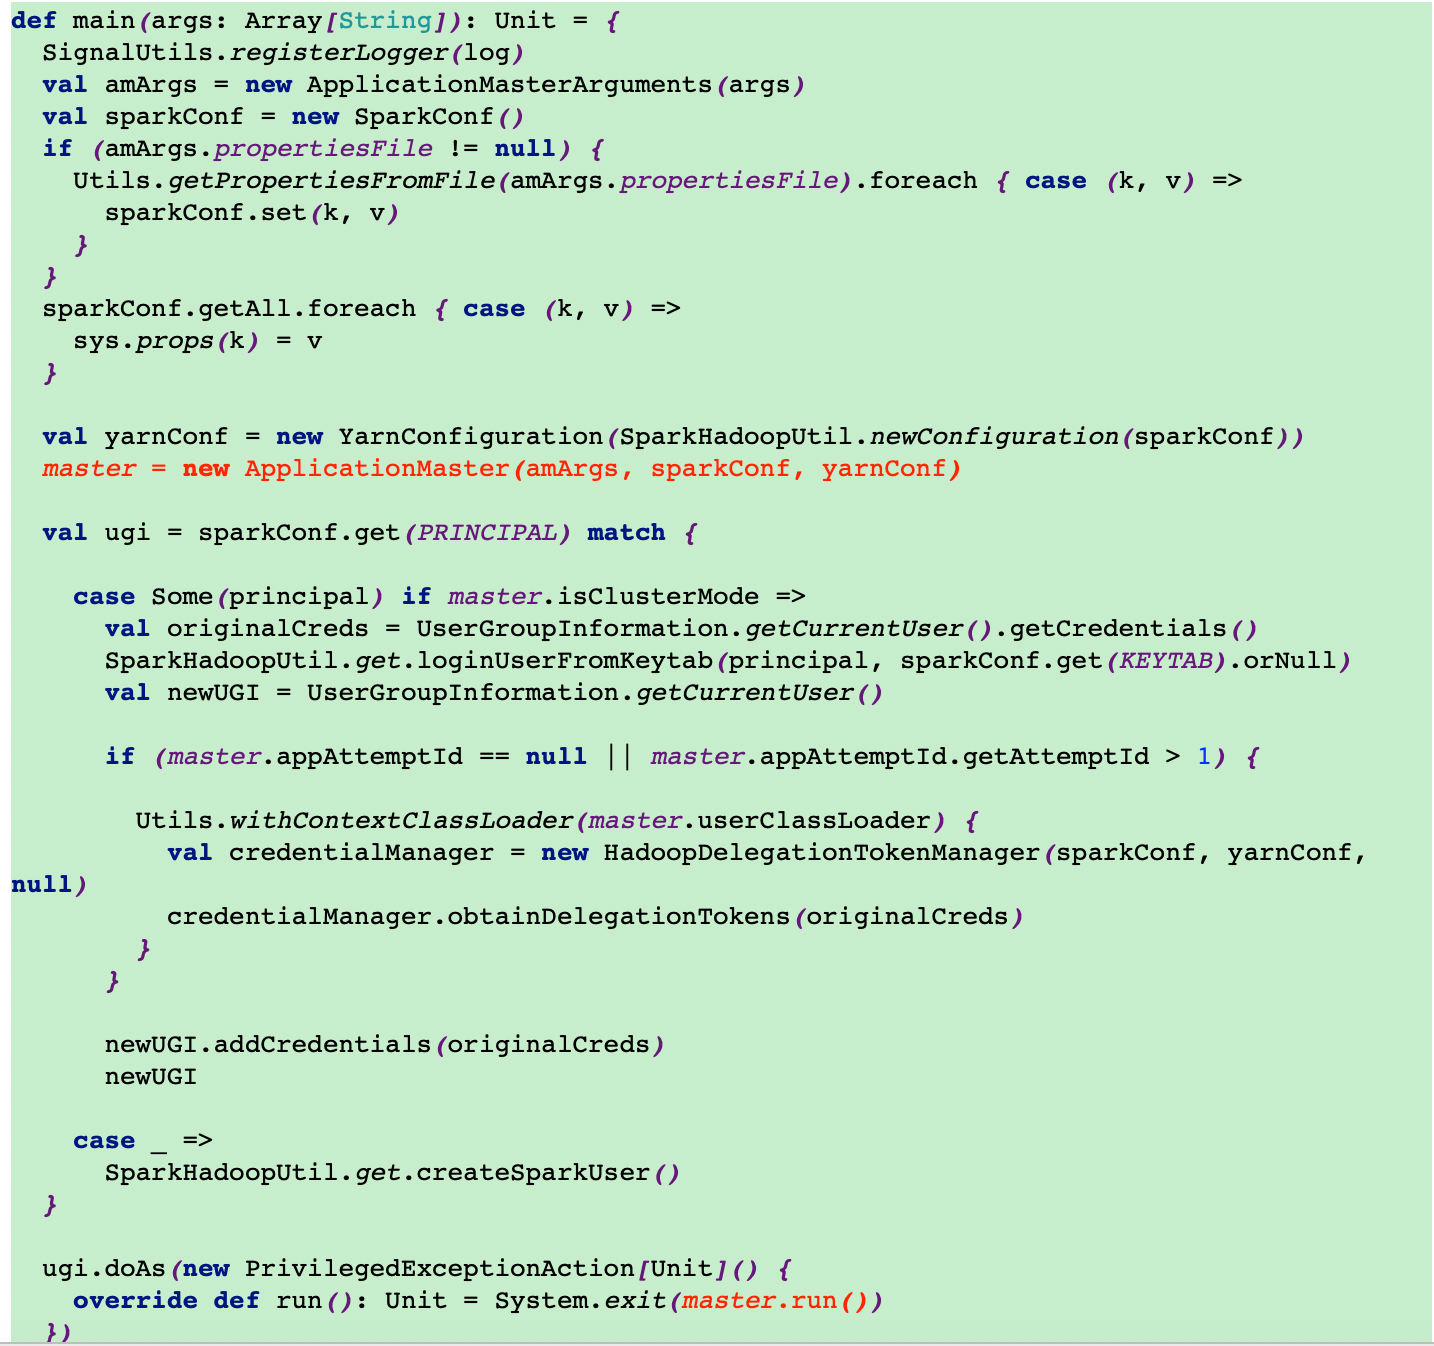
10.調用ApplicationMaster類的main方法
在這裡首先new一個ApplicationMaster,然後調用了master的run方法
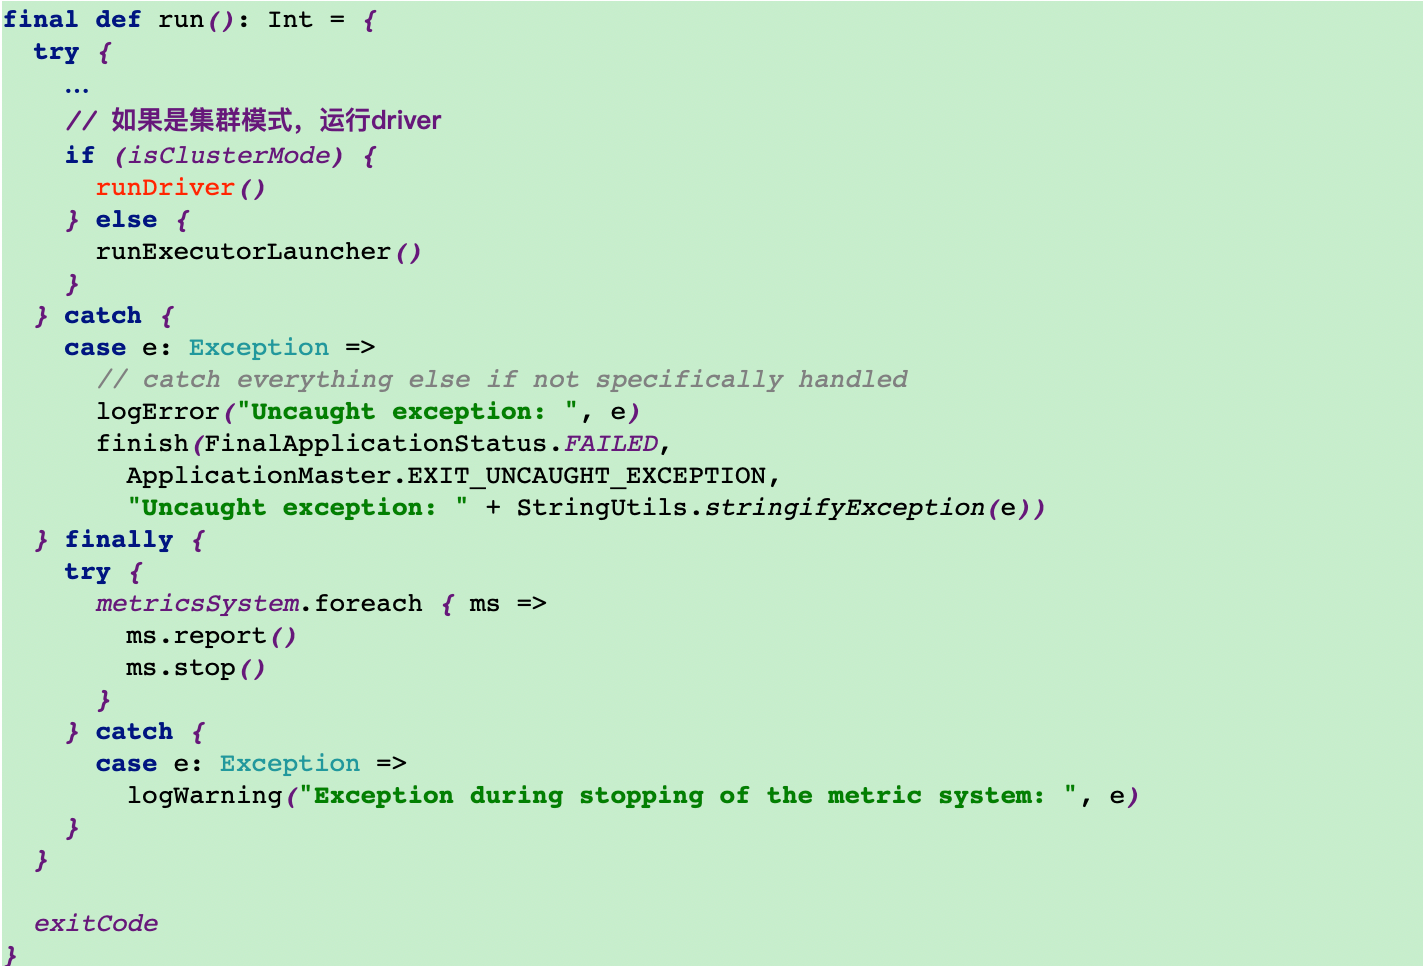
11.調用ApplicationMaster的run方法
這裡會根據是否是集群模式執行不同的方法
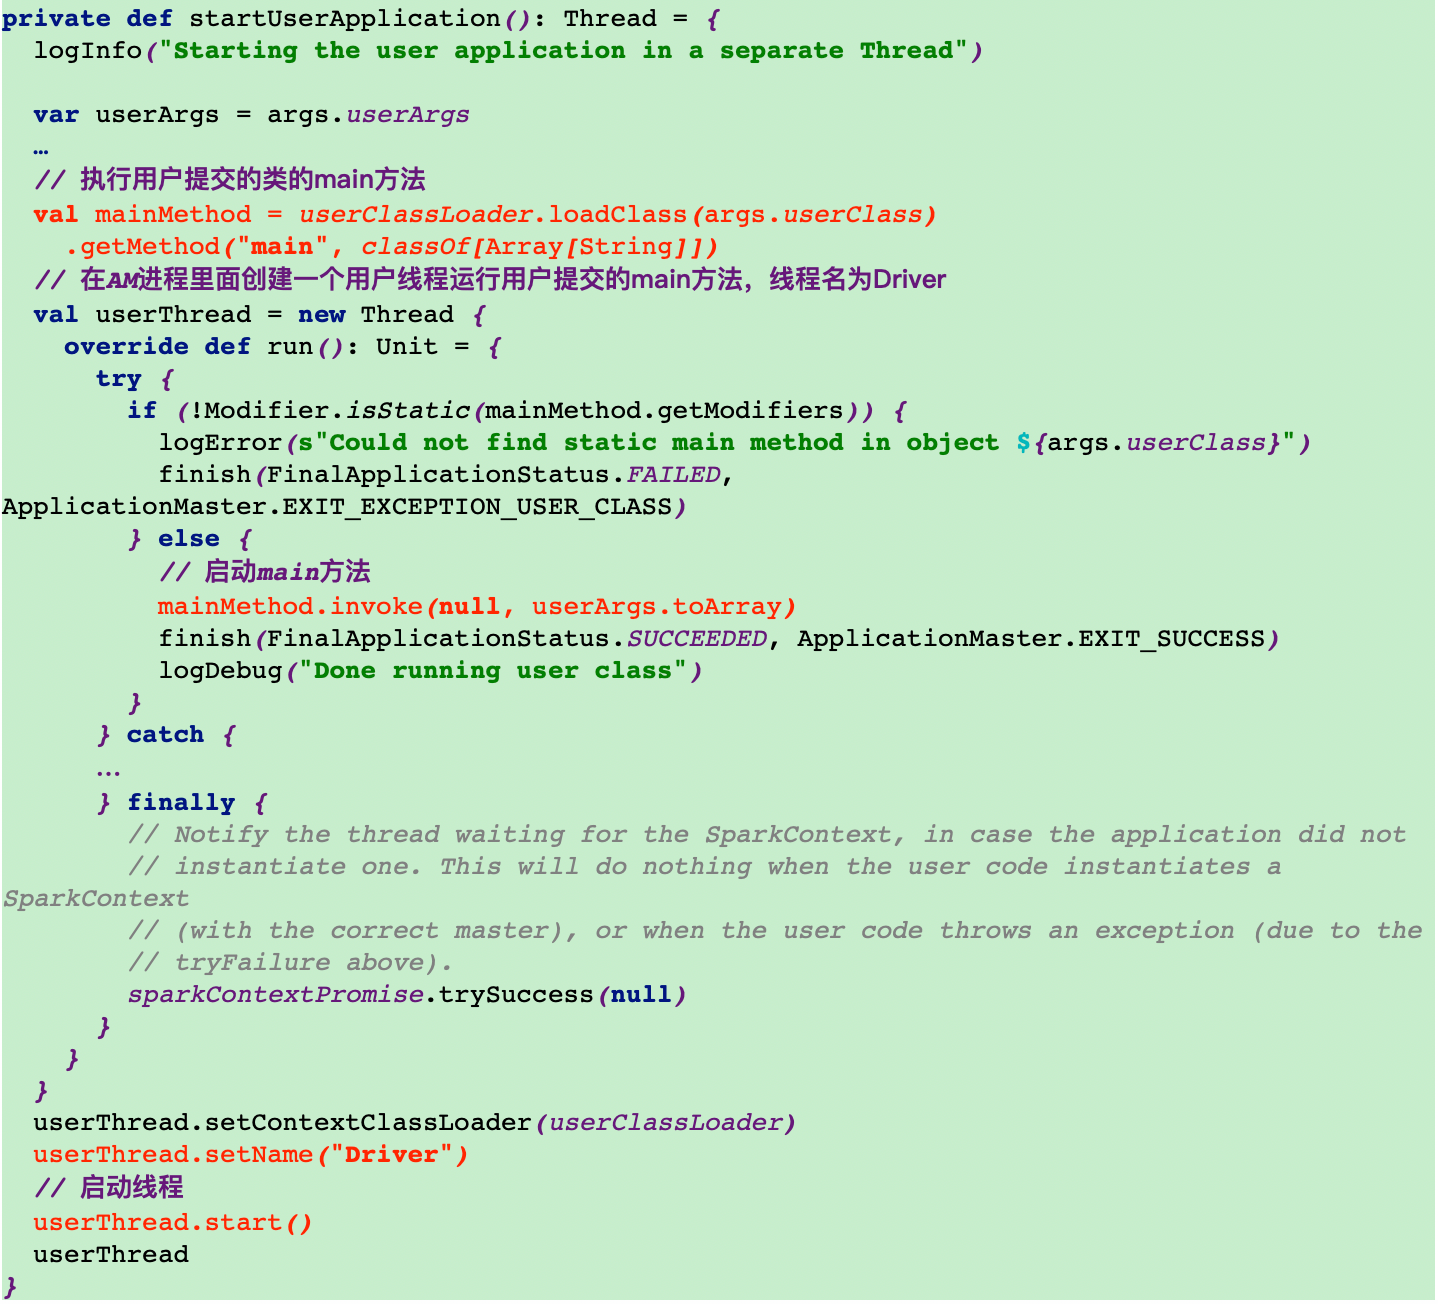
12.調用runDriver方法
12.1調用startUserApplication方法啟動一個driver執行緒
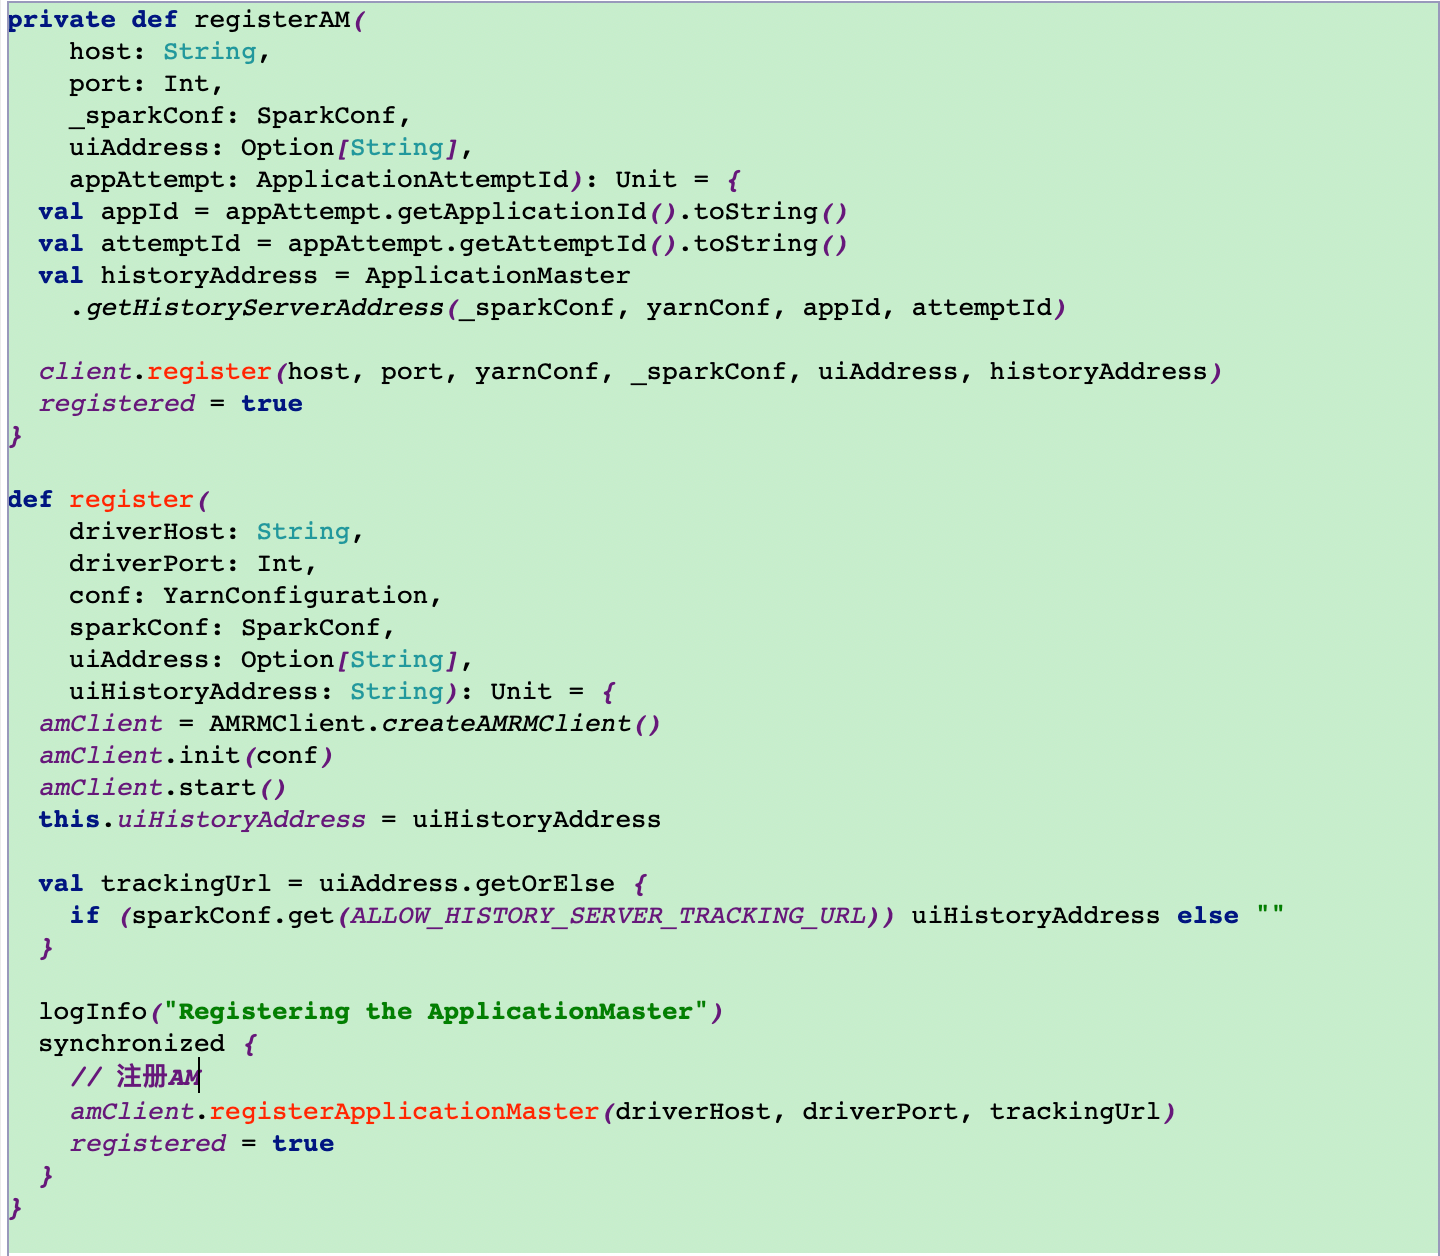
12.2將AM註冊到RM
12.3分配資源
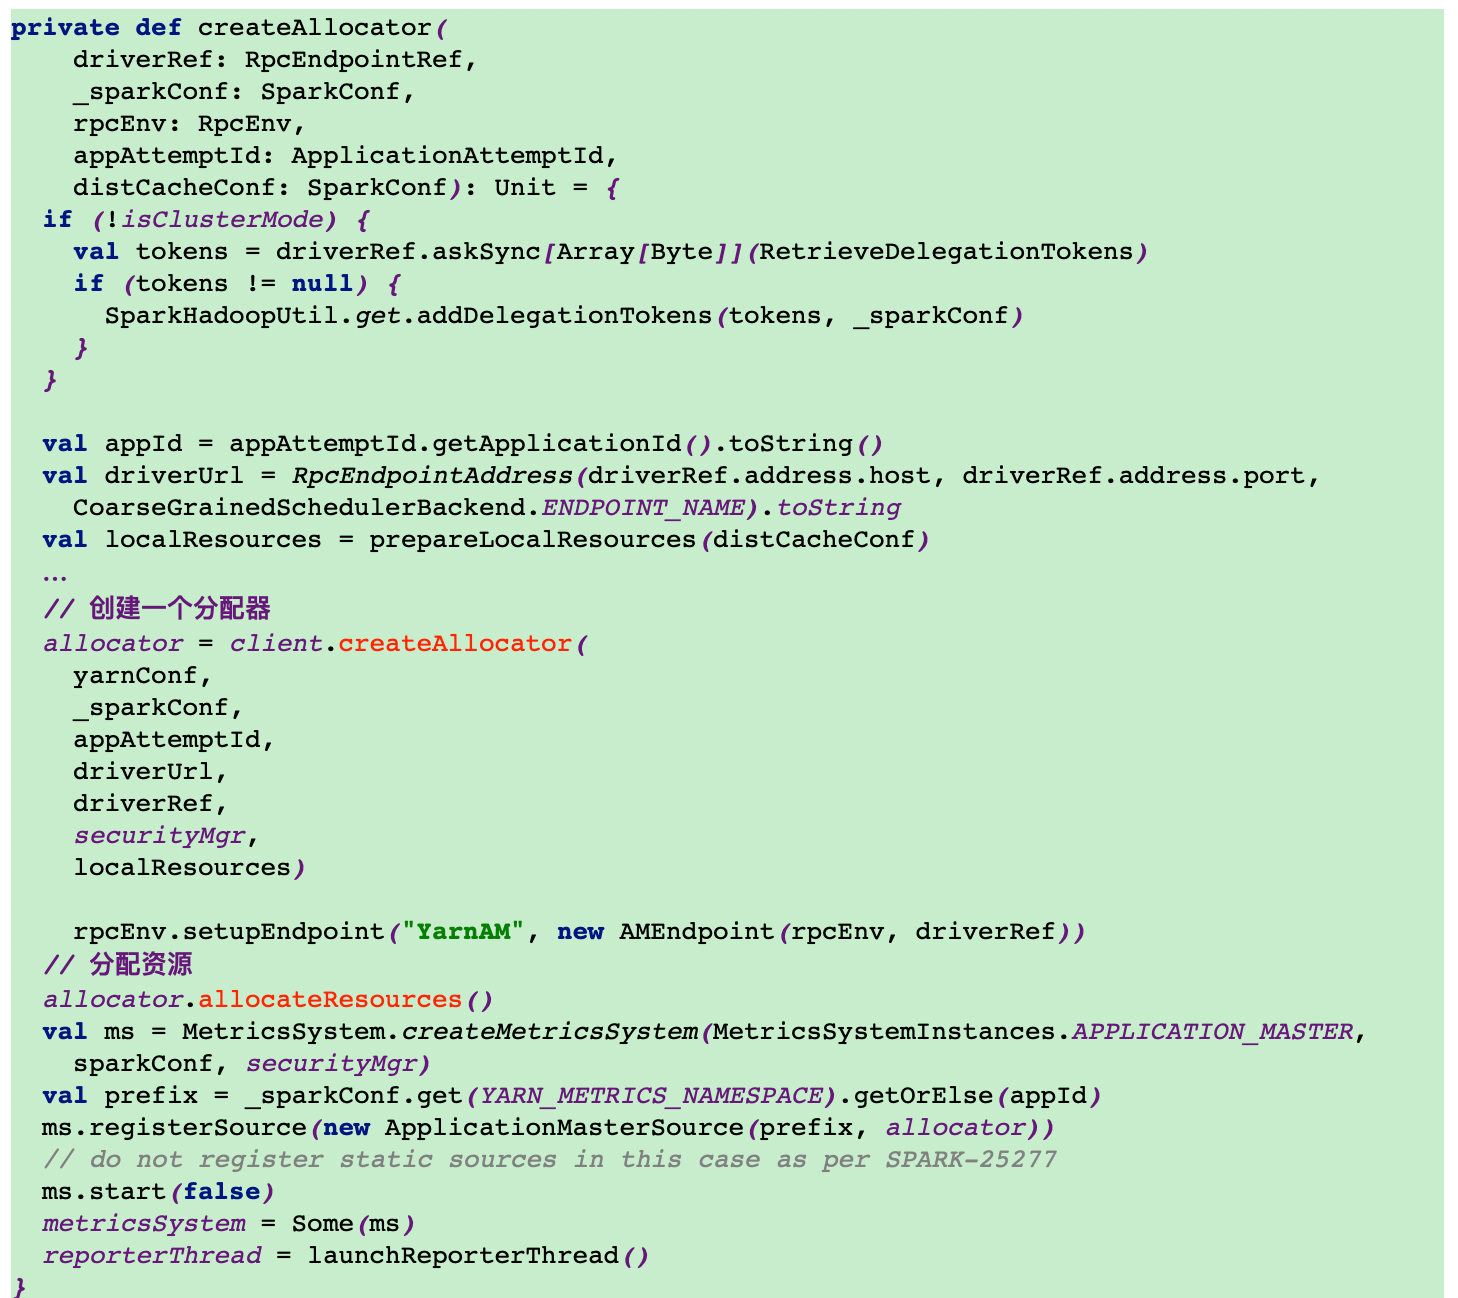
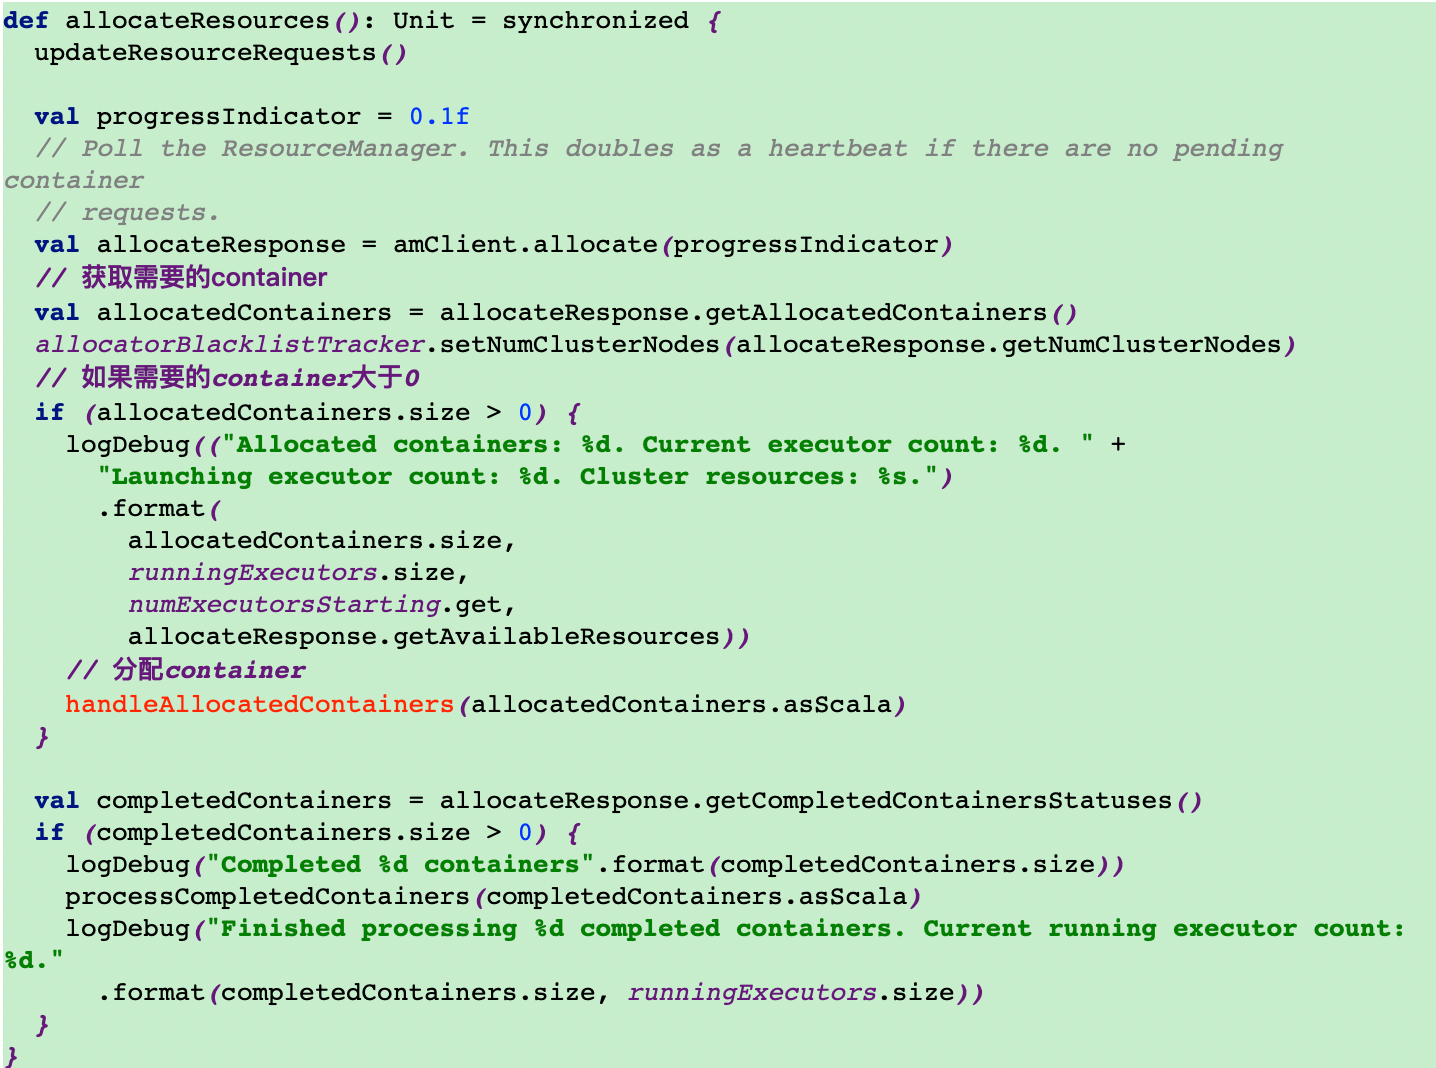
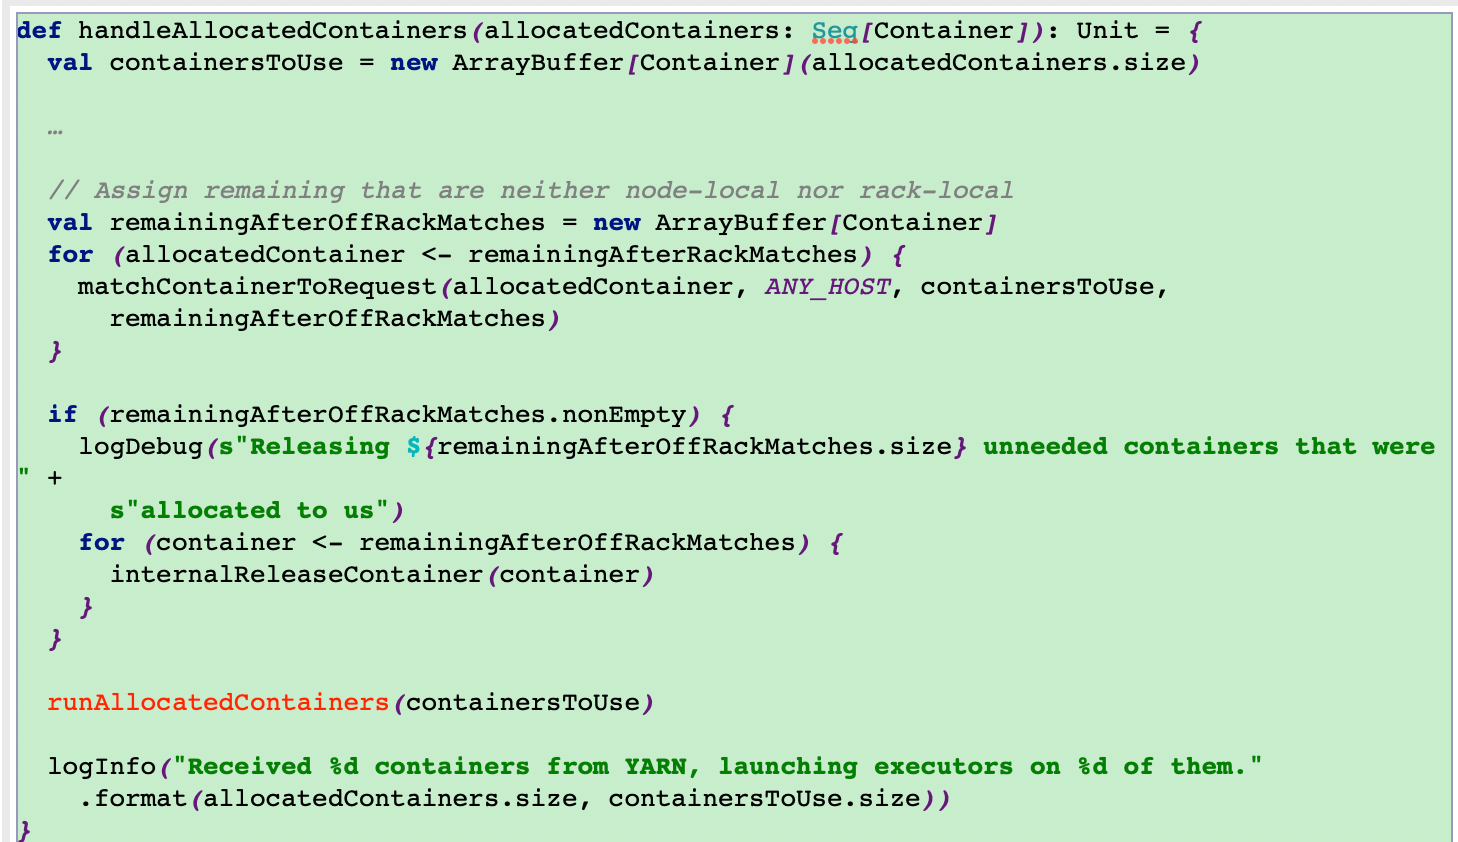
這裡通過調用runAllocatedContainers方法在分配的container裡面運行executors
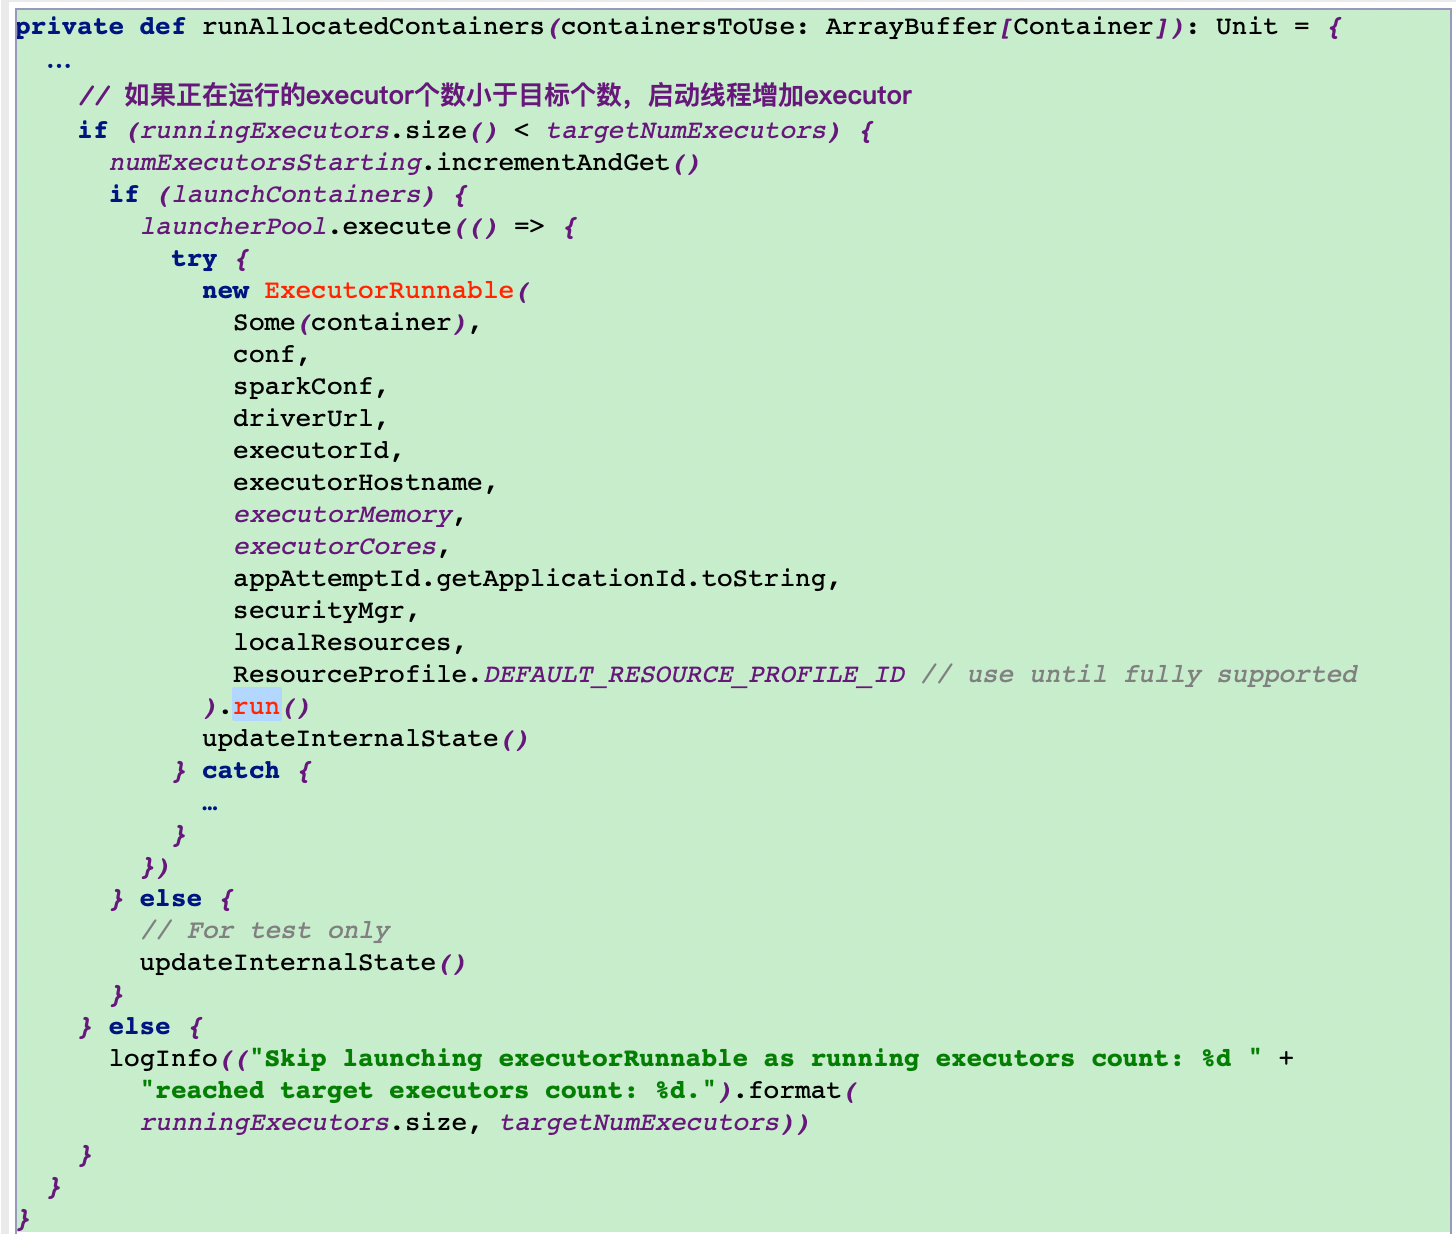
12.4調用ExecutorRunnable的run方法,然後調用run方法裡面的startContainer方法來啟動executor
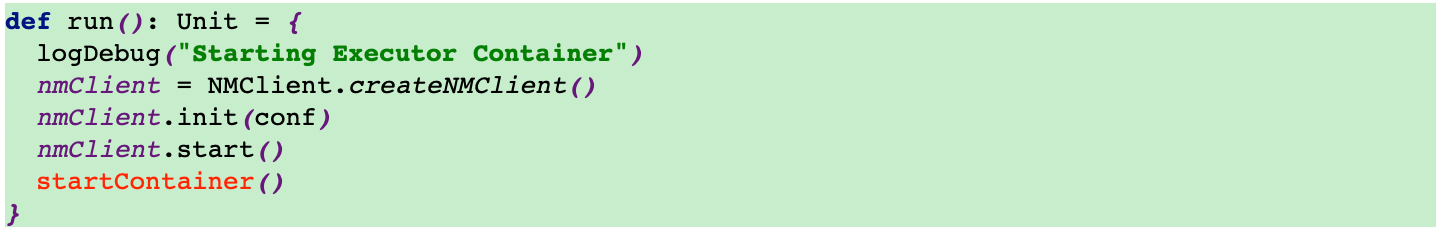
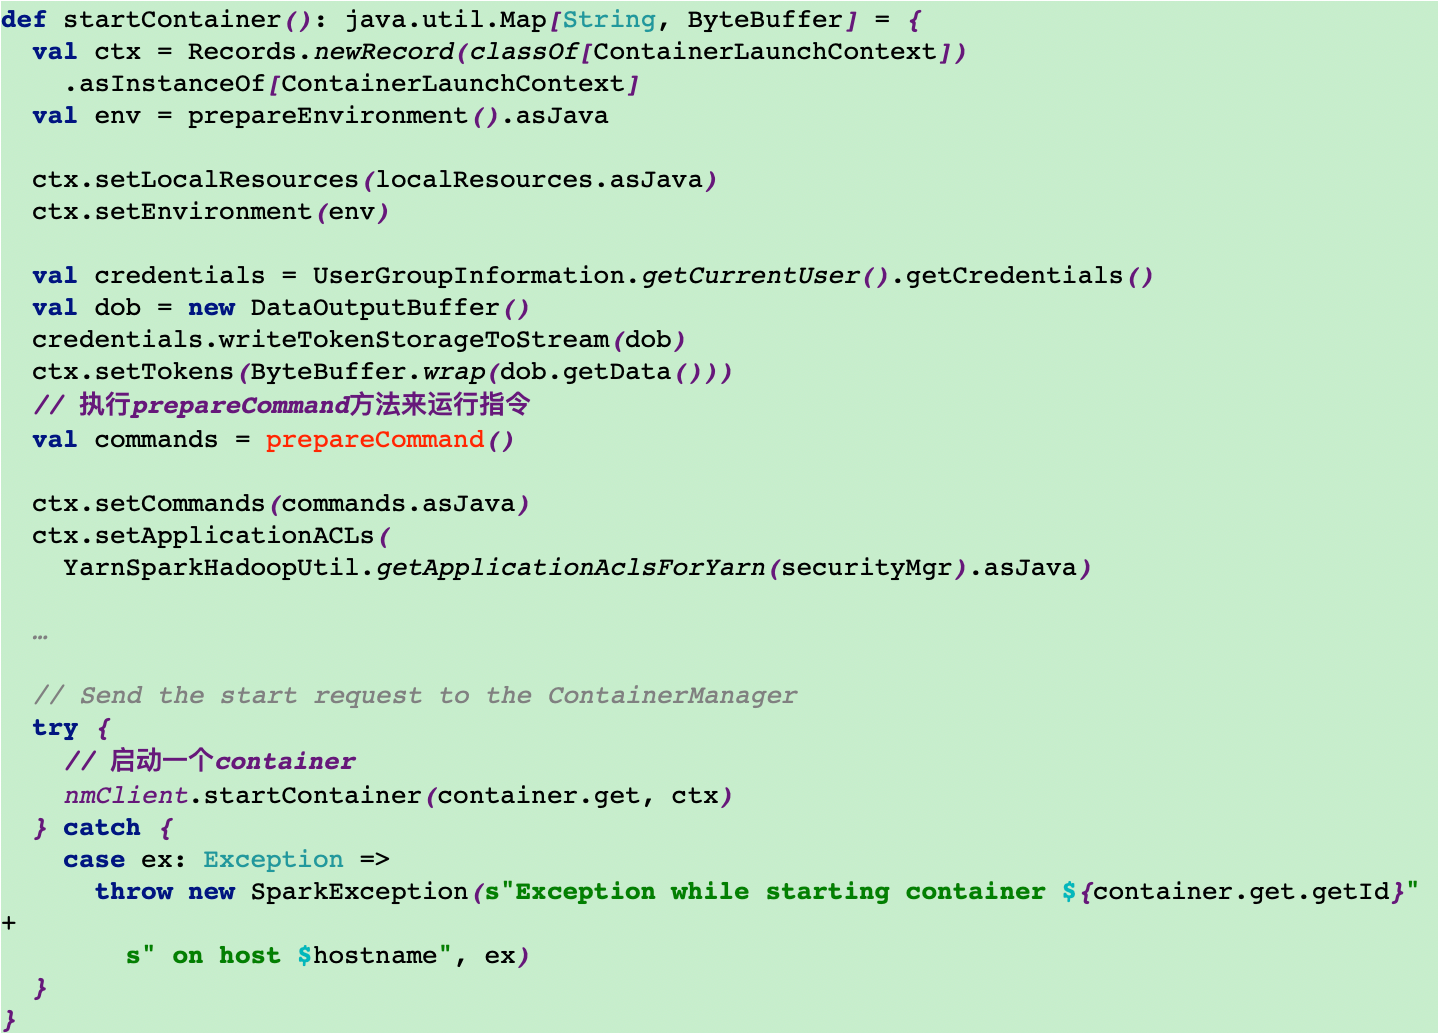
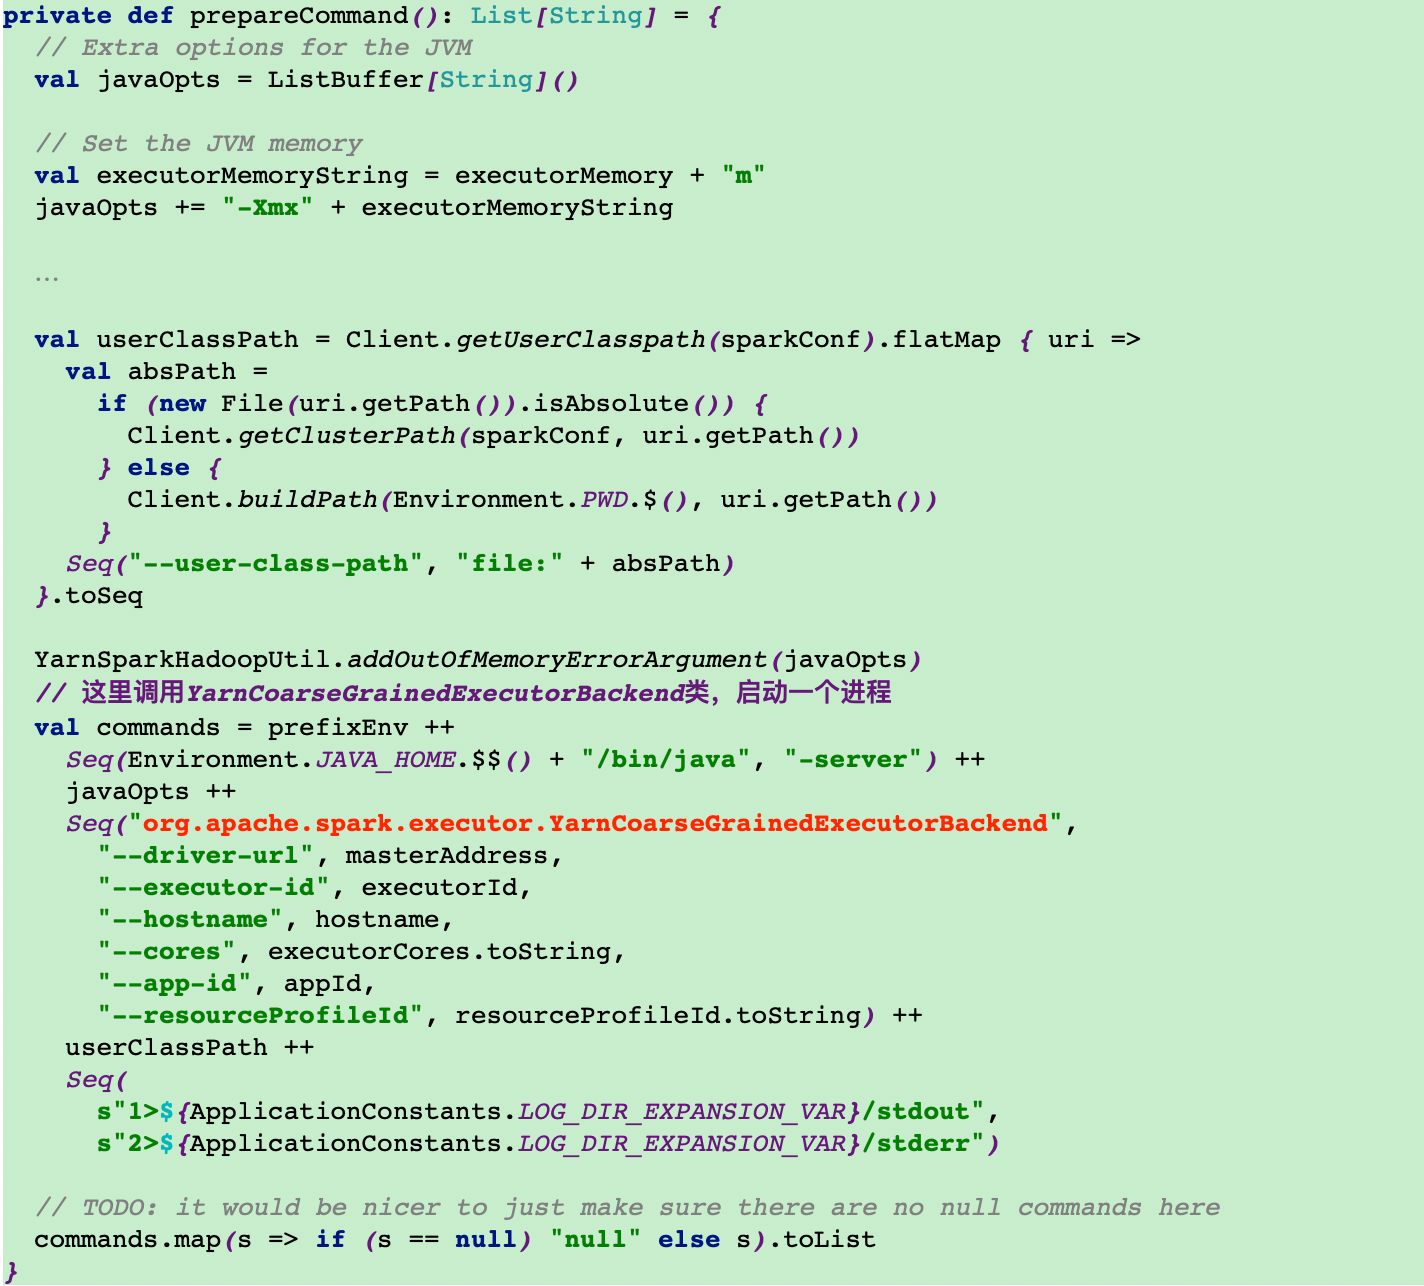
12.5調用prepareCommand方法來運行org.apache.spark.executor.YarnCoarseGrainedExecutorBackend類
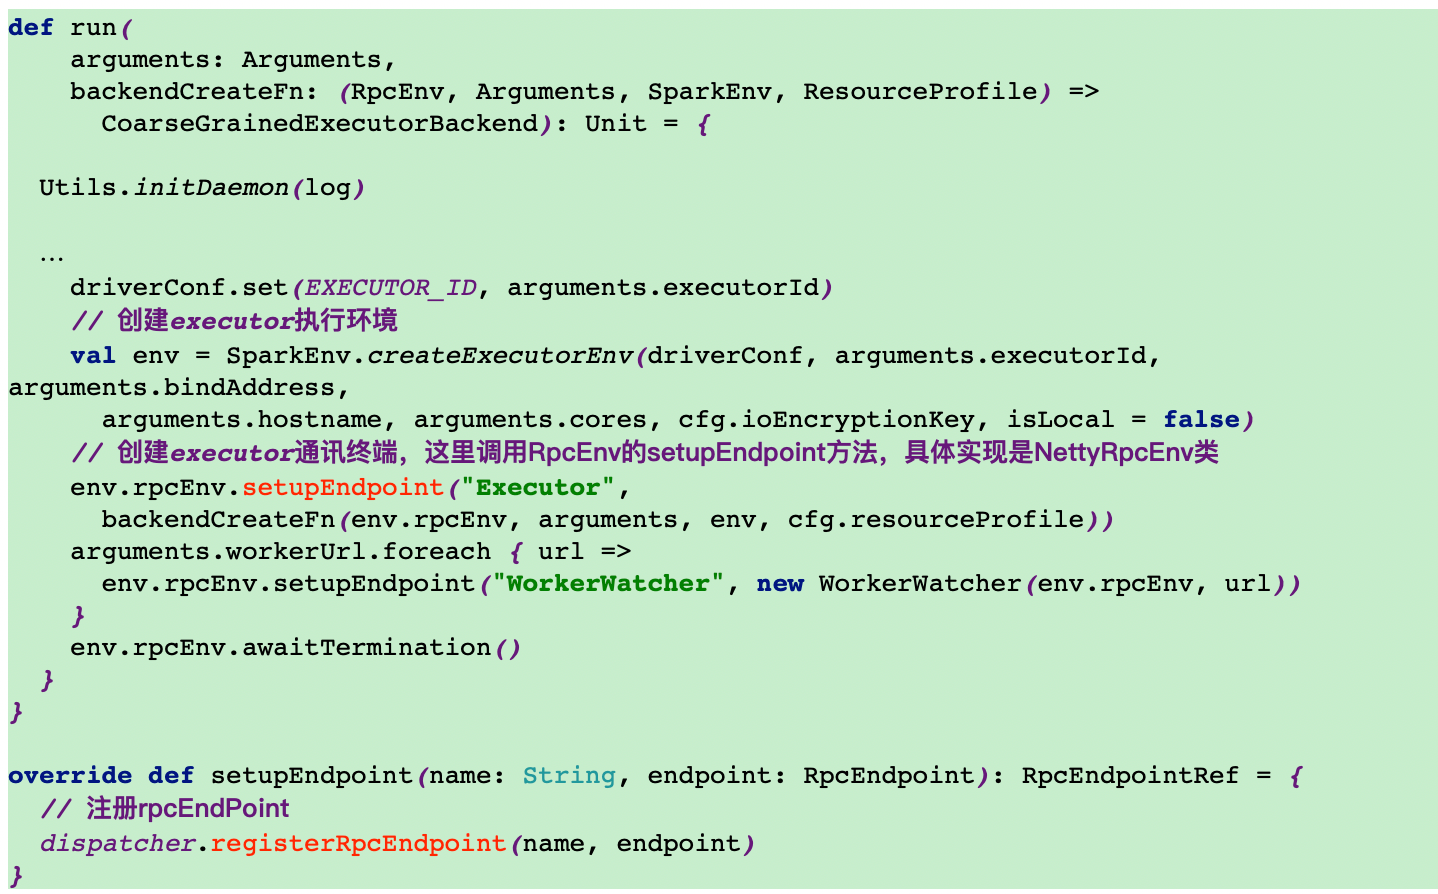
13.執行YarnCoarseGrainedExecutorBackend類main方法的run方法創建executor終端
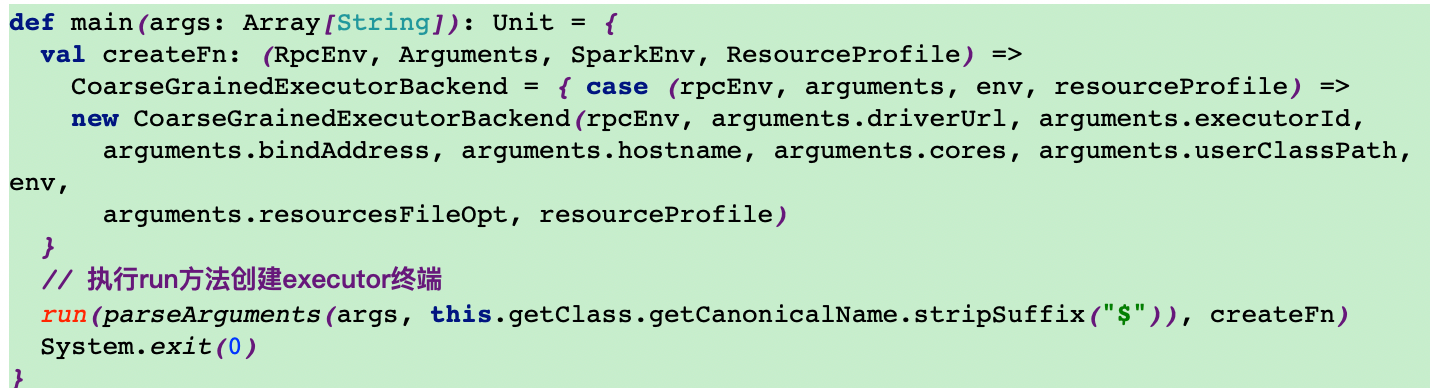
14.調用setupEndpoint創建executor終端
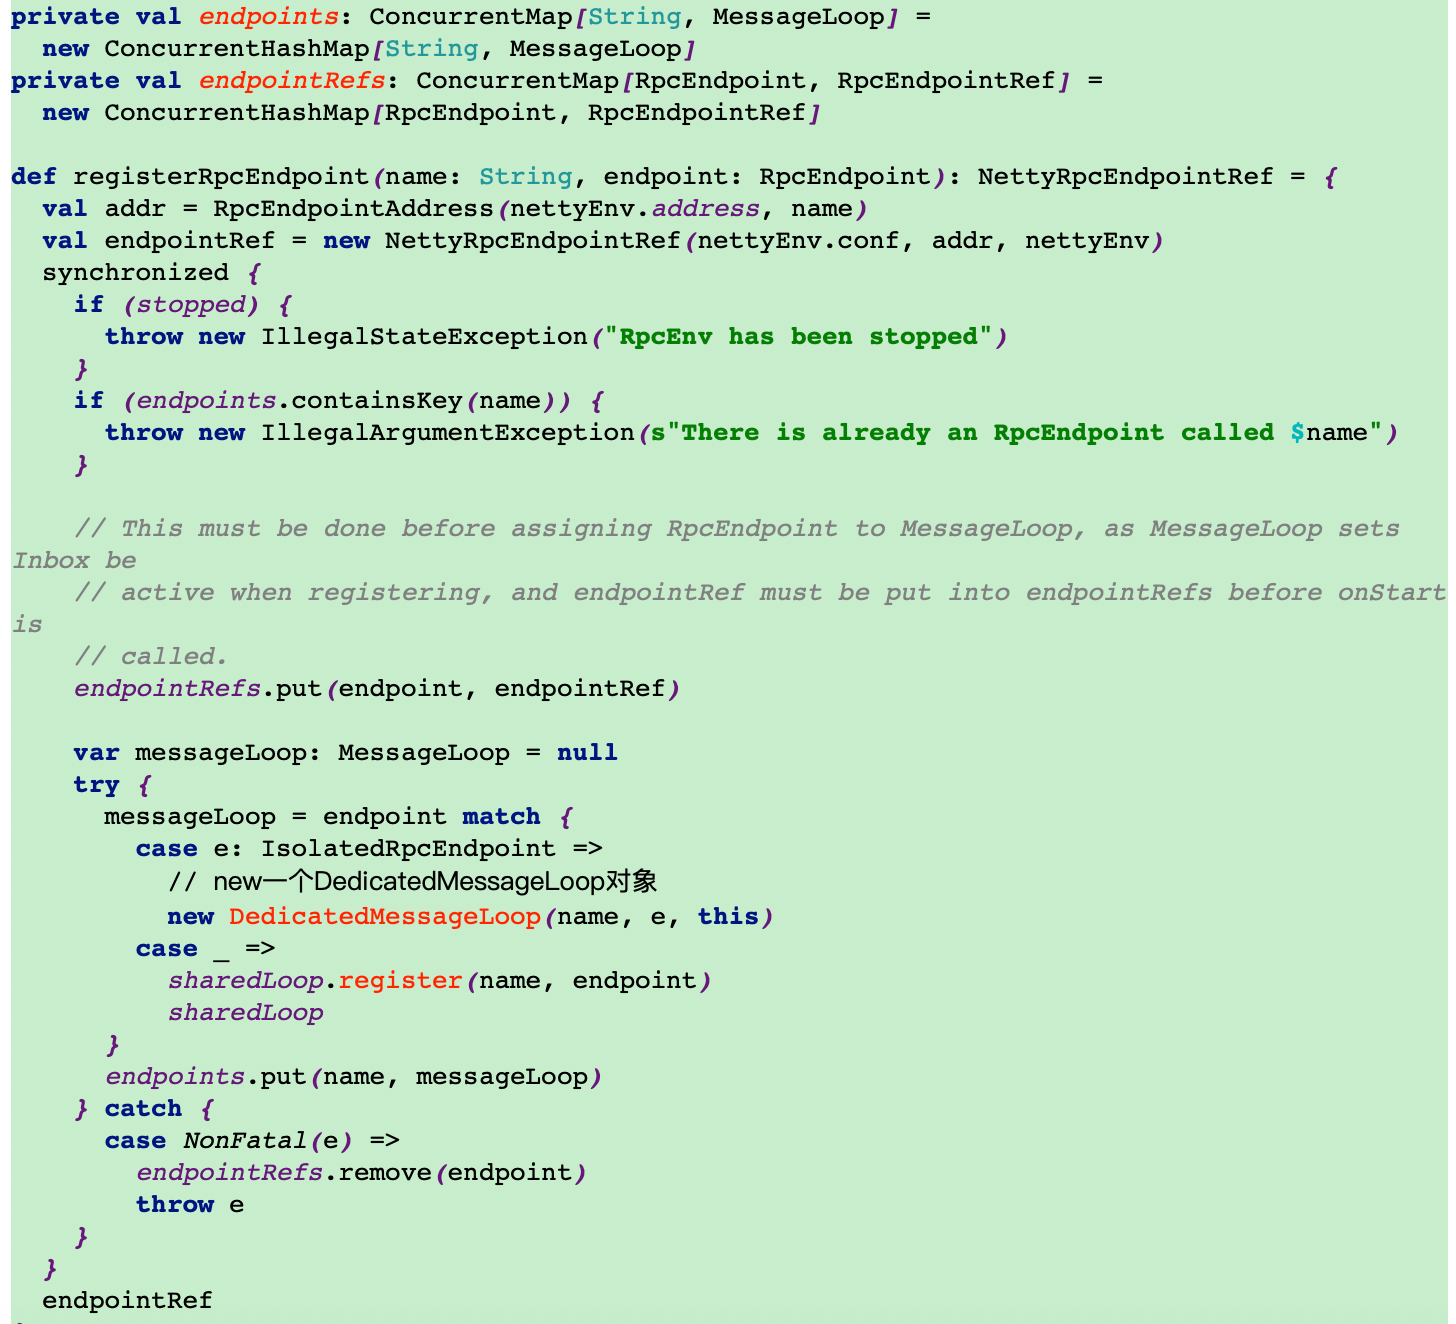
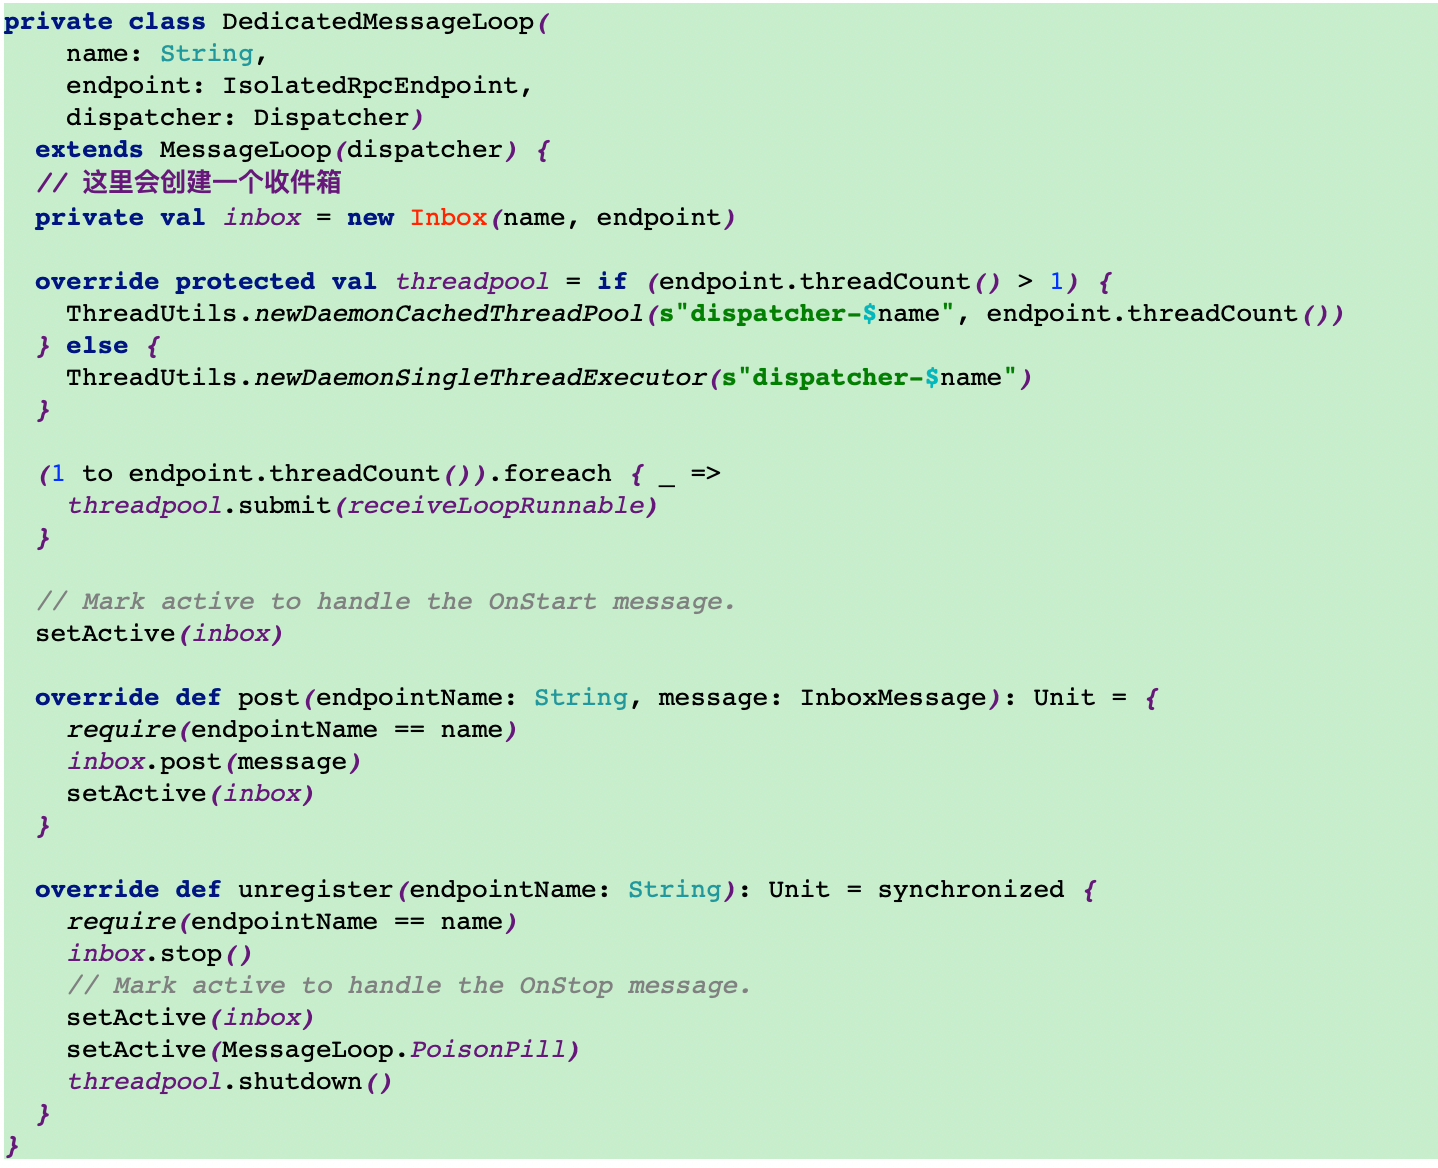
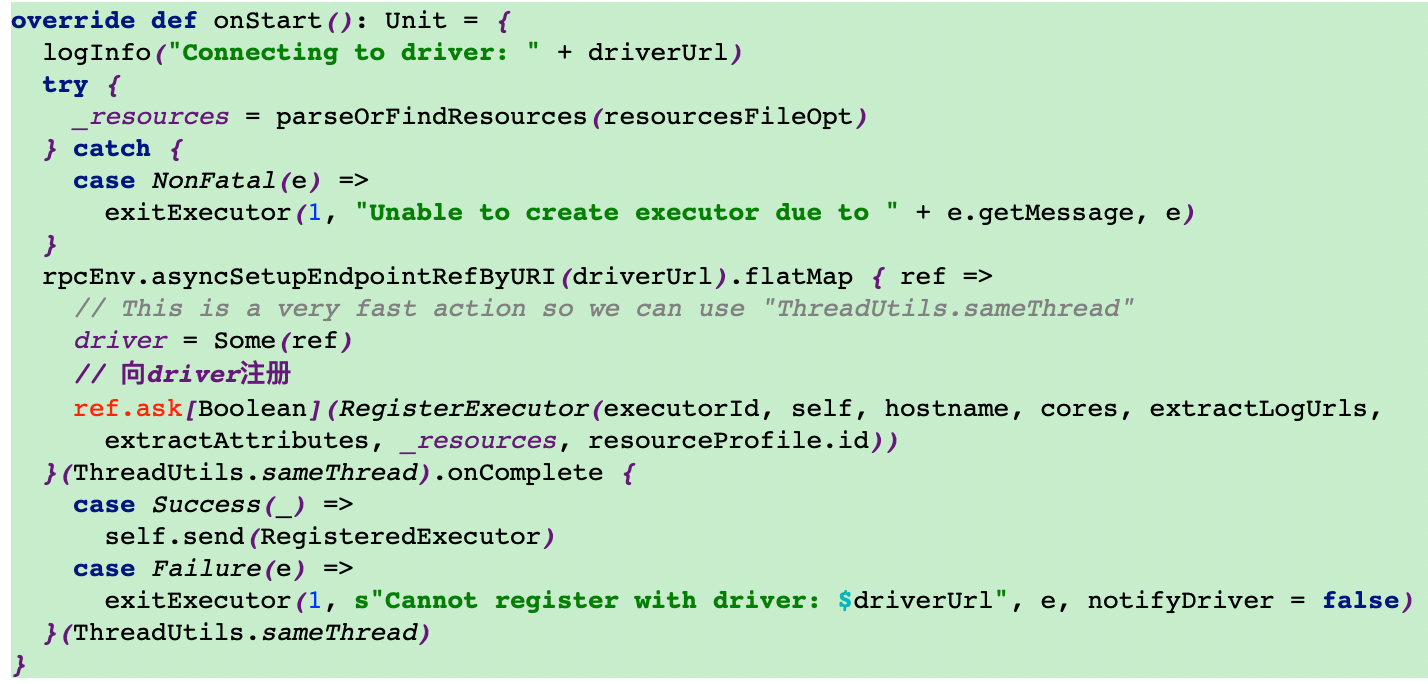
15.反向註冊executor到driver
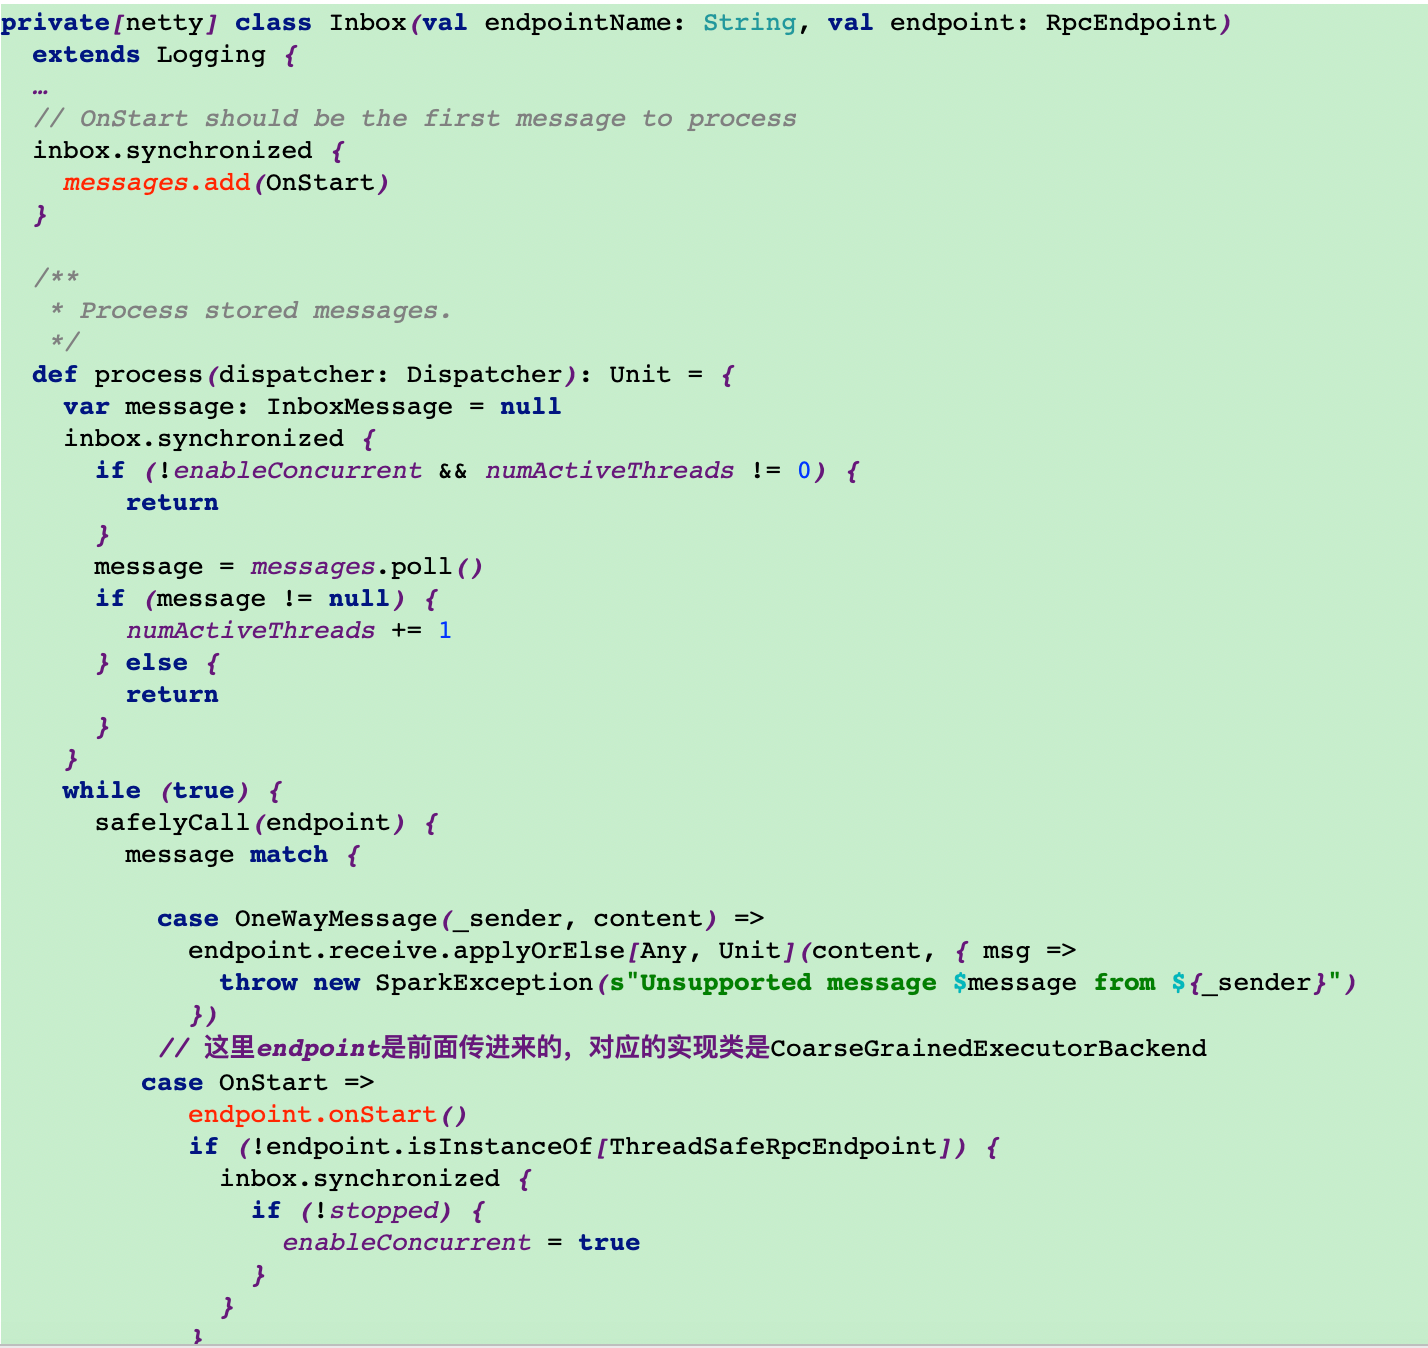
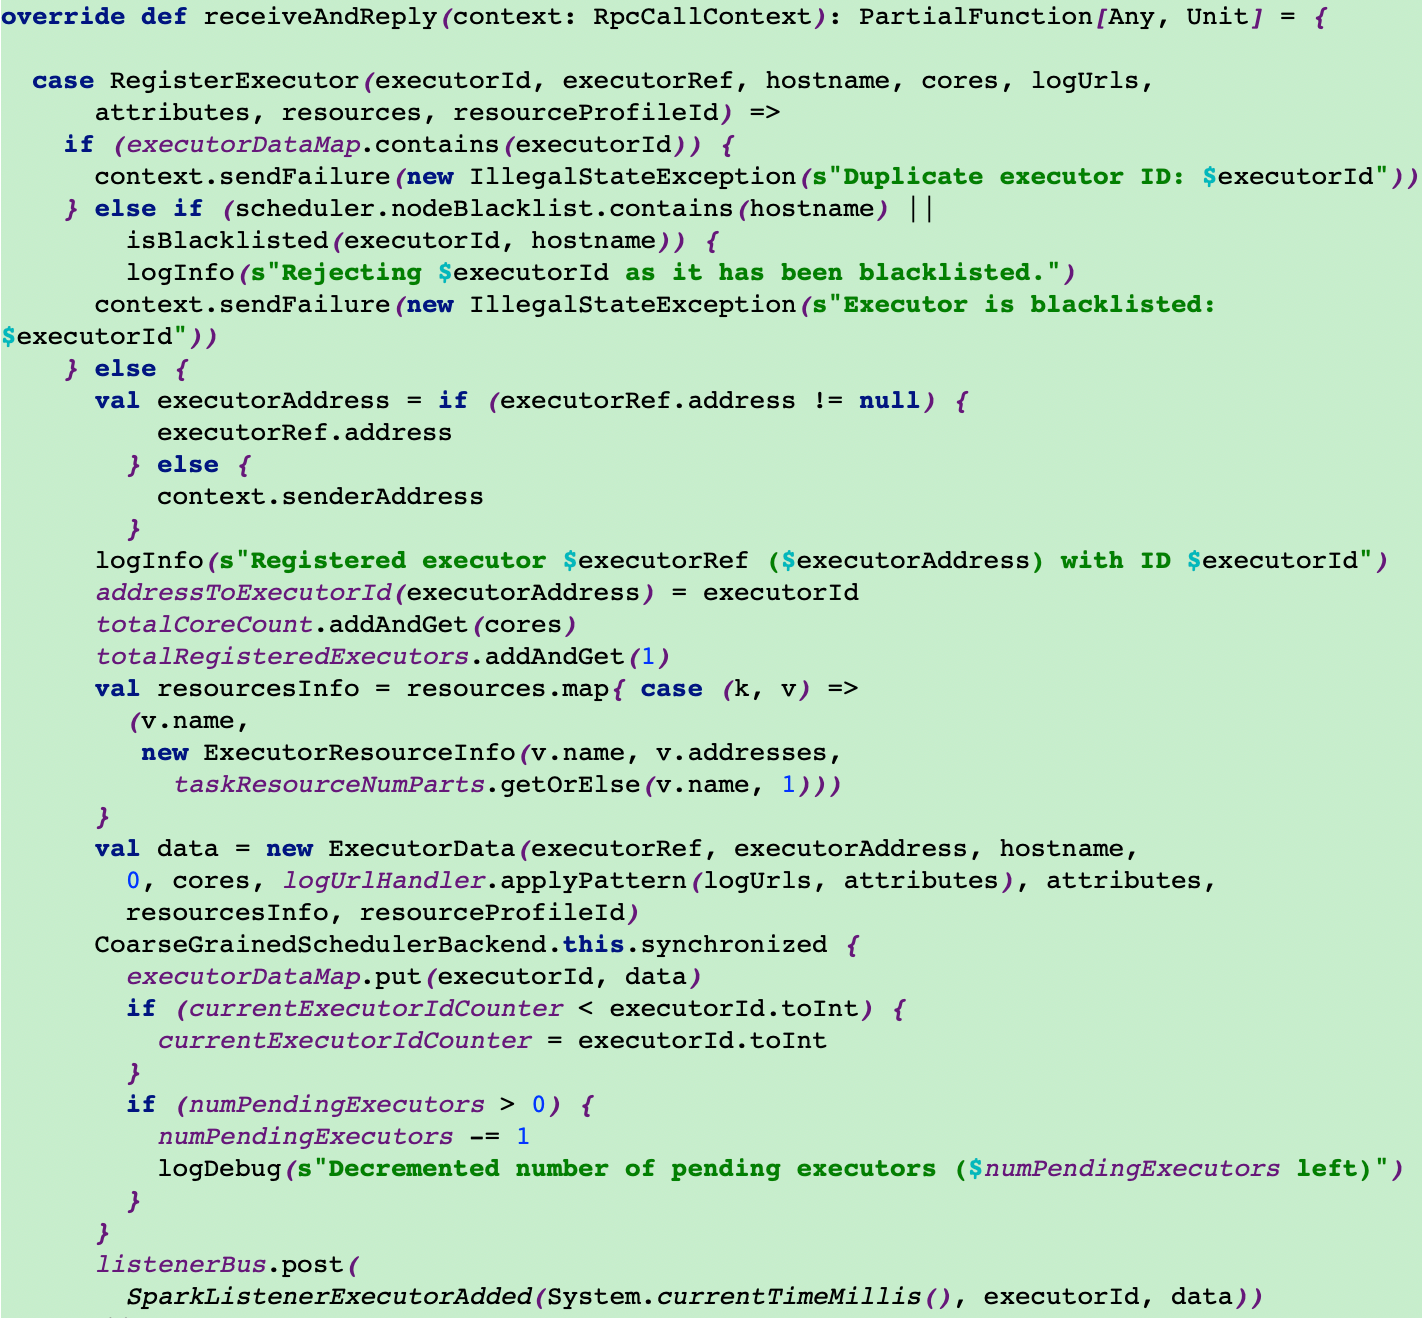
16.driver端接收
在SparkContext中有SchedulerBackend,它是一個特質,具體實現類為CoarseGrainedSchedulerBackend,該類中有一個receiveAndReply方法來對executor的註冊做回復