Spark 系列(十五)—— Spark Streaming 整合 Flume
- 2019 年 10 月 3 日
- 筆記
一、簡介
Apache Flume 是一個分散式,高可用的數據收集系統,可以從不同的數據源收集數據,經過聚合後發送到分散式計算框架或者存儲系統中。Spark Straming 提供了以下兩種方式用於 Flume 的整合。
二、推送式方法
在推送式方法 (Flume-style Push-based Approach) 中,Spark Streaming 程式需要對某台伺服器的某個埠進行監聽,Flume 通過 avro Sink 將數據源源不斷推送到該埠。這裡以監聽日誌文件為例,具體整合方式如下:
2.1 配置日誌收集Flume
新建配置 netcat-memory-avro.properties,使用 tail 命令監聽文件內容變化,然後將新的文件內容通過 avro sink 發送到 hadoop001 這台伺服器的 8888 埠:
#指定agent的sources,sinks,channels a1.sources = s1 a1.sinks = k1 a1.channels = c1 #配置sources屬性 a1.sources.s1.type = exec a1.sources.s1.command = tail -F /tmp/log.txt a1.sources.s1.shell = /bin/bash -c a1.sources.s1.channels = c1 #配置sink a1.sinks.k1.type = avro a1.sinks.k1.hostname = hadoop001 a1.sinks.k1.port = 8888 a1.sinks.k1.batch-size = 1 a1.sinks.k1.channel = c1 #配置channel類型 a1.channels.c1.type = memory a1.channels.c1.capacity = 1000 a1.channels.c1.transactionCapacity = 1002.2 項目依賴
項目採用 Maven 工程進行構建,主要依賴為 spark-streaming 和 spark-streaming-flume。
<properties> <scala.version>2.11</scala.version> <spark.version>2.4.0</spark.version> </properties> <dependencies> <!-- Spark Streaming--> <dependency> <groupId>org.apache.spark</groupId> <artifactId>spark-streaming_${scala.version}</artifactId> <version>${spark.version}</version> </dependency> <!-- Spark Streaming 整合 Flume 依賴--> <dependency> <groupId>org.apache.spark</groupId> <artifactId>spark-streaming-flume_${scala.version}</artifactId> <version>2.4.3</version> </dependency> </dependencies> 2.3 Spark Streaming接收日誌數據
調用 FlumeUtils 工具類的 createStream 方法,對 hadoop001 的 8888 埠進行監聽,獲取到流數據並進行列印:
import org.apache.spark.SparkConf import org.apache.spark.streaming.{Seconds, StreamingContext} import org.apache.spark.streaming.flume.FlumeUtils object PushBasedWordCount { def main(args: Array[String]): Unit = { val sparkConf = new SparkConf() val ssc = new StreamingContext(sparkConf, Seconds(5)) // 1.獲取輸入流 val flumeStream = FlumeUtils.createStream(ssc, "hadoop001", 8888) // 2.列印輸入流的數據 flumeStream.map(line => new String(line.event.getBody.array()).trim).print() ssc.start() ssc.awaitTermination() } }2.4 項目打包
因為 Spark 安裝目錄下是不含有 spark-streaming-flume 依賴包的,所以在提交到集群運行時候必須提供該依賴包,你可以在提交命令中使用 --jar 指定上傳到伺服器的該依賴包,或者使用 --packages org.apache.spark:spark-streaming-flume_2.12:2.4.3 指定依賴包的完整名稱,這樣程式在啟動時會先去中央倉庫進行下載。
這裡我採用的是第三種方式:使用 maven-shade-plugin 插件進行 ALL IN ONE 打包,把所有依賴的 Jar 一併打入最終包中。需要注意的是 spark-streaming 包在 Spark 安裝目錄的 jars 目錄中已經提供,所以不需要打入。插件配置如下:
<build> <plugins> <plugin> <groupId>org.apache.maven.plugins</groupId> <artifactId>maven-compiler-plugin</artifactId> <configuration> <source>8</source> <target>8</target> </configuration> </plugin> <!--使用 shade 進行打包--> <plugin> <groupId>org.apache.maven.plugins</groupId> <artifactId>maven-shade-plugin</artifactId> <configuration> <createDependencyReducedPom>true</createDependencyReducedPom> <filters> <filter> <artifact>*:*</artifact> <excludes> <exclude>META-INF/*.SF</exclude> <exclude>META-INF/*.sf</exclude> <exclude>META-INF/*.DSA</exclude> <exclude>META-INF/*.dsa</exclude> <exclude>META-INF/*.RSA</exclude> <exclude>META-INF/*.rsa</exclude> <exclude>META-INF/*.EC</exclude> <exclude>META-INF/*.ec</exclude> <exclude>META-INF/MSFTSIG.SF</exclude> <exclude>META-INF/MSFTSIG.RSA</exclude> </excludes> </filter> </filters> <artifactSet> <excludes> <exclude>org.apache.spark:spark-streaming_${scala.version}</exclude> <exclude>org.scala-lang:scala-library</exclude> <exclude>org.apache.commons:commons-lang3</exclude> </excludes> </artifactSet> </configuration> <executions> <execution> <phase>package</phase> <goals> <goal>shade</goal> </goals> <configuration> <transformers> <transformer implementation="org.apache.maven.plugins.shade.resource.ServicesResourceTransformer"/> <transformer implementation="org.apache.maven.plugins.shade.resource.ManifestResourceTransformer"> </transformer> </transformers> </configuration> </execution> </executions> </plugin> <!--打包.scala 文件需要配置此插件--> <plugin> <groupId>org.scala-tools</groupId> <artifactId>maven-scala-plugin</artifactId> <version>2.15.1</version> <executions> <execution> <id>scala-compile</id> <goals> <goal>compile</goal> </goals> <configuration> <includes> <include>**/*.scala</include> </includes> </configuration> </execution> <execution> <id>scala-test-compile</id> <goals> <goal>testCompile</goal> </goals> </execution> </executions> </plugin> </plugins> </build>本項目完整源碼見:spark-streaming-flume
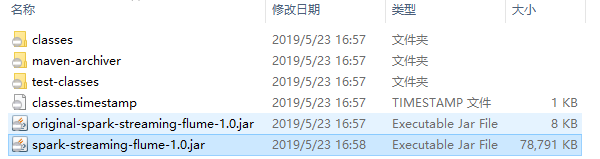
使用 mvn clean package 命令打包後會生產以下兩個 Jar 包,提交 非 original 開頭的 Jar 即可。
2.5 啟動服務和提交作業
啟動 Flume 服務:
flume-ng agent --conf conf --conf-file /usr/app/apache-flume-1.6.0-cdh5.15.2-bin/examples/netcat-memory-avro.properties --name a1 -Dflume.root.logger=INFO,console提交 Spark Streaming 作業:
spark-submit --class com.heibaiying.flume.PushBasedWordCount --master local[4] /usr/appjar/spark-streaming-flume-1.0.jar2.6 測試
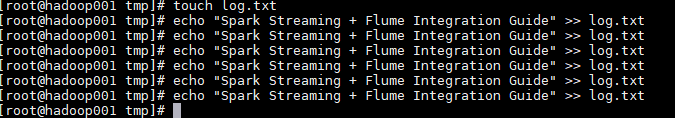
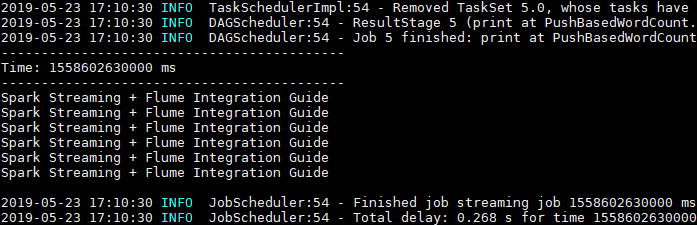
這裡使用 echo 命令模擬日誌產生的場景,往日誌文件中追加數據,然後查看程式的輸出:
Spark Streaming 程式成功接收到數據並列印輸出:
2.7 注意事項
1. 啟動順序
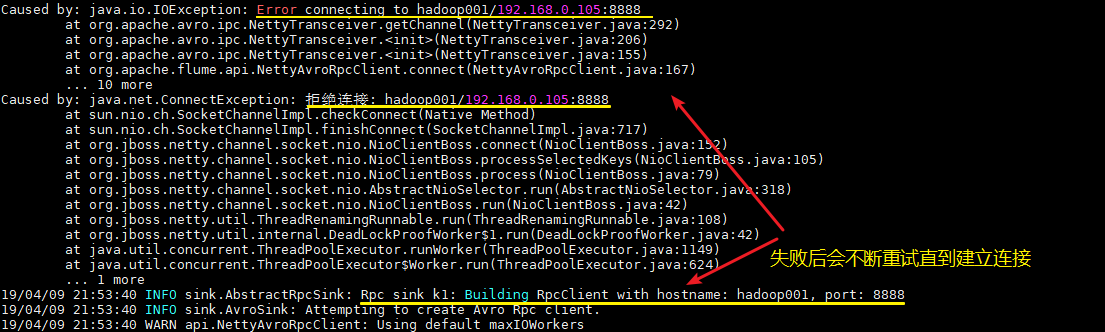
這裡需要注意的,不論你先啟動 Spark 程式還是 Flume 程式,由於兩者的啟動都需要一定的時間,此時先啟動的程式會短暫地拋出埠拒絕連接的異常,此時不需要進行任何操作,等待兩個程式都啟動完成即可。
2. 版本一致
最好保證用於本地開發和編譯的 Scala 版本和 Spark 的 Scala 版本一致,至少保證大版本一致,如都是 2.11。
三、拉取式方法
拉取式方法 (Pull-based Approach using a Custom Sink) 是將數據推送到 SparkSink 接收器中,此時數據會保持緩衝狀態,Spark Streaming 定時從接收器中拉取數據。這種方式是基於事務的,即只有在 Spark Streaming 接收和複製數據完成後,才會刪除快取的數據。與第一種方式相比,具有更強的可靠性和容錯保證。整合步驟如下:
3.1 配置日誌收集Flume
新建 Flume 配置文件 netcat-memory-sparkSink.properties,配置和上面基本一致,只是把 a1.sinks.k1.type 的屬性修改為 org.apache.spark.streaming.flume.sink.SparkSink,即採用 Spark 接收器。
#指定agent的sources,sinks,channels a1.sources = s1 a1.sinks = k1 a1.channels = c1 #配置sources屬性 a1.sources.s1.type = exec a1.sources.s1.command = tail -F /tmp/log.txt a1.sources.s1.shell = /bin/bash -c a1.sources.s1.channels = c1 #配置sink a1.sinks.k1.type = org.apache.spark.streaming.flume.sink.SparkSink a1.sinks.k1.hostname = hadoop001 a1.sinks.k1.port = 8888 a1.sinks.k1.batch-size = 1 a1.sinks.k1.channel = c1 #配置channel類型 a1.channels.c1.type = memory a1.channels.c1.capacity = 1000 a1.channels.c1.transactionCapacity = 1002.2 新增依賴
使用拉取式方法需要額外添加以下兩個依賴:
<dependency> <groupId>org.scala-lang</groupId> <artifactId>scala-library</artifactId> <version>2.12.8</version> </dependency> <dependency> <groupId>org.apache.commons</groupId> <artifactId>commons-lang3</artifactId> <version>3.5</version> </dependency>注意:添加這兩個依賴只是為了本地測試,Spark 的安裝目錄下已經提供了這兩個依賴,所以在最終打包時需要進行排除。
2.3 Spark Streaming接收日誌數據
這裡和上面推送式方法的程式碼基本相同,只是將調用方法改為 createPollingStream。
import org.apache.spark.SparkConf import org.apache.spark.streaming.{Seconds, StreamingContext} import org.apache.spark.streaming.flume.FlumeUtils object PullBasedWordCount { def main(args: Array[String]): Unit = { val sparkConf = new SparkConf() val ssc = new StreamingContext(sparkConf, Seconds(5)) // 1.獲取輸入流 val flumeStream = FlumeUtils.createPollingStream(ssc, "hadoop001", 8888) // 2.列印輸入流中的數據 flumeStream.map(line => new String(line.event.getBody.array()).trim).print() ssc.start() ssc.awaitTermination() } }2.4 啟動測試
啟動和提交作業流程與上面相同,這裡給出執行腳本,過程不再贅述。
啟動 Flume 進行日誌收集:
flume-ng agent --conf conf --conf-file /usr/app/apache-flume-1.6.0-cdh5.15.2-bin/examples/netcat-memory-sparkSink.properties --name a1 -Dflume.root.logger=INFO,console提交 Spark Streaming 作業:
spark-submit --class com.heibaiying.flume.PullBasedWordCount --master local[4] /usr/appjar/spark-streaming-flume-1.0.jar參考資料
- streaming-flume-integration
- 關於大數據應用常用的打包方式可以參見:大數據應用常用打包方式
更多大數據系列文章可以參見 GitHub 開源項目: 大數據入門指南